What Does "5.0 TOPS NPU" Mean?
TOPS stands for Trillion Operations Per Second, and it is the standard unit used to express the throughput of a Neural Processing Unit (NPU) — a dedicated accelerator built into modern processors specifically to run artificial intelligence and machine learning workloads. An NPU rated at 5.0 TOPS can perform roughly five trillion low-precision (typically INT8) operations every second, and it does so far more efficiently than a general-purpose CPU core running the same model.
The key advantage of an NPU is not raw speed alone, but efficiency. AI inference — the process of running a trained model on live data — is repetitive and highly parallel, which is a poor fit for CPU architectures. By offloading that work to an NPU, the CPU stays free for the application logic, the system draws less power, and it generates less heat. This matters enormously in fanless and sealed industrial enclosures where there is no airflow to carry heat away.
Typical Workloads for a 5 TOPS-Class NPU
A 5 TOPS NPU comfortably handles edge inference rather than model training. Representative workloads include:
| Workload | What the NPU Does | Typical Latency |
|---|---|---|
| Object detection | Identifies people, vehicles, defects in video frames | 10–40 ms per frame |
| Pose and gesture recognition | Tracks body keypoints for safety or interaction | 15–50 ms |
| OCR and barcode reading | Extracts text from labels, plates, documents | 20–80 ms |
| Anomaly detection | Flags abnormal vibration, sound or image patterns | sub-second |
| Keyword spotting | Wake-word and voice command detection | continuous |
| Predictive maintenance | Runs small regression/classification models on sensor data | sub-second |
Models are usually deployed in quantised formats such as INT8, OpenVINO IR, ONNX or TensorFlow Lite, which is exactly what the INT8 TOPS figure describes. Larger models such as vision transformers can run, but at reduced frame rates.
Why NPUs Matter in Industrial and Embedded Systems
Industrial deployments increasingly need local intelligence: a production line camera that rejects defective parts, a gate that recognises authorised personnel, a kiosk that responds to voice, or a pump that predicts its own failure. Sending that video or sensor stream to the cloud introduces bandwidth cost, latency and — critically — data governance problems.
Running inference locally on a 5 TOPS NPU solves all three. It also means the system keeps working when the network drops, which is often a hard requirement in factories, utilities, warehouses and remote sites. Combined with a fanless industrial PC, an NPU-equipped system can sit in a dusty cabinet or a hot control room and run vision models continuously for years.
What to Look For Beyond the TOPS Number
TOPS is a headline figure, but several other factors decide real-world AI performance:
-
Precision support — INT8 throughput is what "5.0 TOPS" usually refers to; FP16 and INT4 support affect which models you can run.
-
Software stack — driver and toolkit maturity (OpenVINO, ONNX Runtime, DirectML) matters more than the marketing number.
-
Memory bandwidth — inference is often memory-bound, so dual-channel DDR4/DDR5 helps.
-
Thermal design — a fanless chassis must dissipate the NPU's heat along with the CPU's.
-
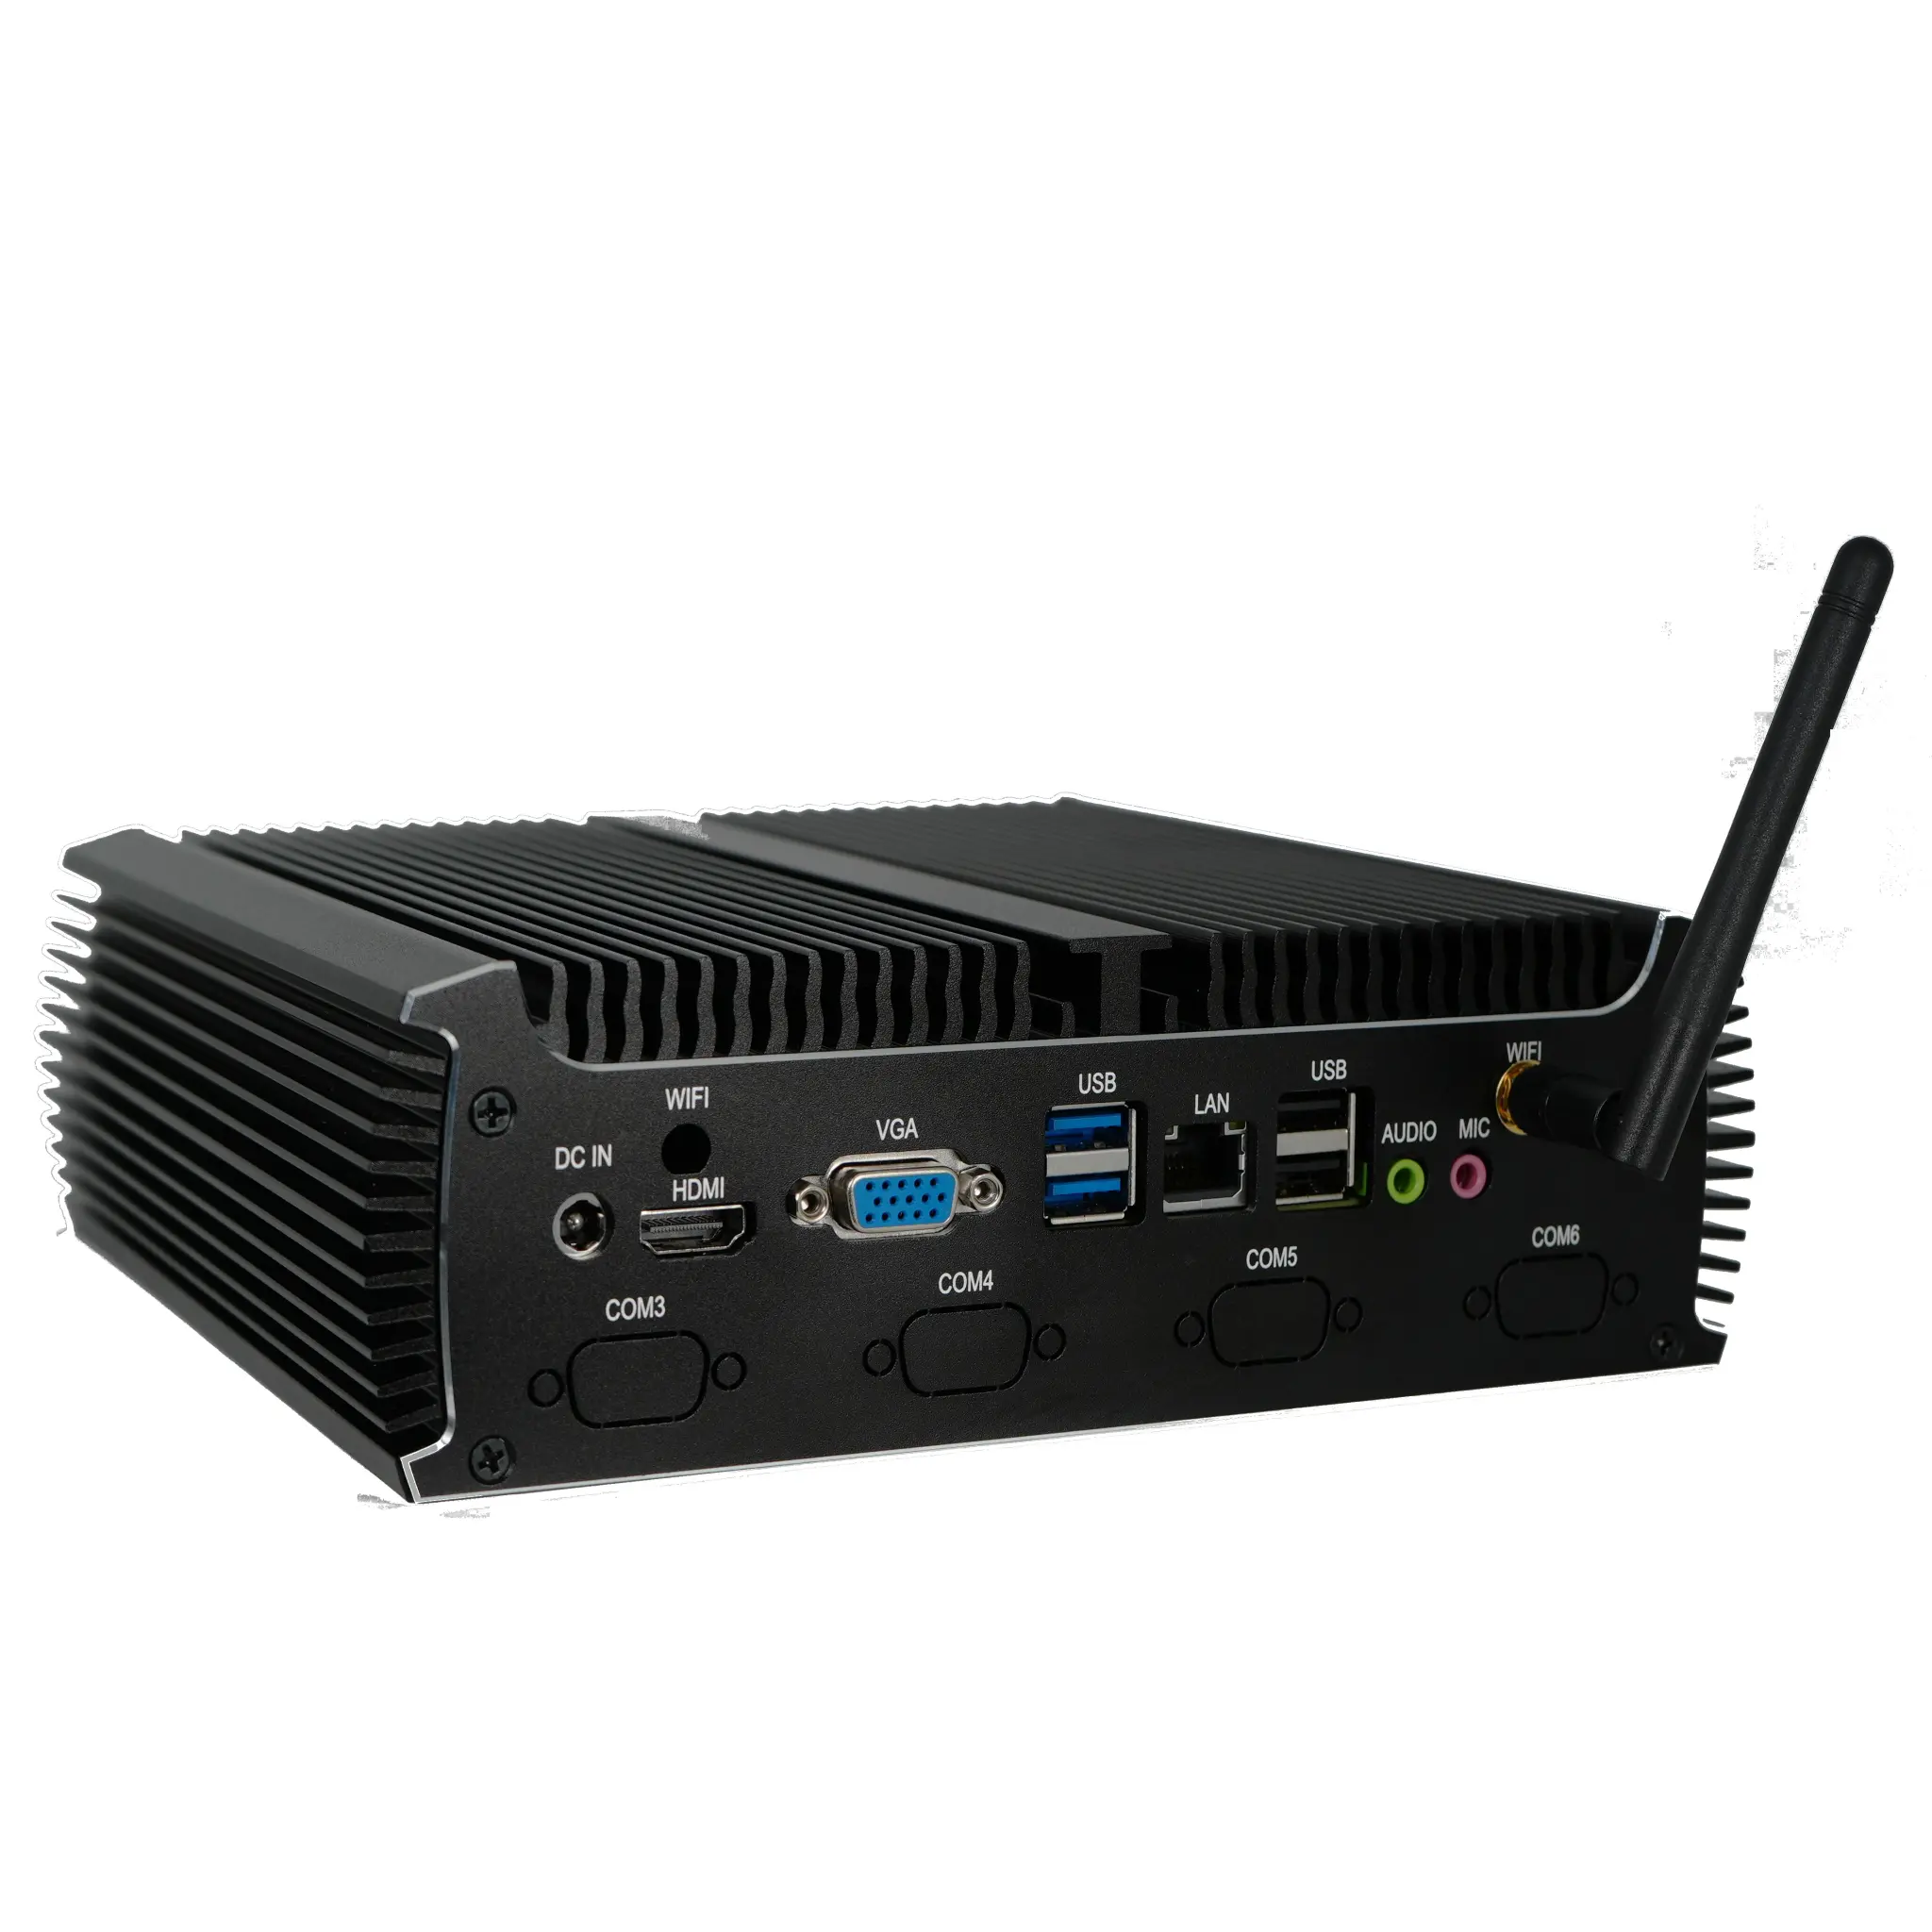
I/O for cameras — multiple Gigabit Ethernet ports, USB 3.2 and HDMI outputs determine how many streams you can ingest.
Thinvent Products Featuring This Technology
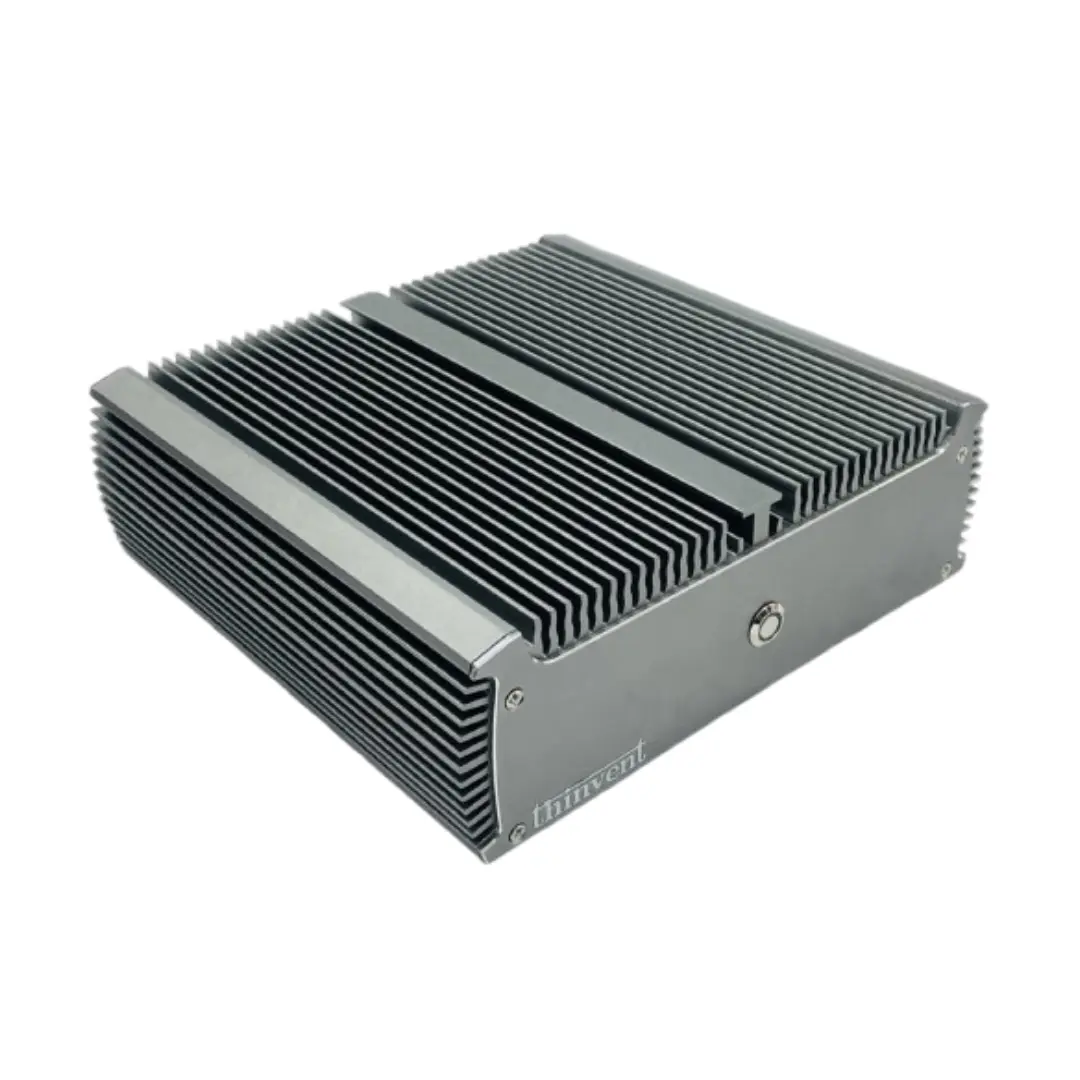
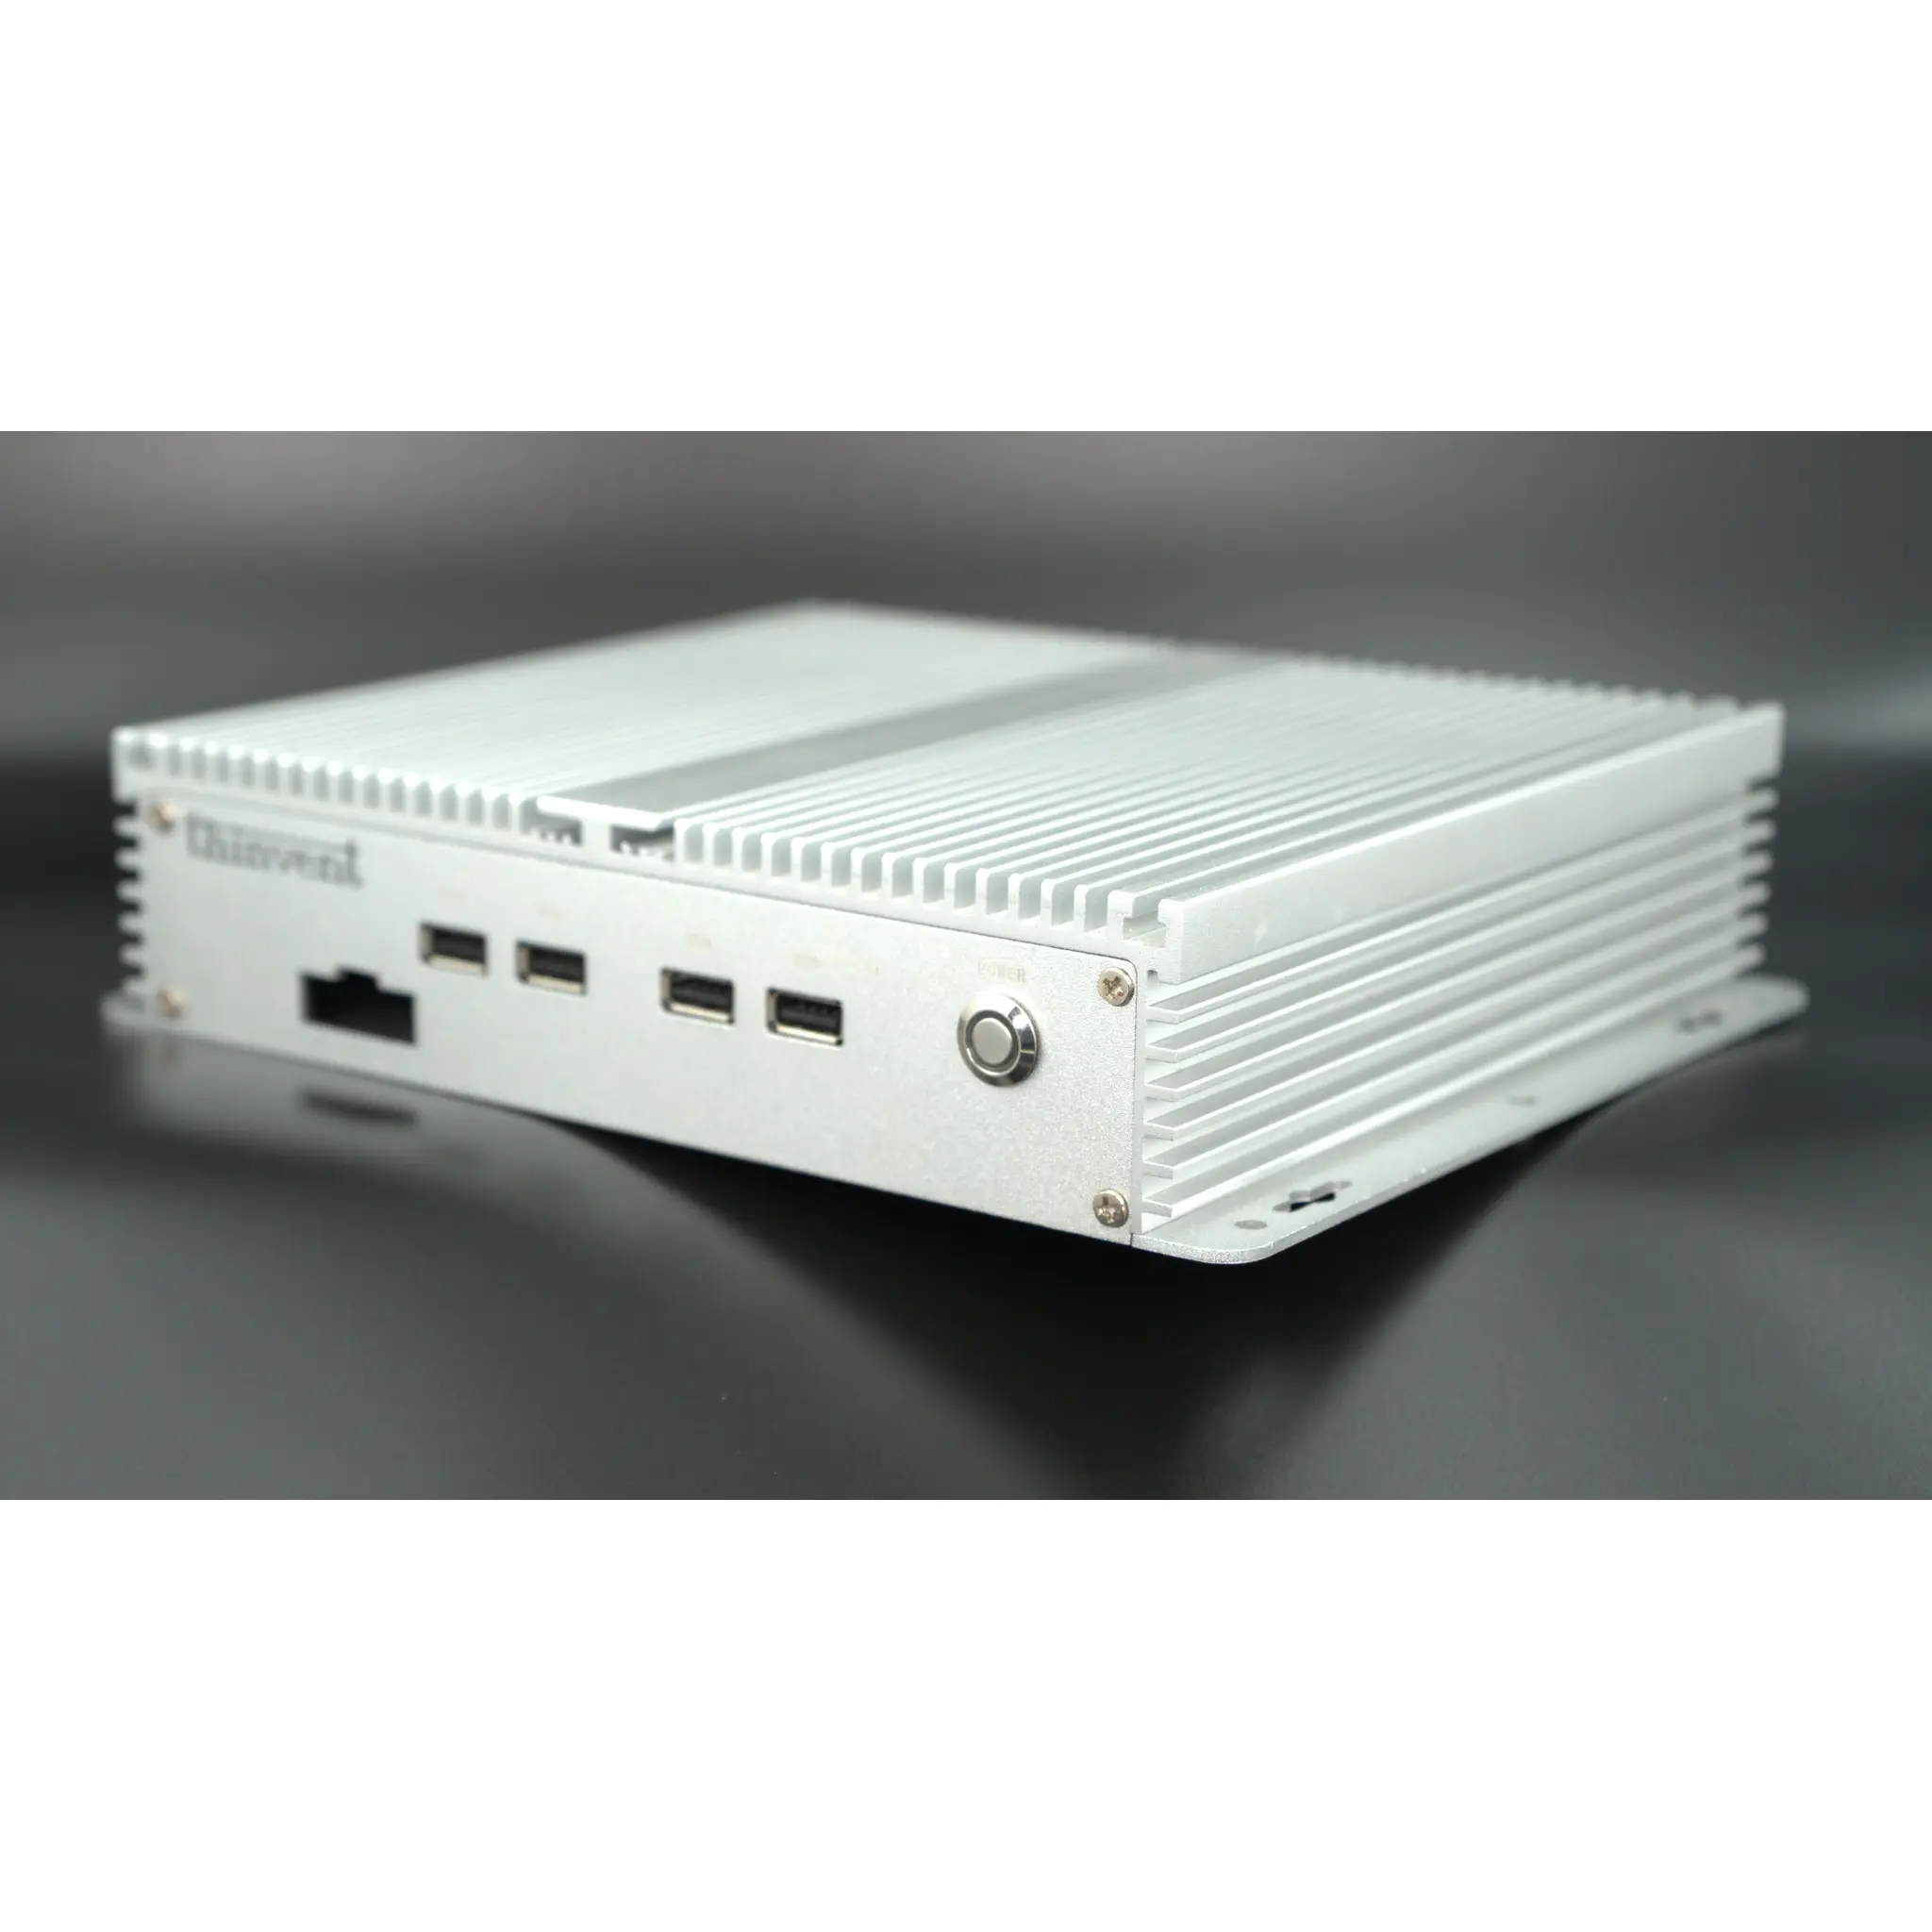
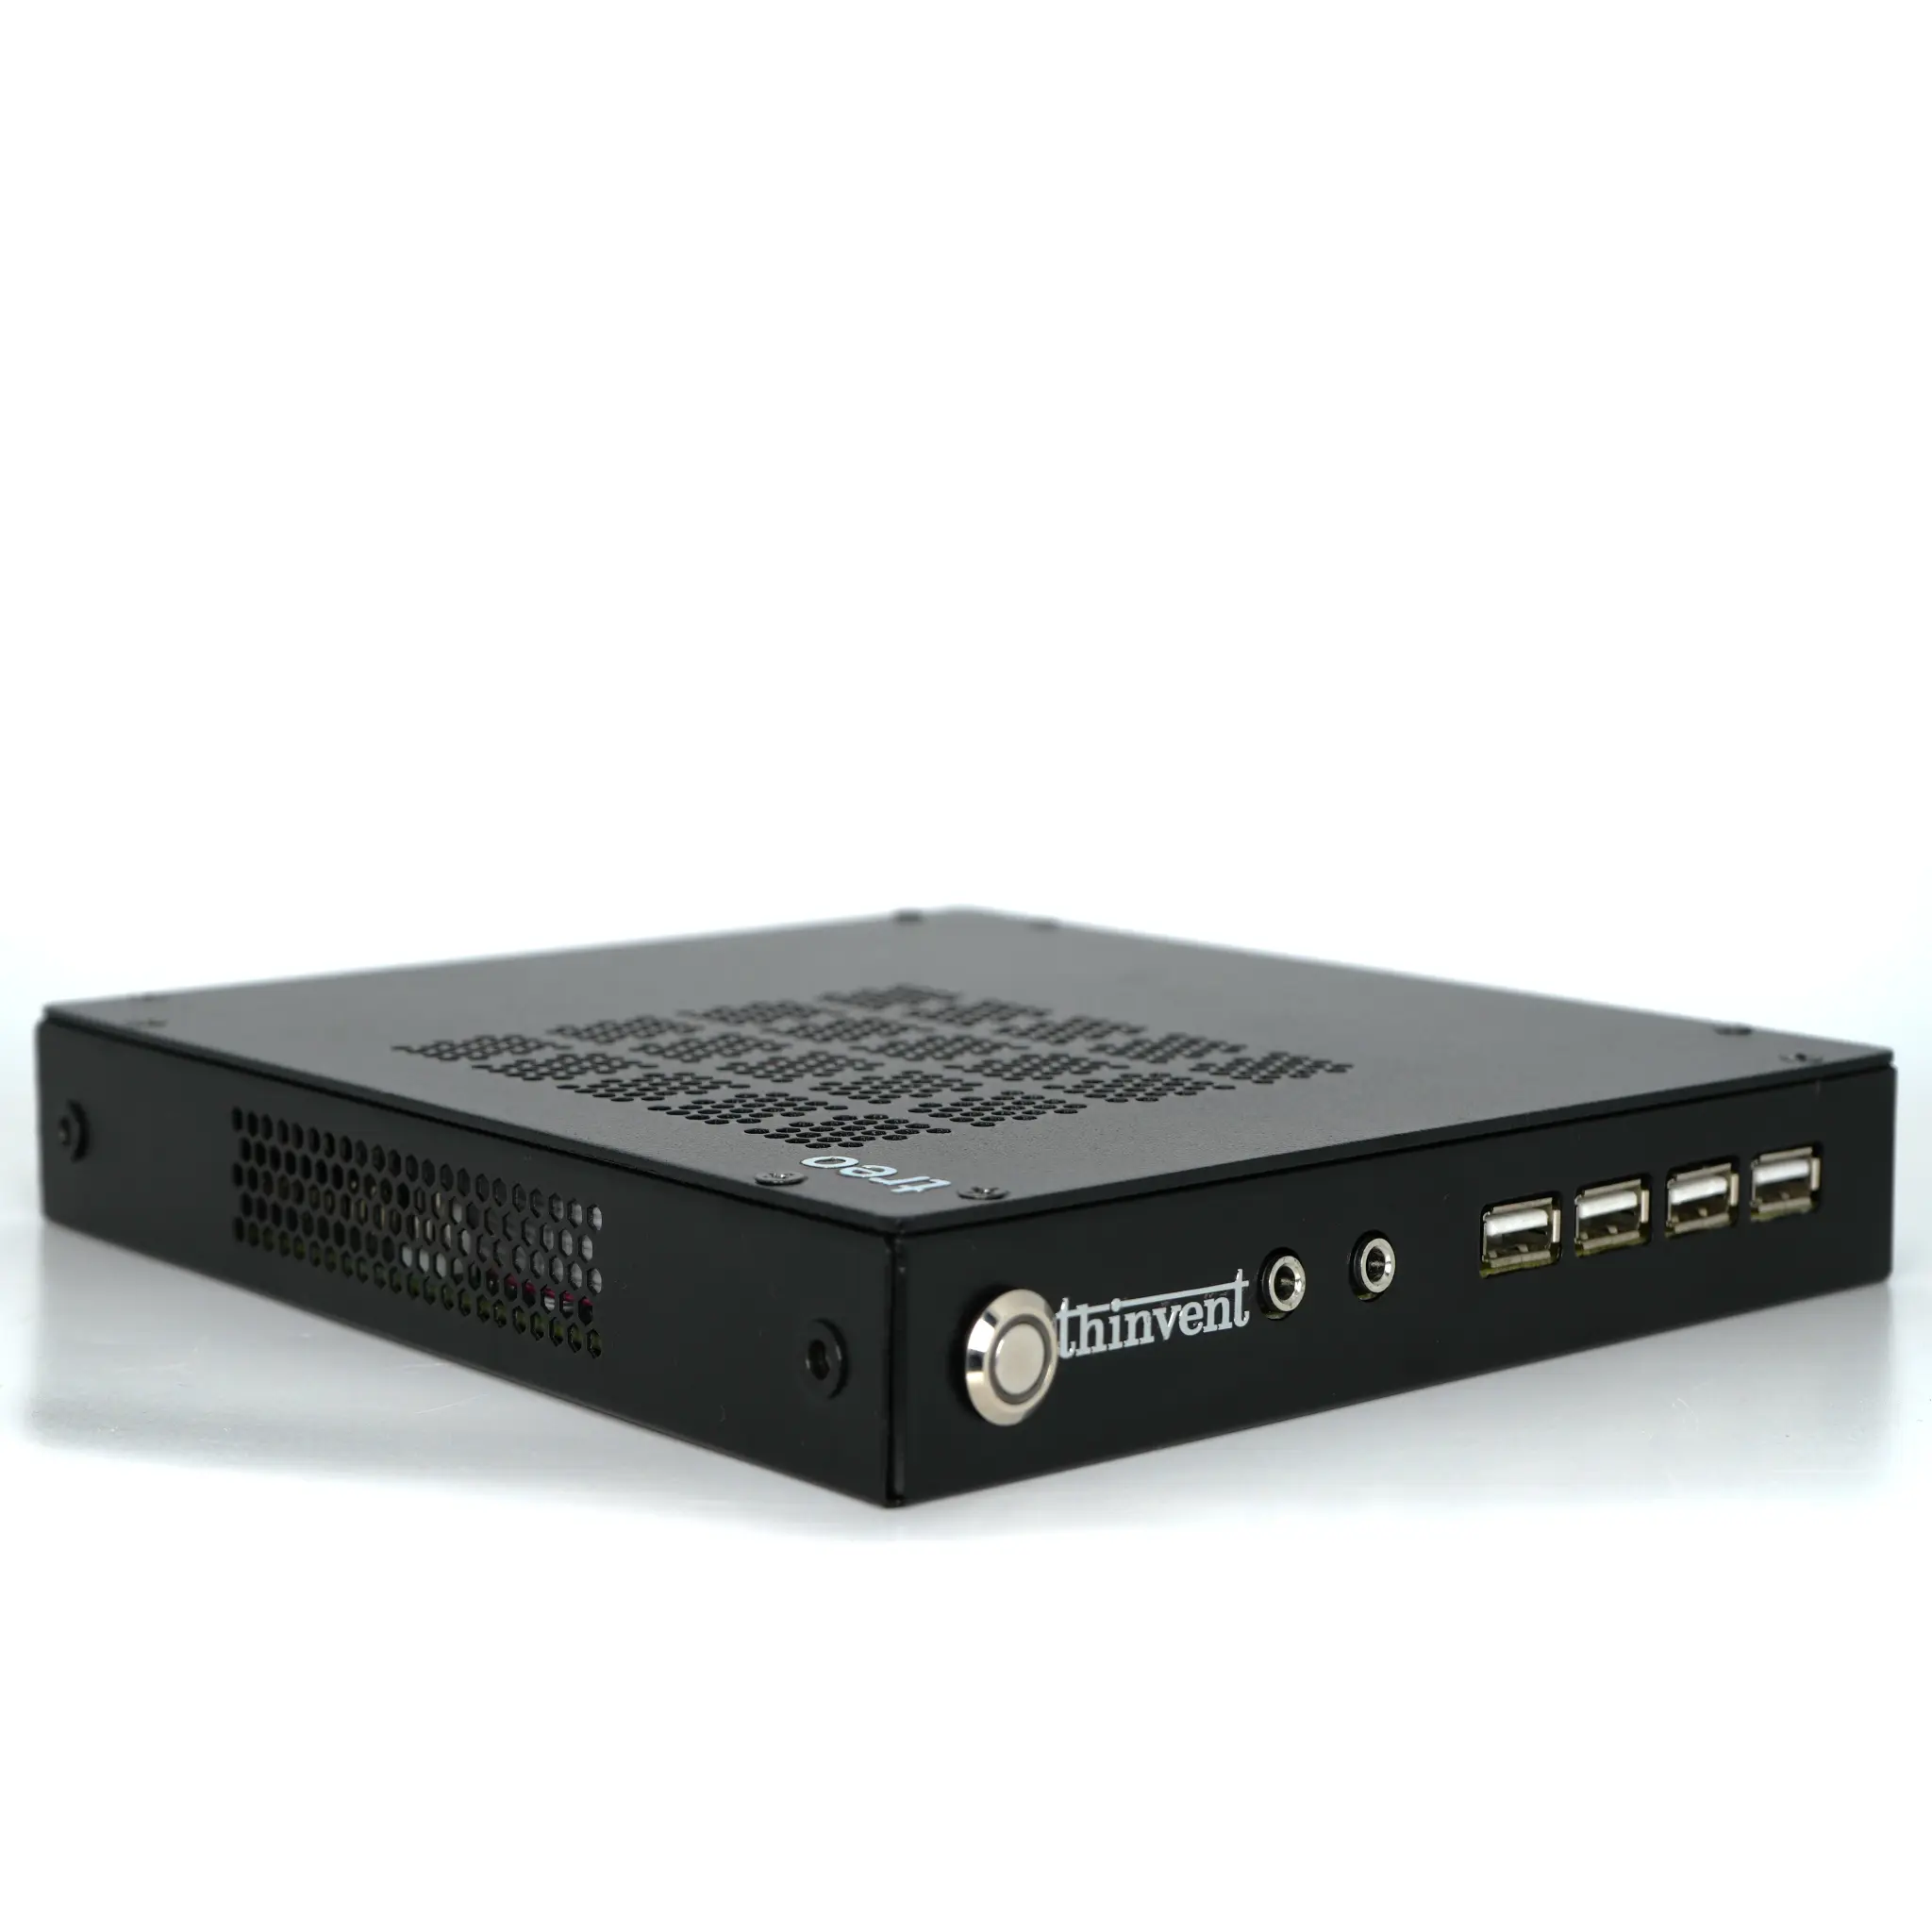
Thinvent's industrial computers, mini PCs and all-in-one systems are built around Intel Core and Intel N-series processors that integrate on-die AI acceleration, and are available in fanless, sealed chassis designed for continuous duty in dust, heat and vibration. Configurations range from compact mini PCs for kiosk and digital signage inference, through industrial PCs with dual Gigabit Ethernet and multiple serial ports for machine-vision and factory-floor deployments, up to all-in-one panel PCs for operator stations and smart terminals. Thinvent systems ship with Windows 11 Pro, Windows 11 IoT, Ubuntu Linux or Thinux embedded Linux, so you can deploy OpenVINO, ONNX Runtime or TensorFlow Lite pipelines on the platform that fits your stack.