Powerful Desktops for Running Local LLMs
Running Large Language Models (LLMs) locally demands significant computing resources, particularly a powerful CPU, ample RAM, and fast storage. While many tasks can be handled by standard desktops, local LLM inference requires a machine built for heavy computational loads. Key specifications to consider include a high core count processor for parallel processing, a substantial amount of RAM to load model parameters, and a fast SSD for quick data access.
For effective local LLM execution, processors with higher core counts and clock speeds are preferred to accelerate the complex calculations involved. Memory capacity is critical; models can range from a few gigabytes to tens of gigabytes, necessitating sufficient RAM to load them entirely into memory for efficient processing. Fast NVMe SSDs are crucial for loading models and datasets rapidly, minimizing wait times during inference.
Common use cases for local LLMs include:
-
Code generation and assistance: Generating code snippets, debugging, and offering programming advice.
-
Content creation: Drafting articles, marketing copy, creative writing, and summarizing text.
-
Personal AI assistants: Building custom chatbots and interactive AI agents for specific tasks.
-
Data analysis and summarization: Processing and extracting insights from large datasets.
To ensure smooth performance, aim for systems with at least an Intel Core i5 or equivalent processor, 16GB of RAM (with 32GB or more being ideal for larger models), and a 512GB SSD or larger.
Thinvent Desktops for Local LLM Processing
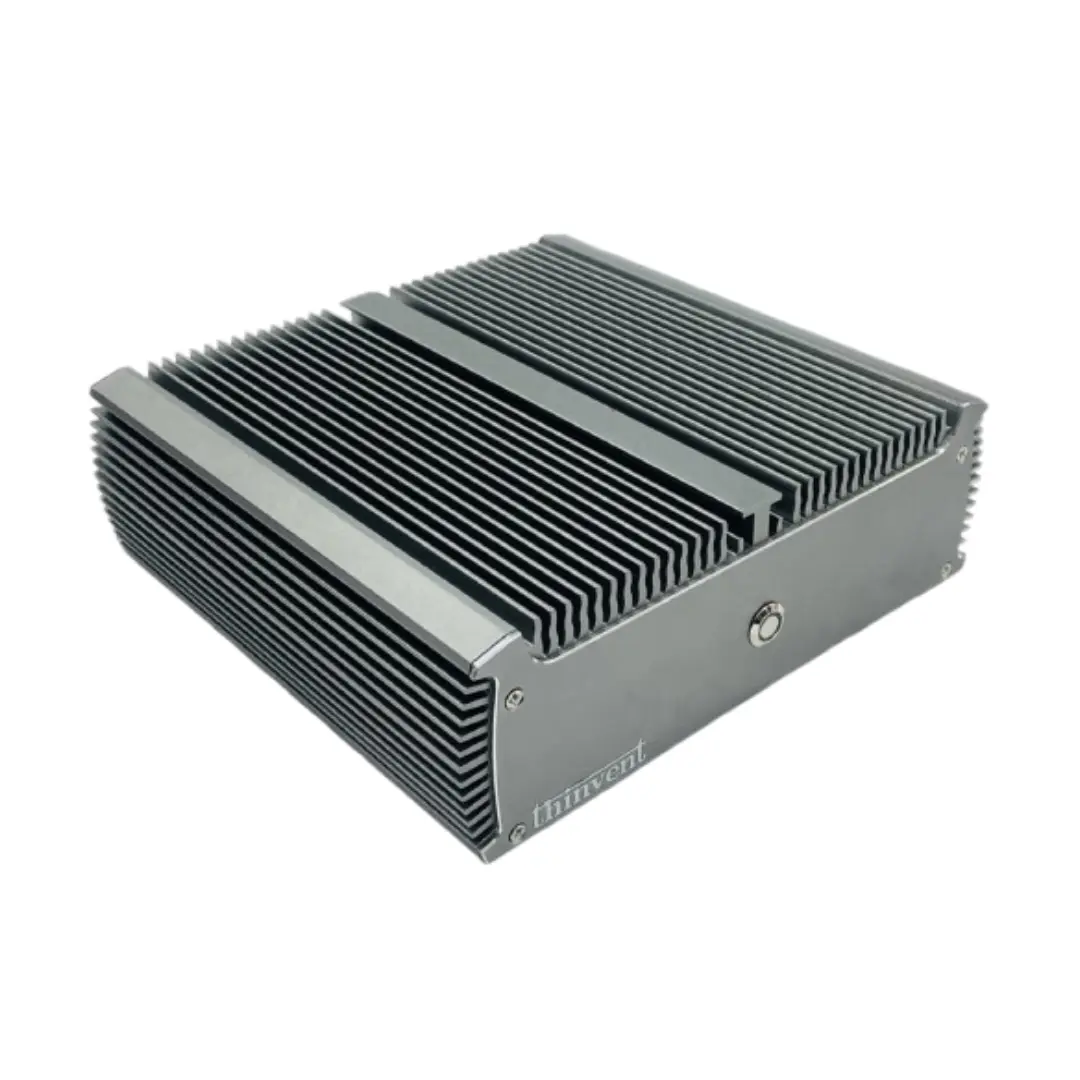
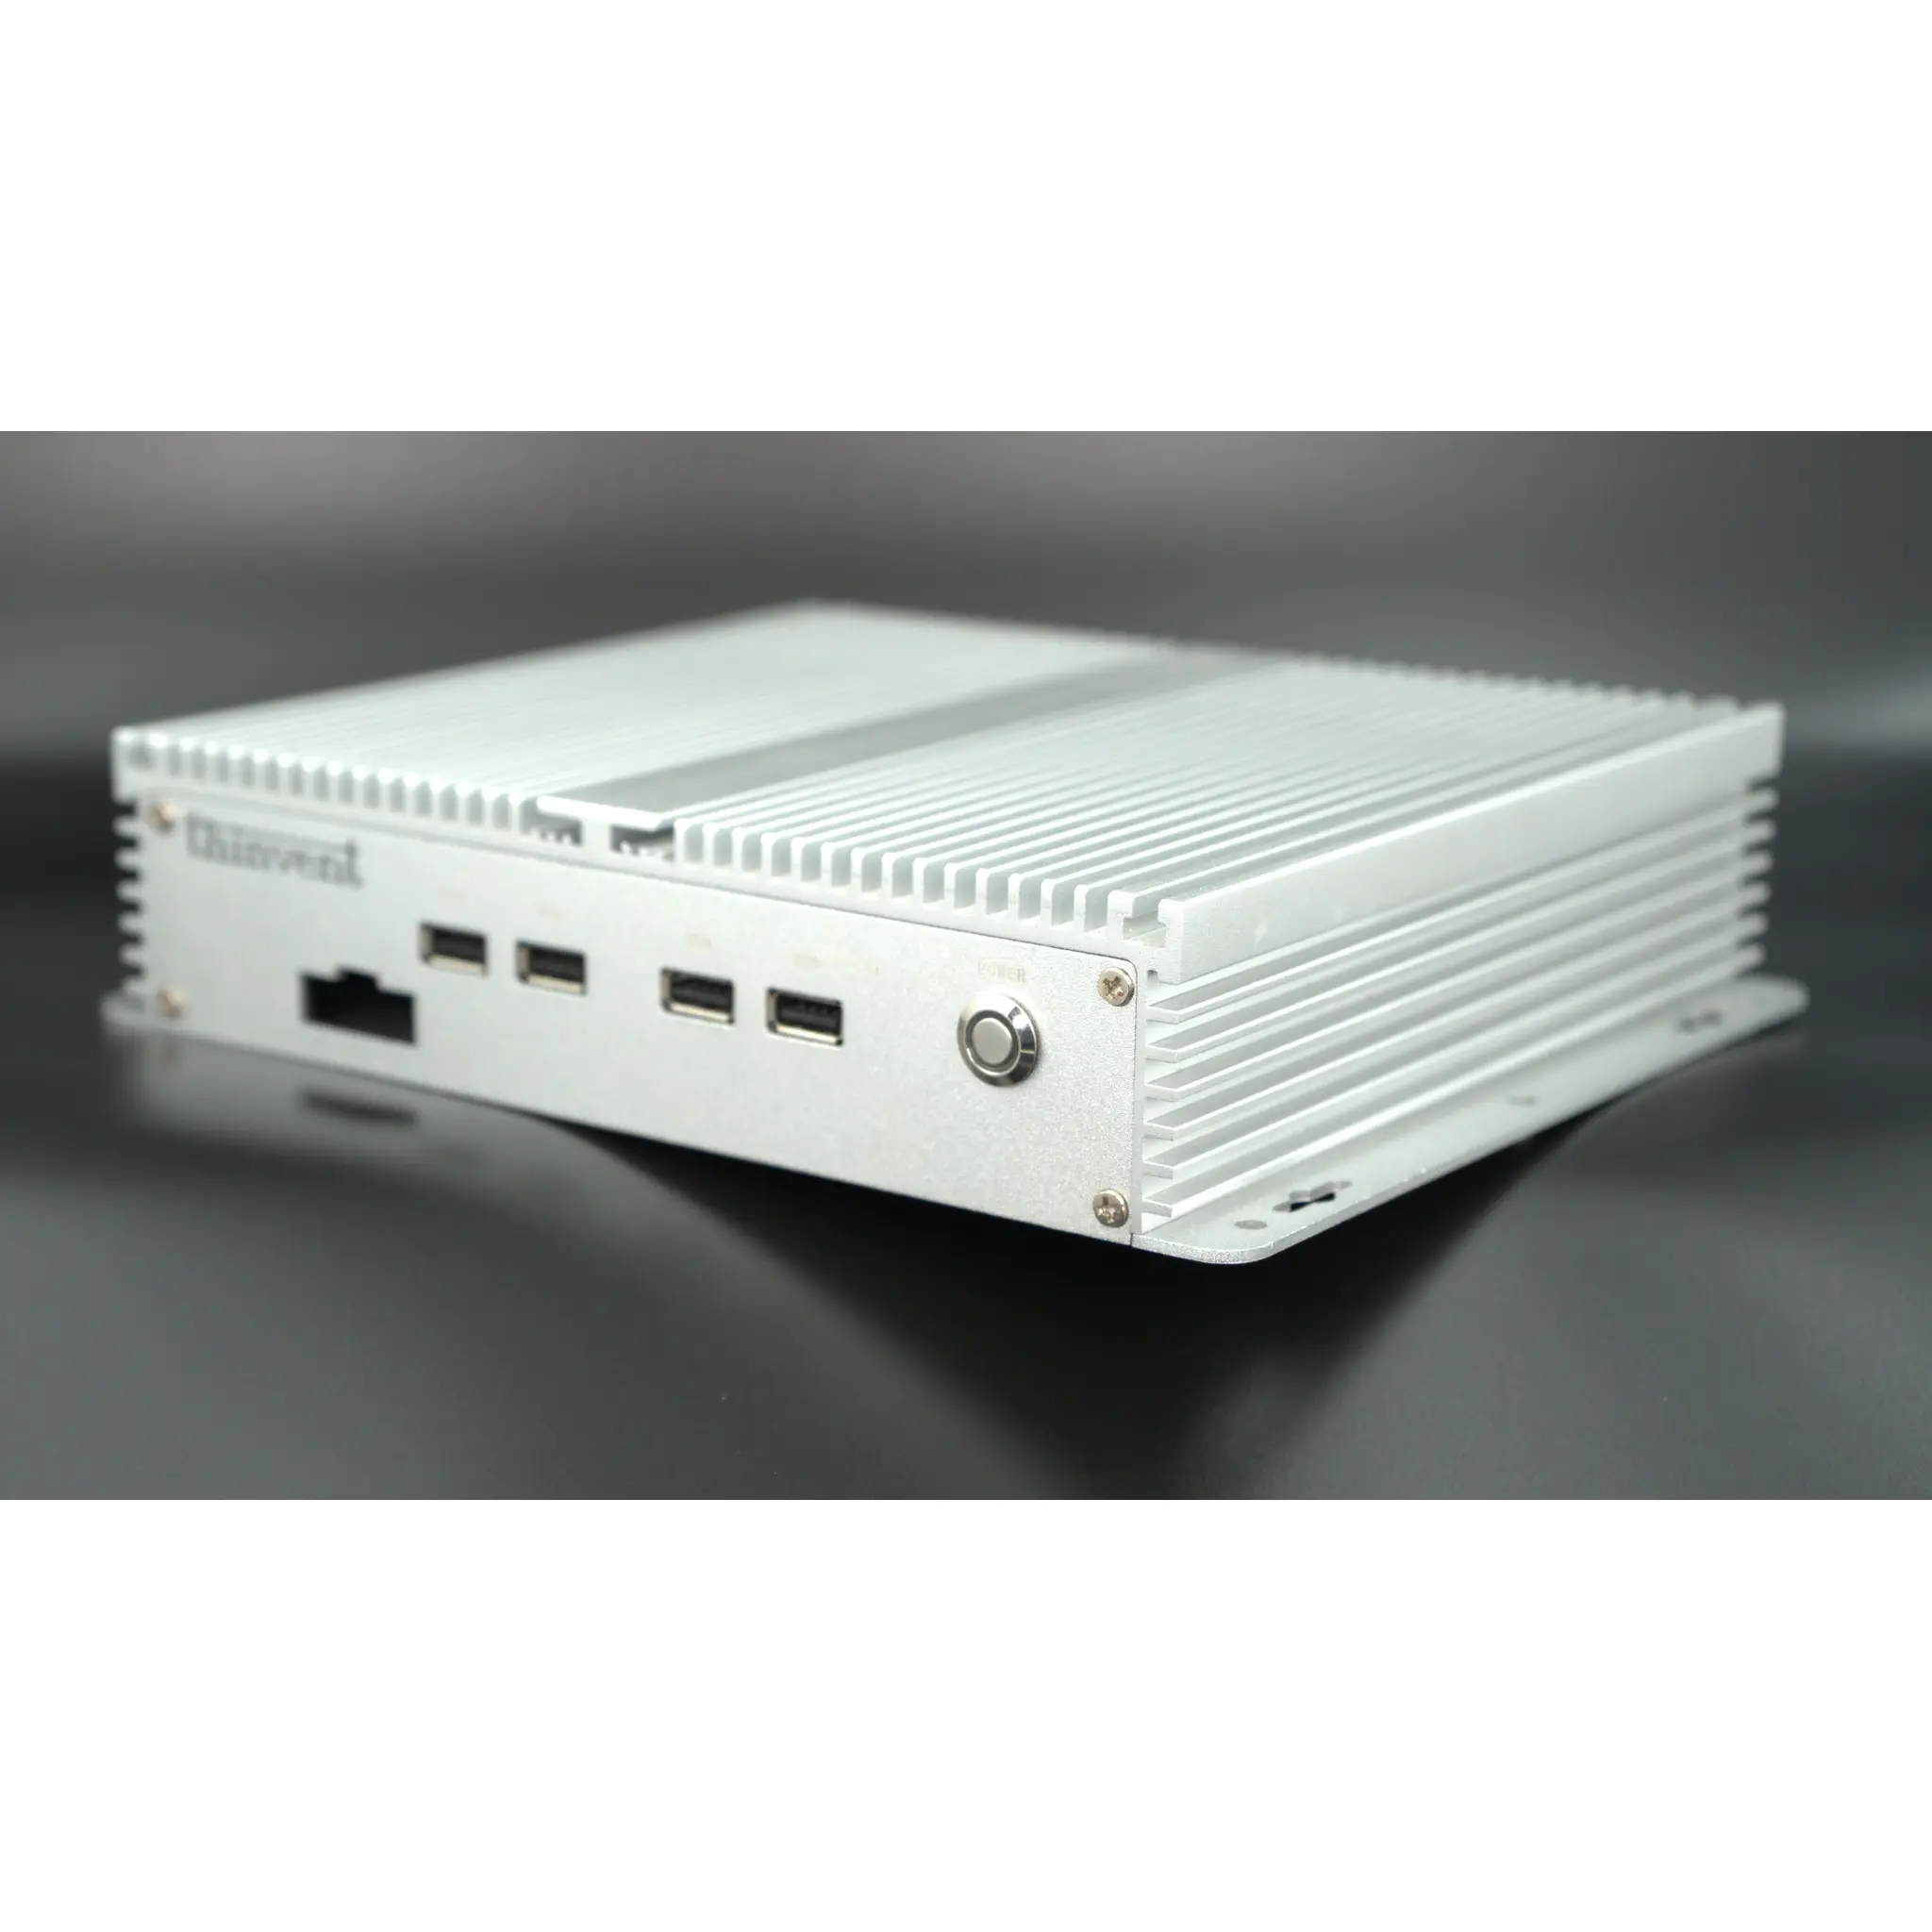
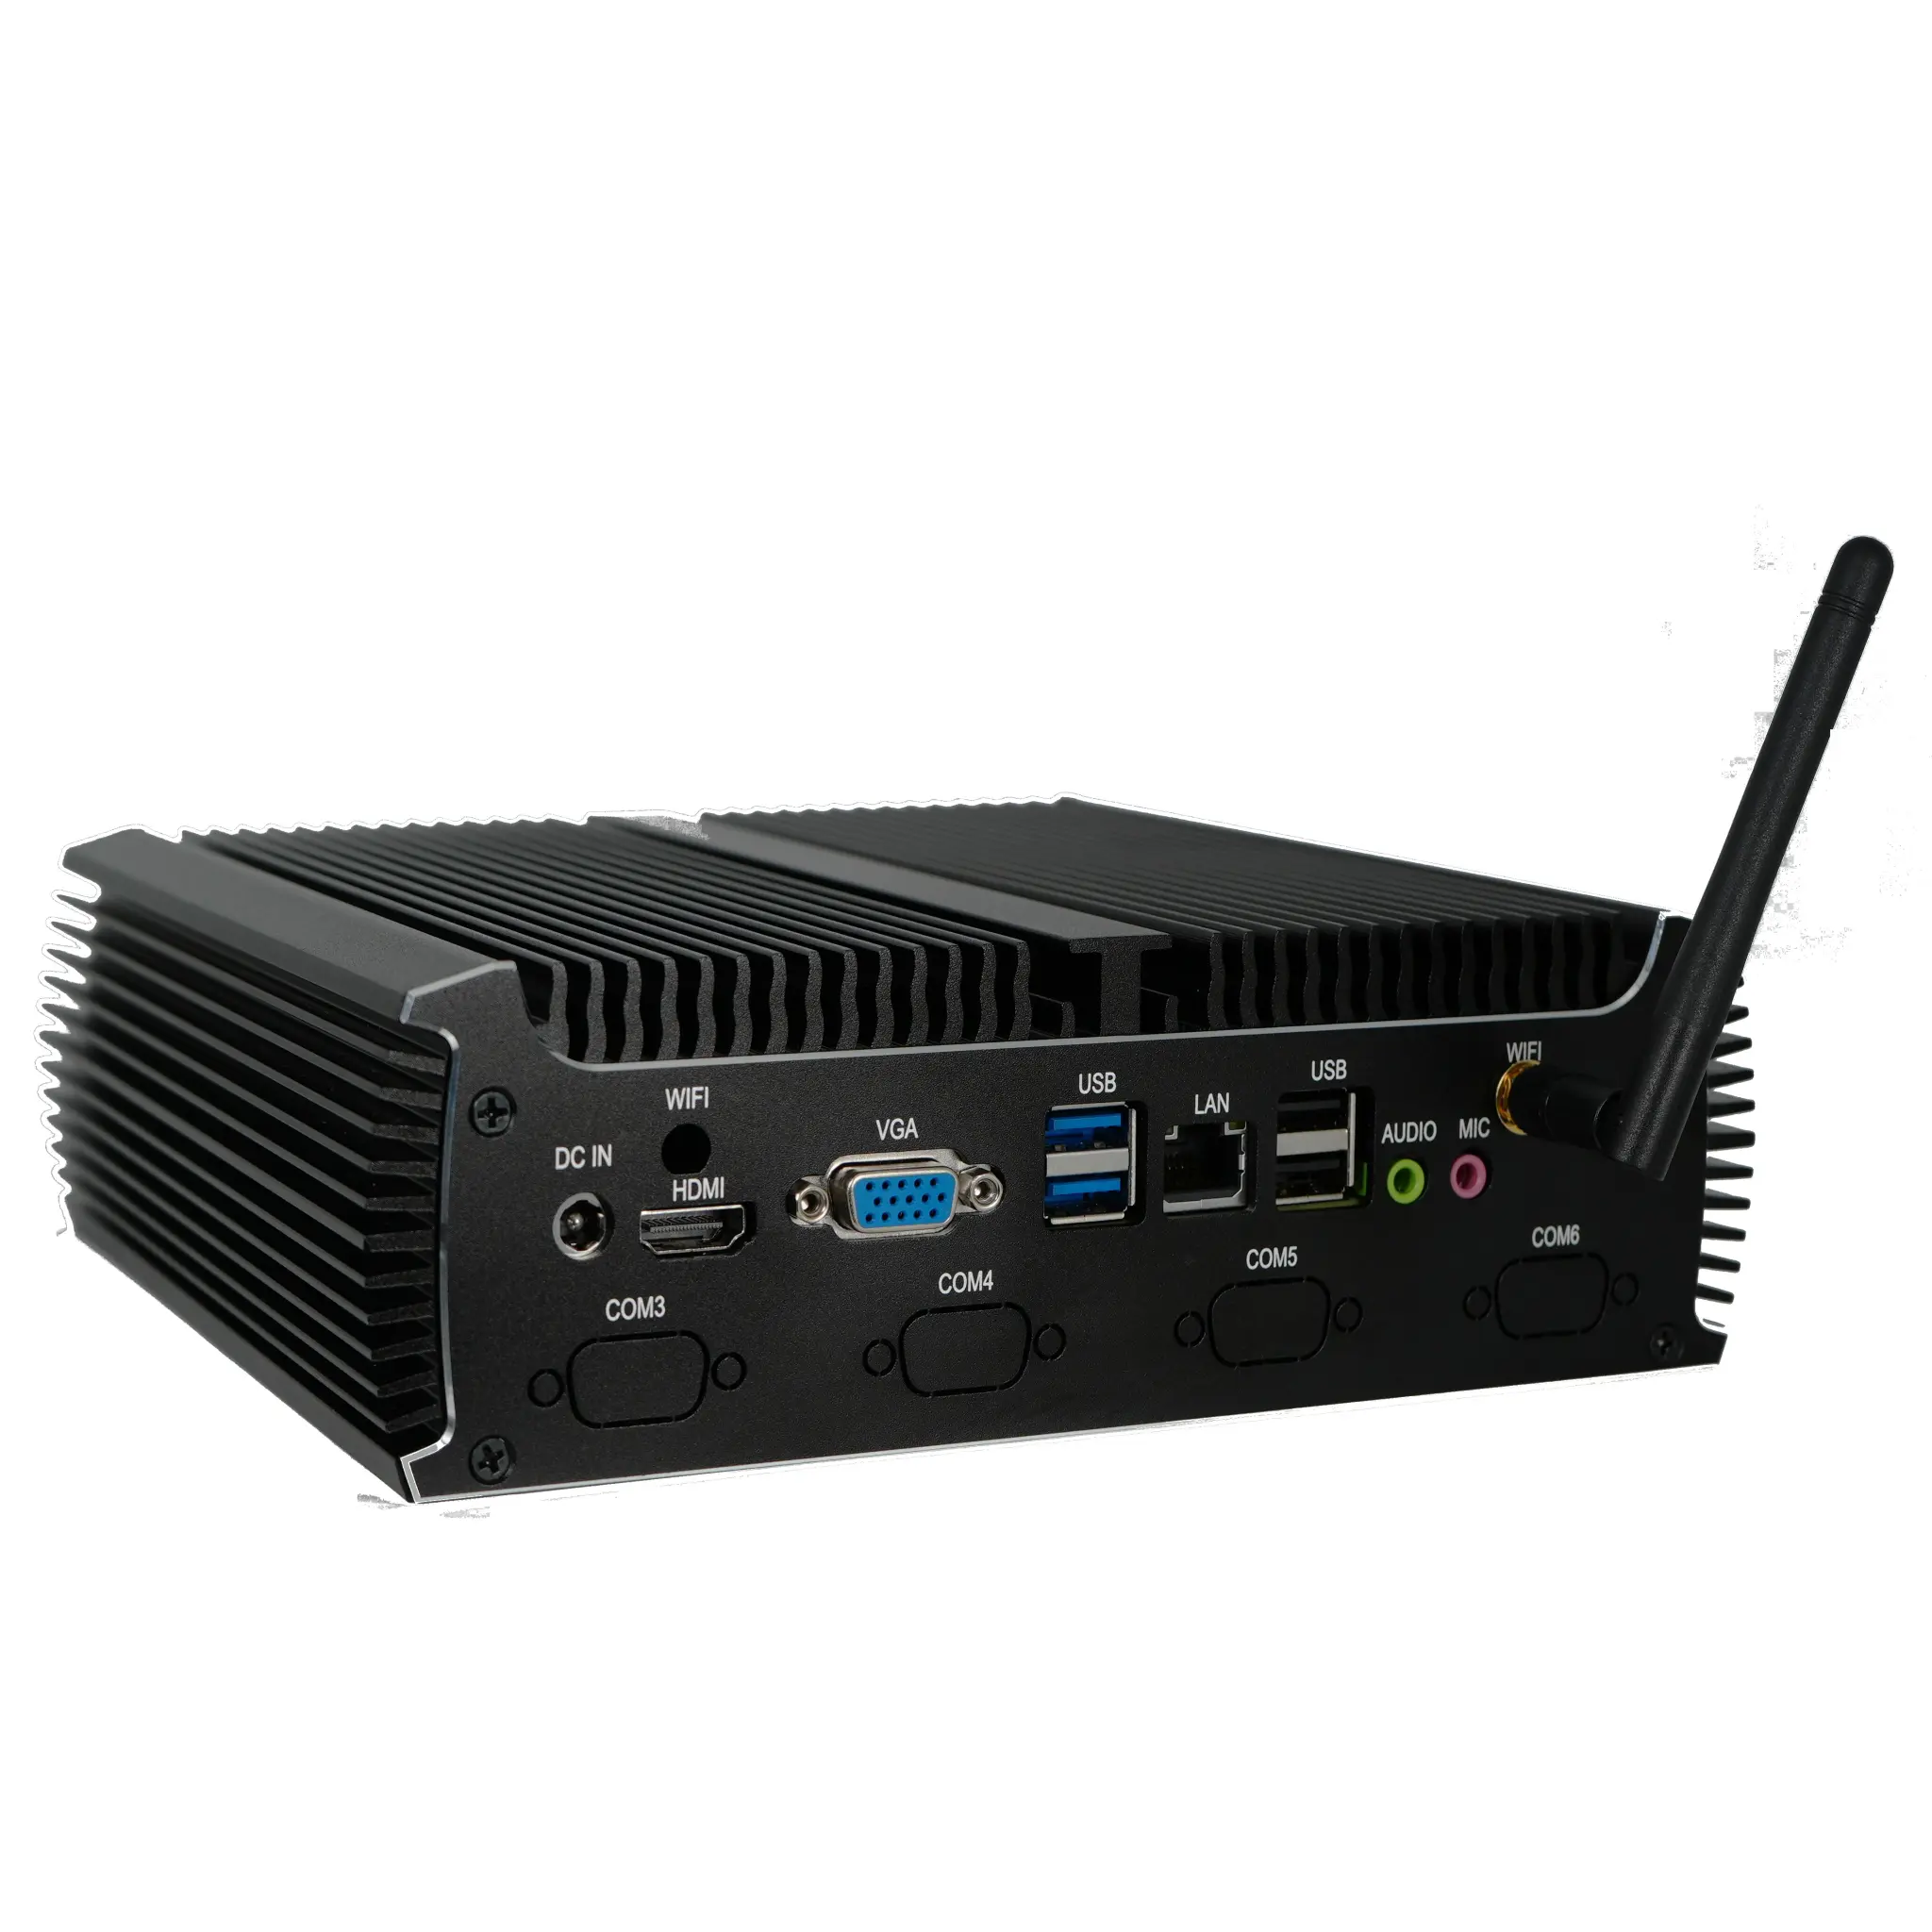
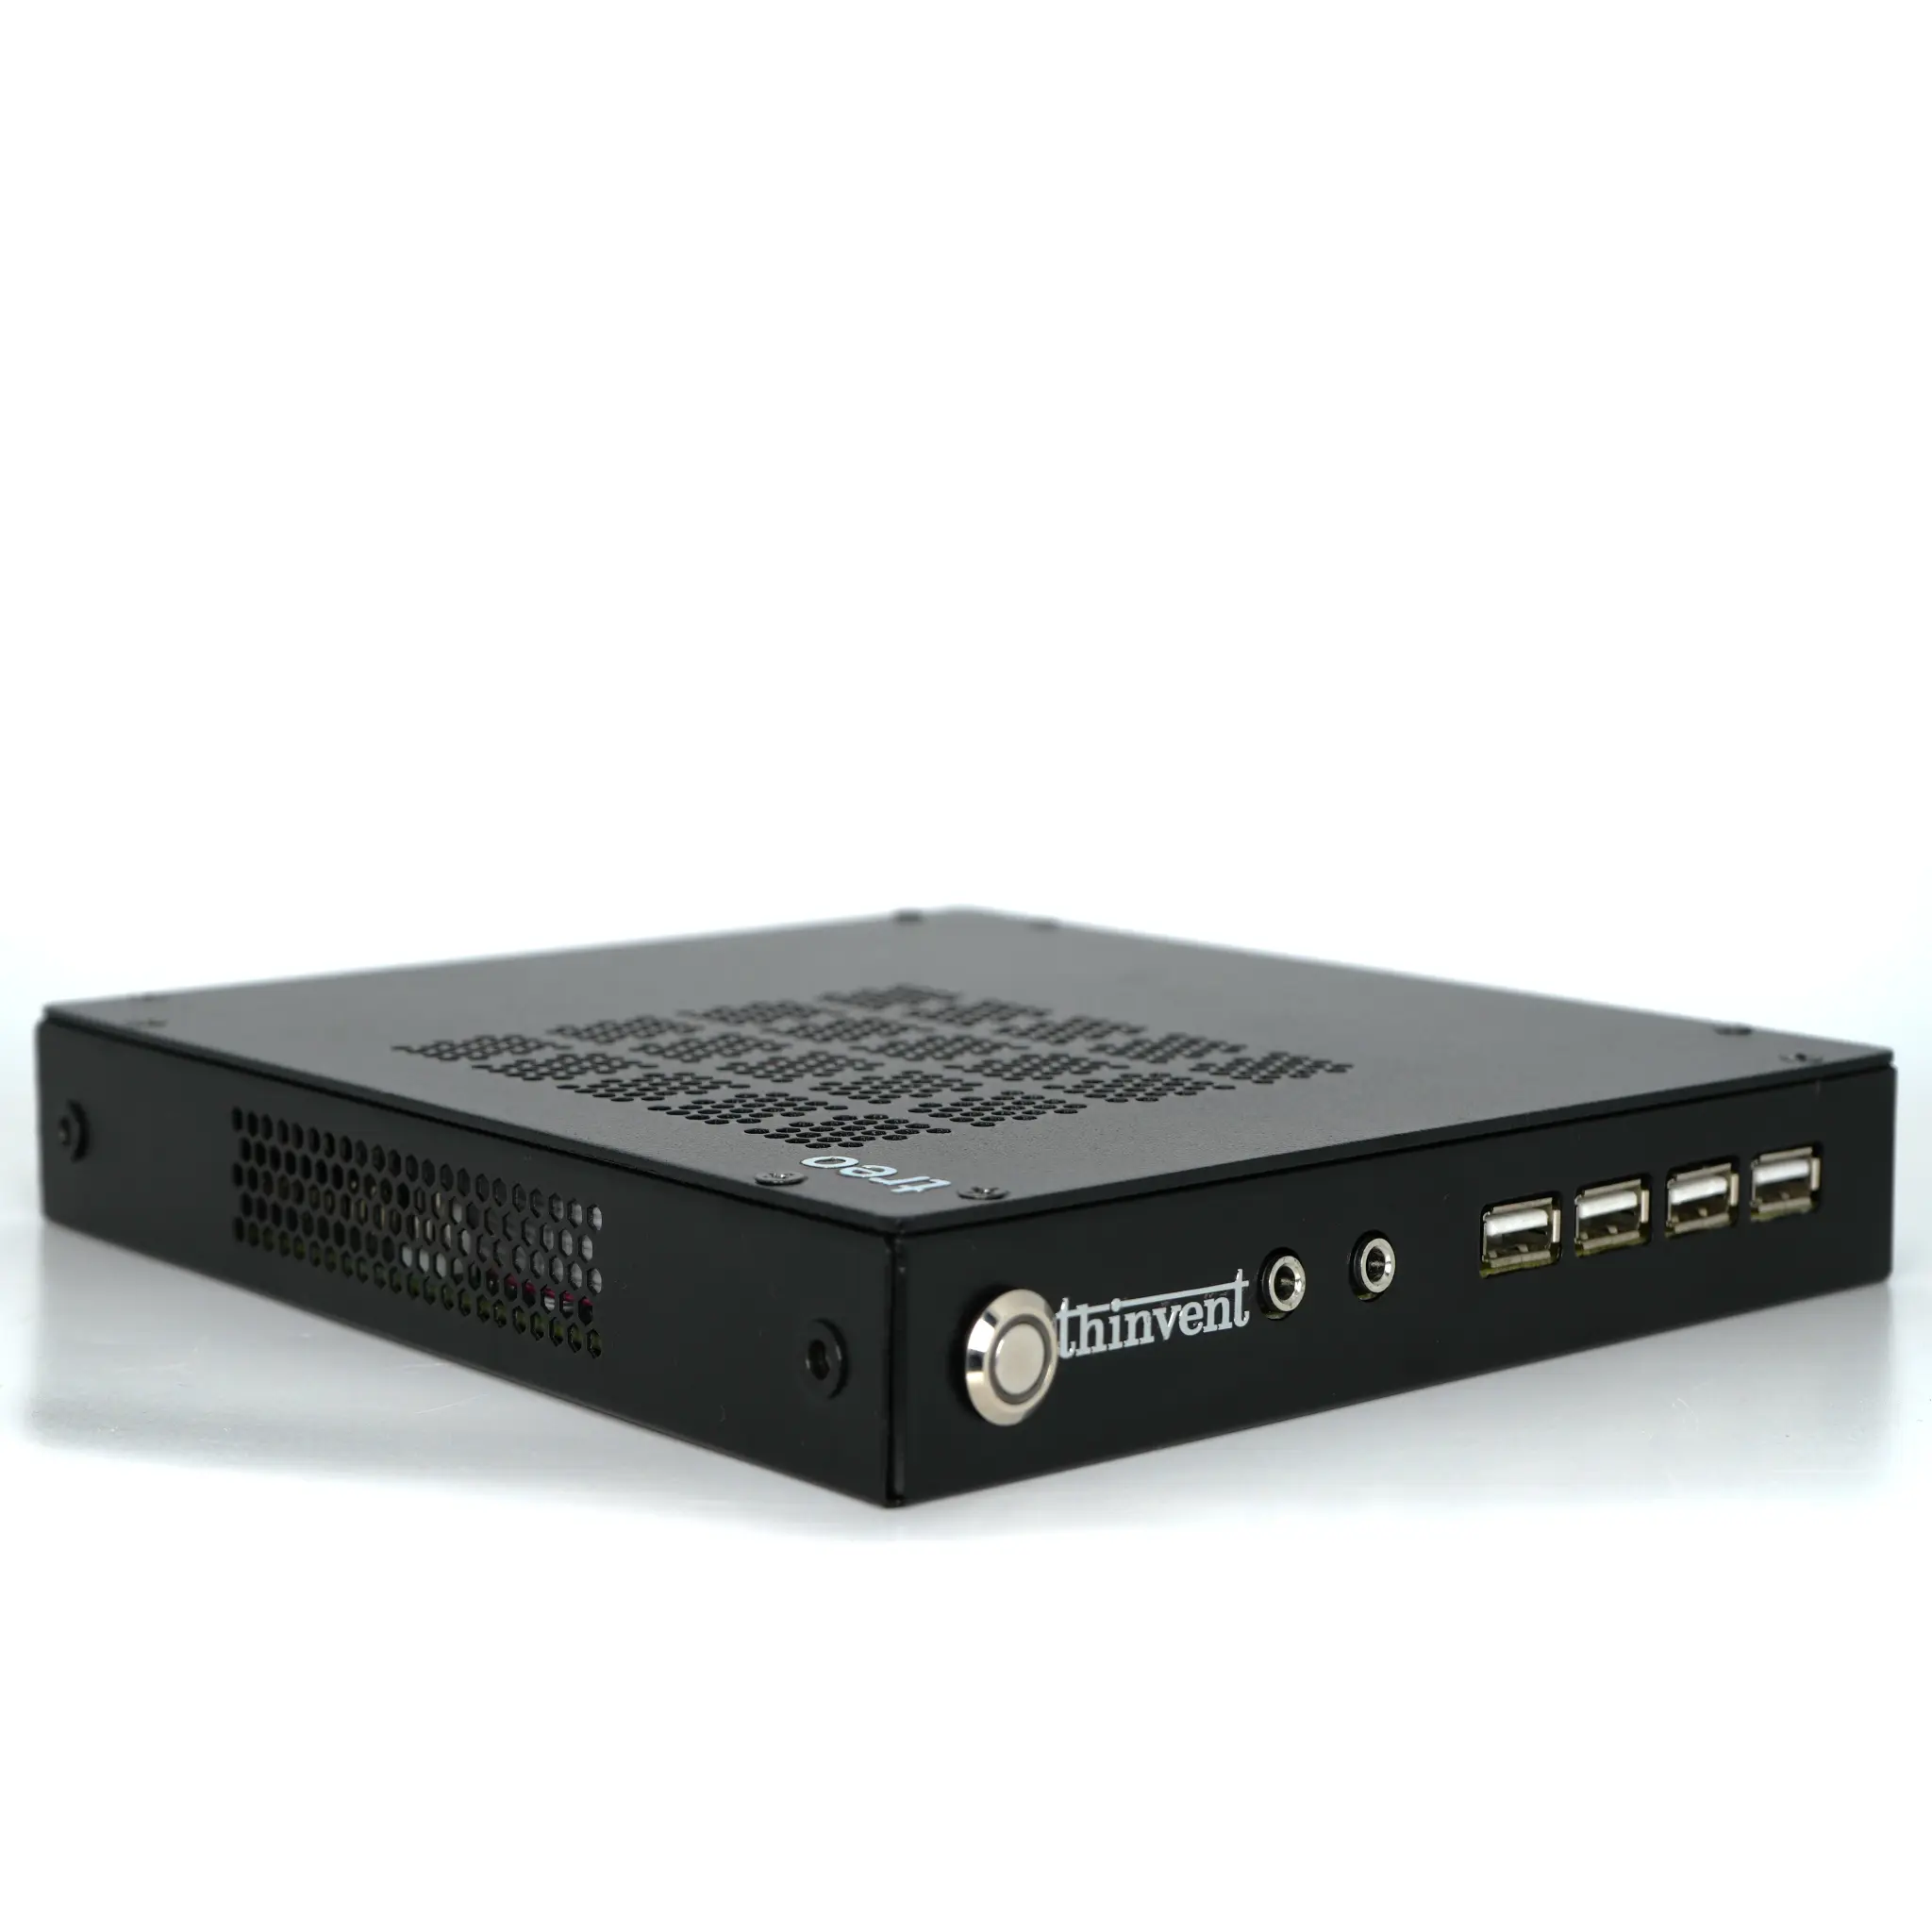
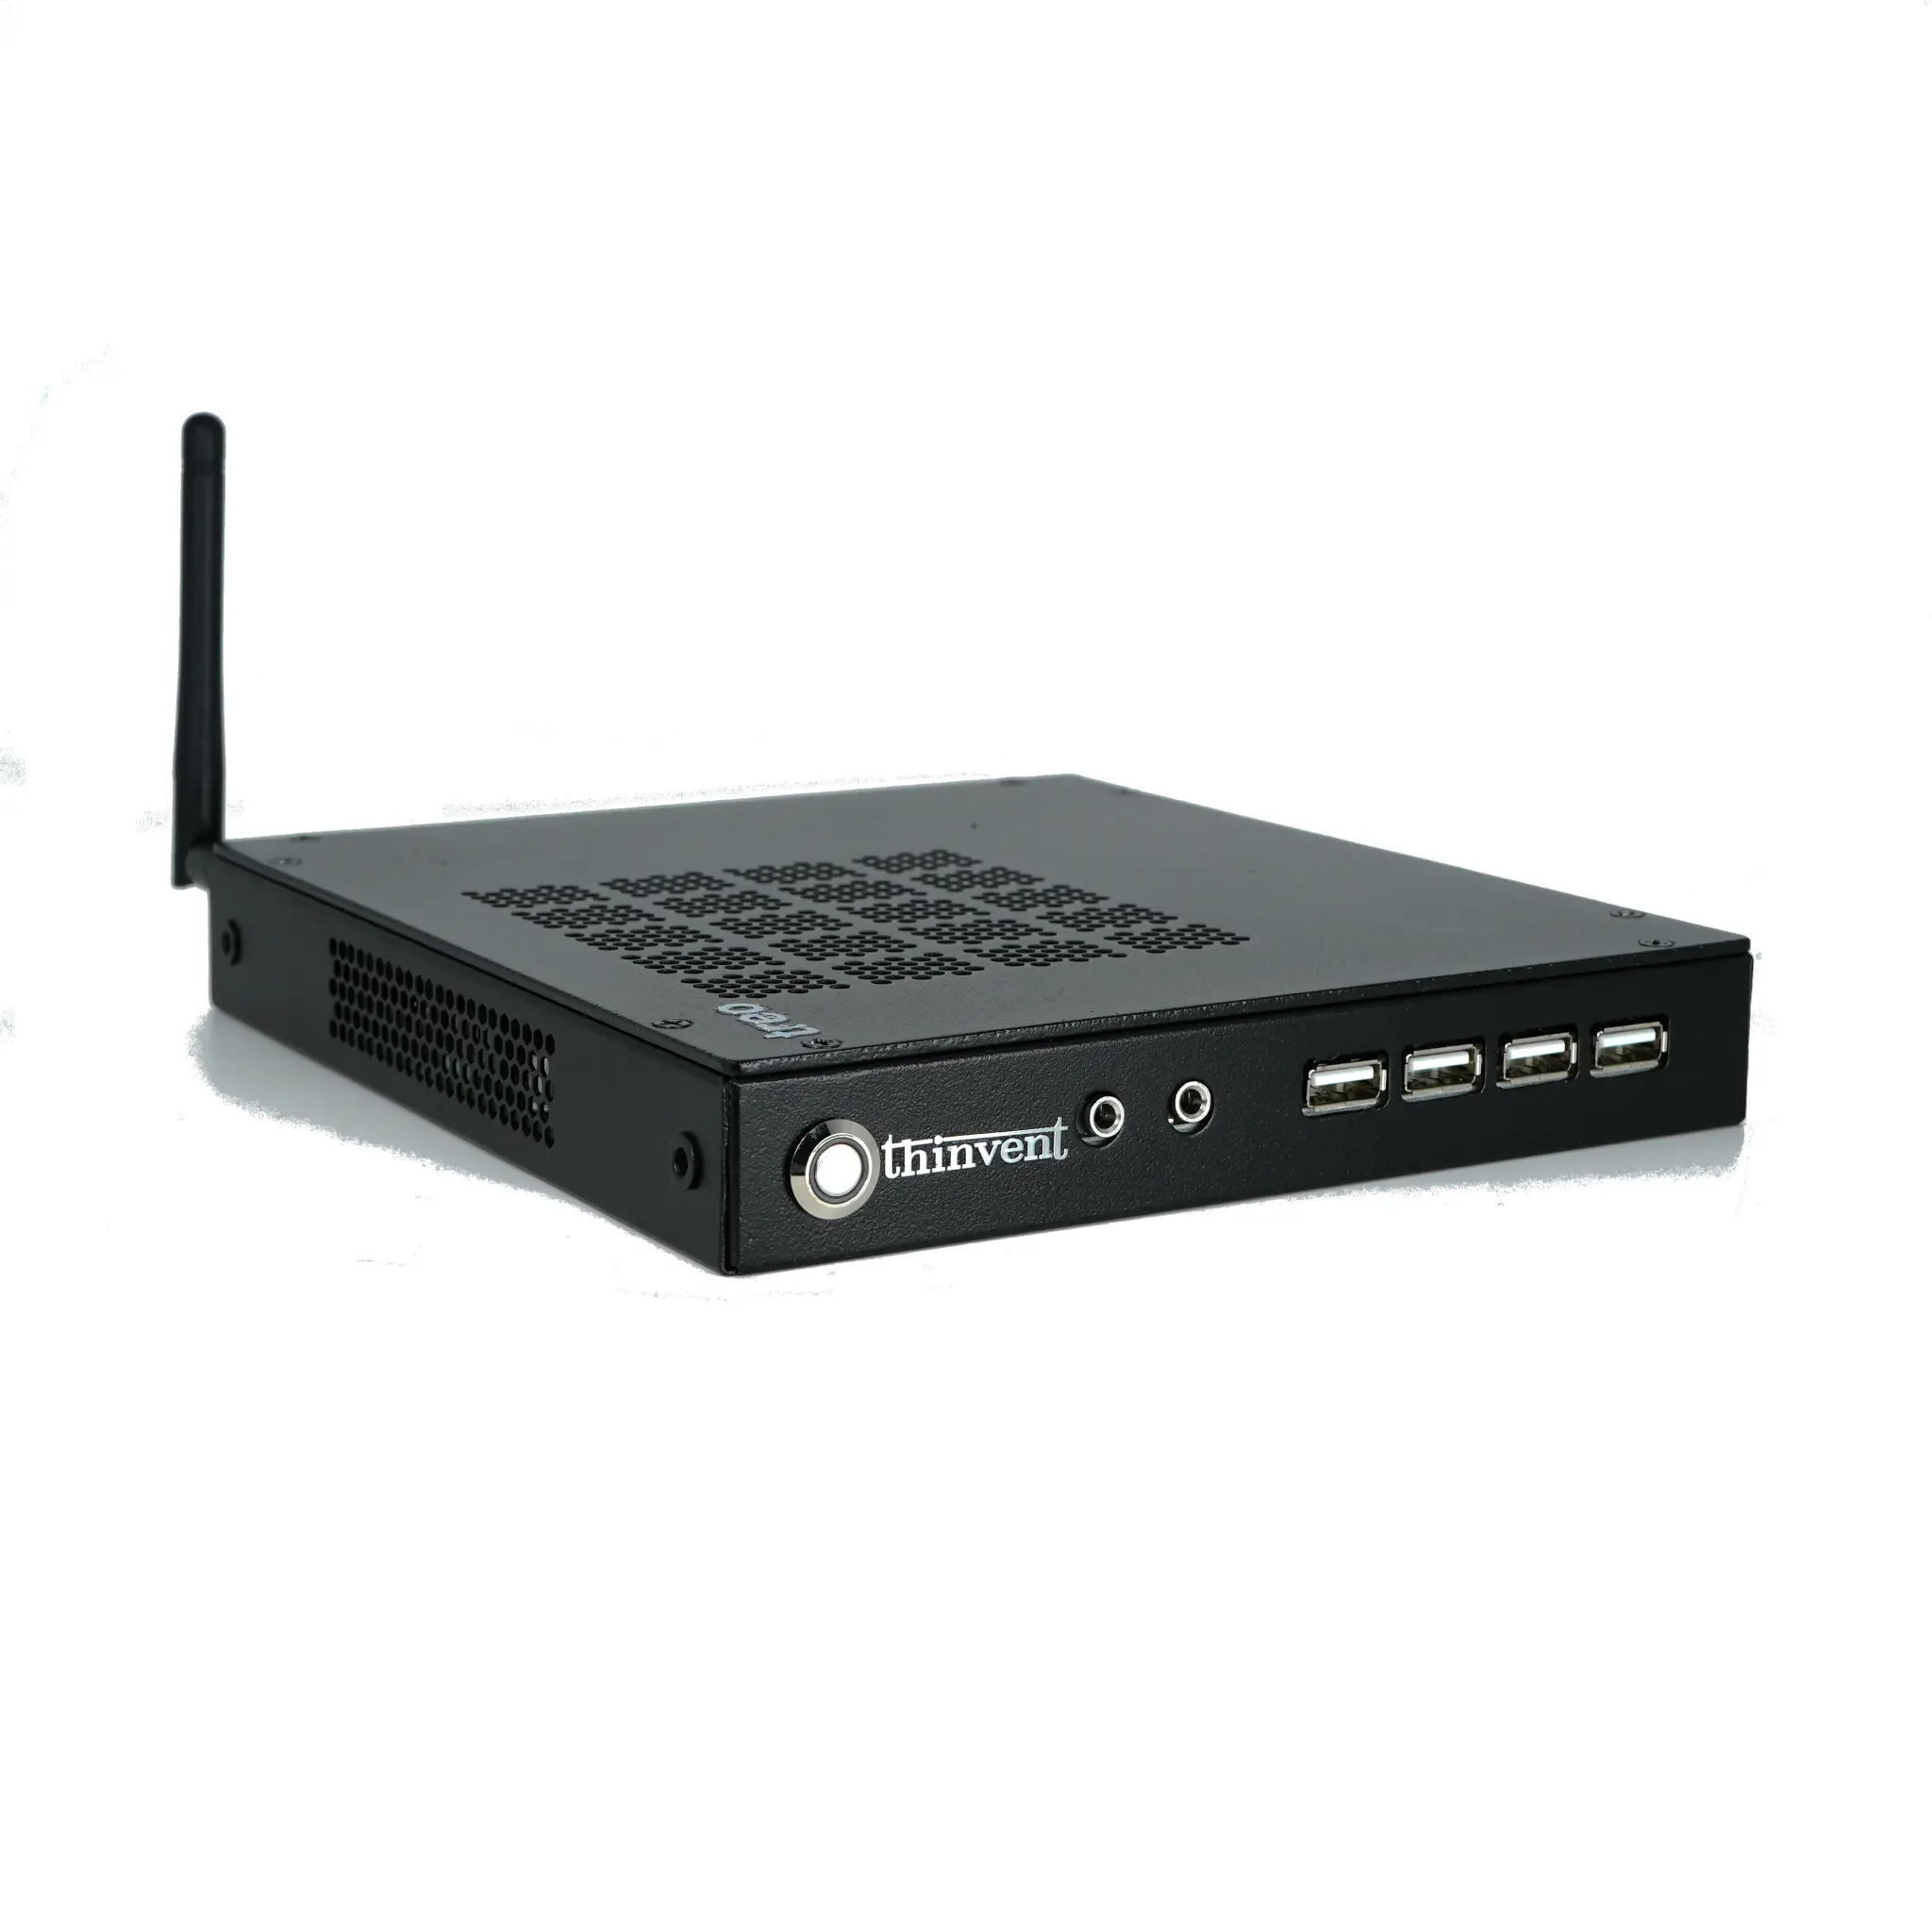
Thinvent offers a range of powerful Mini PCs and Industrial PCs that can be configured to meet the demands of running local LLMs. Our systems are designed for reliability and performance, providing a robust platform for your AI projects. With options for upgraded processors, significant RAM configurations, and fast SSD storage, you can build a machine tailored for efficient LLM inference. Explore Thinvent's compact yet powerful solutions to power your local AI development and deployment needs.