What Kind of Computer Do You Need to Run AI Locally?
Running AI locally means executing models such as large language models (LLMs), image generators, speech recognisers, or computer-vision pipelines on hardware you own, rather than sending data to a cloud API. The hardware you need depends on the size of the model and the workload. Small quantised language models (for example, 3B–8B parameter models in 4-bit or 8-bit form) and most vision or speech models run comfortably on a modern multi-core CPU with 16GB of RAM. Larger models, fine-tuning, and diffusion image generation benefit from a dedicated GPU with substantial VRAM, or from a CPU with many cores and a wide memory path.
Key Specifications That Matter
CPU: More cores and higher clock speeds shorten inference time. A 6-core Intel® Core™ processor such as the i3-1215U (6 cores, up to 4.4 GHz, 10 MB cache) handles quantised LLM inference, OCR, object detection, and speech-to-text reliably at the edge. Instruction sets such as AVX2 and AVX-512, where available, accelerate matrix maths used by runtimes like llama.cpp, ONNX Runtime, and OpenVINO.
Memory: RAM is the single most common bottleneck. As a rule of thumb, allow roughly 1GB of RAM per 1B parameters for 4-bit quantised models, plus overhead for the operating system and application. 16GB is a practical minimum for 7B–8B models; 32GB or 64GB gives headroom for larger models or several concurrent workloads.
Storage: AI models are large files. A 7B model in 4-bit form is roughly 4GB, while larger models run to tens of gigabytes. Fast NVMe SSD storage of 512GB or 1TB keeps model loading quick and leaves room for datasets, logs, and container images.
GPU (optional): A discrete GPU with 8GB or more VRAM dramatically speeds up inference and is required for comfortable diffusion image generation or fine-tuning. Many industrial and embedded deployments instead rely on CPU inference for lower power draw, wider temperature tolerance, and simpler long-term maintenance.
| Workload | Practical Minimum | Comfortable |
|---|---|---|
| 3B–8B quantised LLM chat | 6-core CPU, 16GB RAM, 512GB SSD | 10–12 core CPU, 32GB RAM, 1TB SSD |
| OCR, speech-to-text, vision | 4-core CPU, 8GB RAM, 256GB SSD | 6-core CPU, 16GB RAM, 512GB SSD |
| Diffusion image generation | GPU with 8GB VRAM | GPU with 12GB+ VRAM |
| Fine-tuning | GPU with 16GB+ VRAM | Multi-GPU workstation |
Software Stack
Local AI runs on Linux or Windows. On Linux, Python with PyTorch, llama.cpp, Ollama, or ONNX Runtime is the usual path; Ubuntu Linux 24.04 LTS is a common base because of its long support window. On Windows, Windows 11 Pro supports the same runtimes plus Windows-native tooling such as DirectML. Containerised deployment with Docker makes it easier to pin model versions and reproduce results. For headless or kiosk-style AI appliances, an embedded Linux image keeps the attack surface small and the boot time short.
Where Local AI Is Deployed
Local inference is chosen when data cannot leave the premises, when network latency or connectivity is unreliable, or when per-request cloud costs need to be avoided. Typical deployments include factory floors running visual quality inspection, retail and hospitality sites running on-device assistants, healthcare and legal environments handling confidential documents, and remote sites where a small fanless box must keep working through dust, heat, and vibration.
Thinvent Products for Local AI
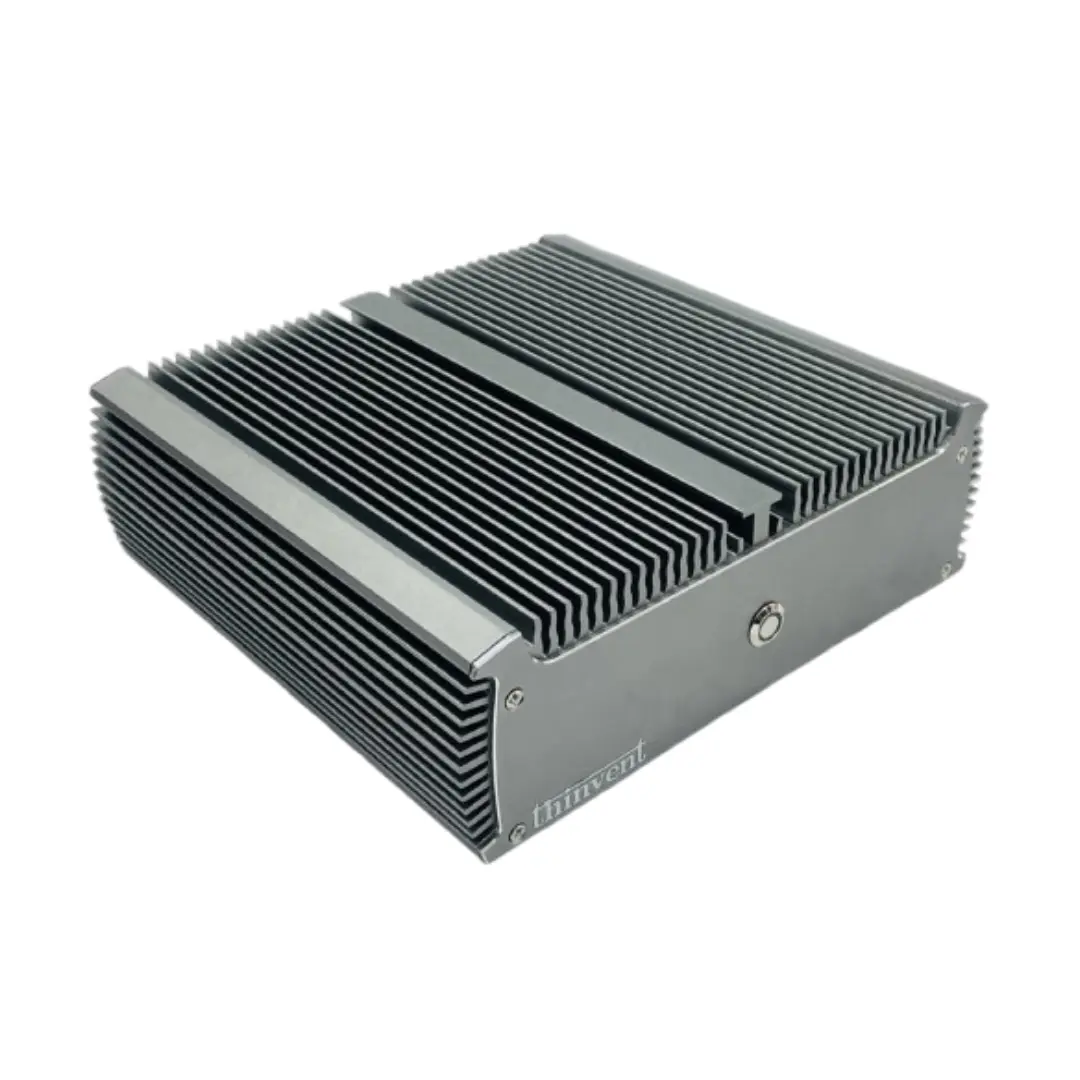
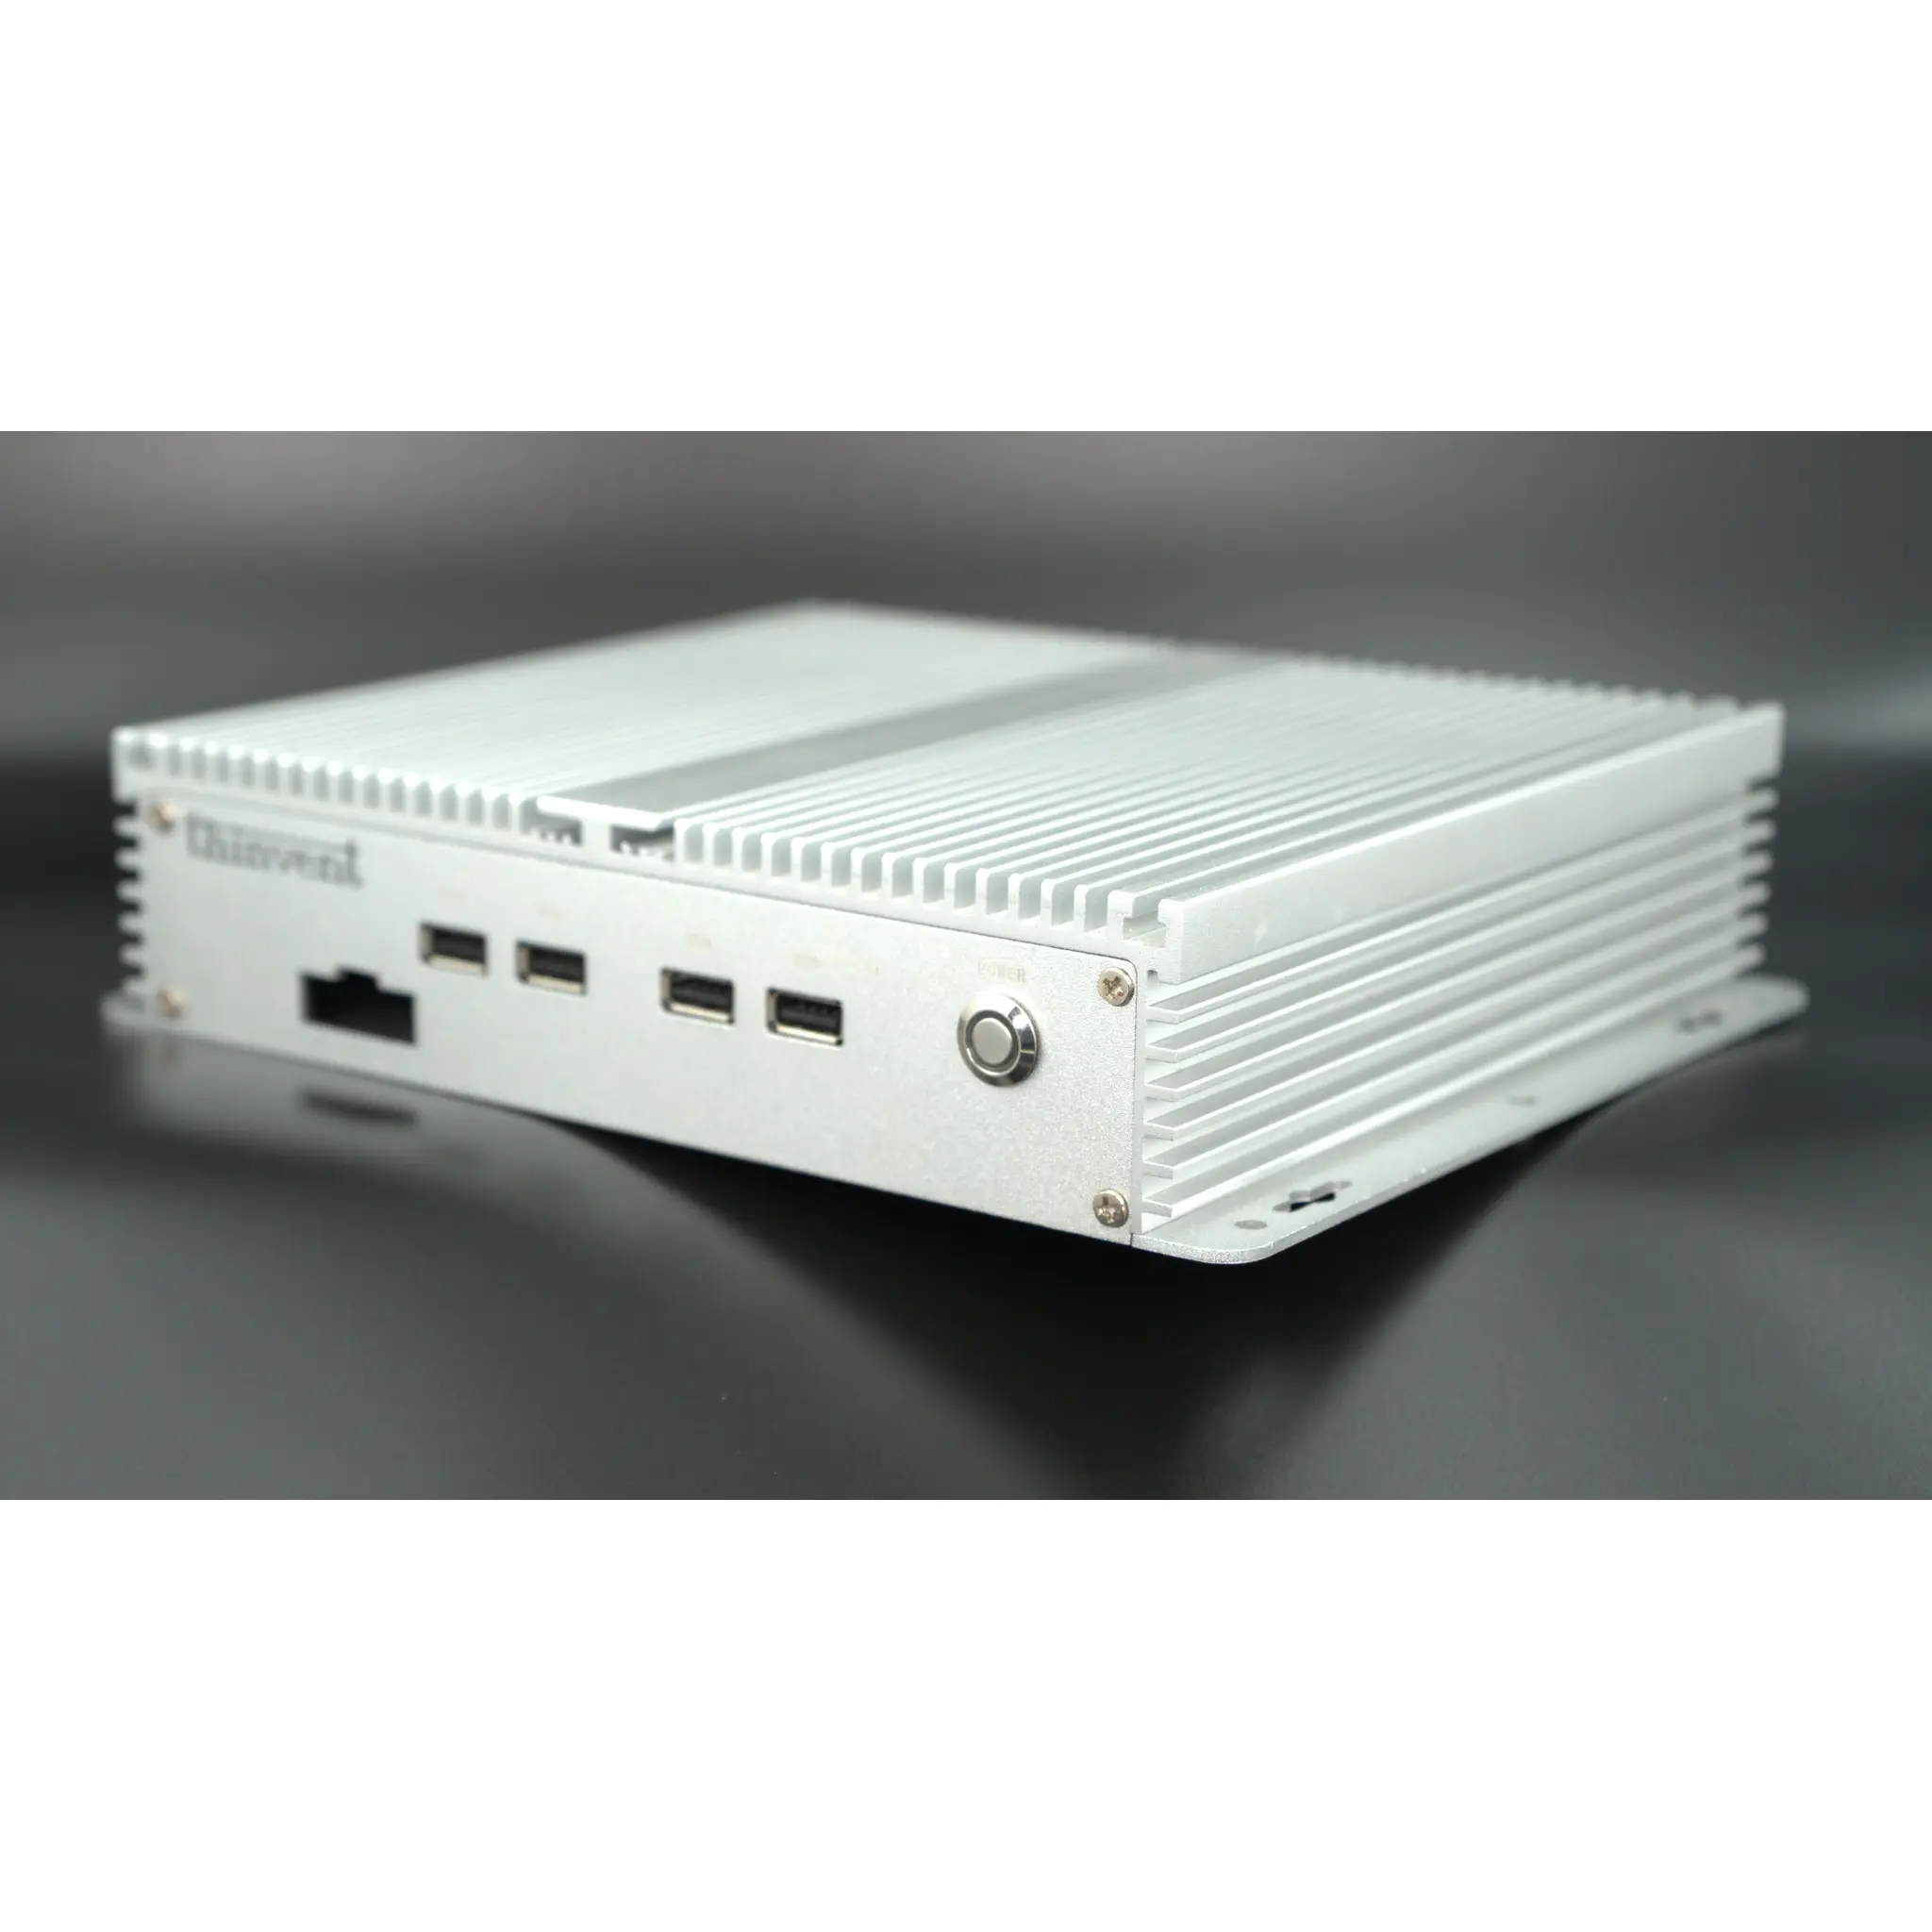
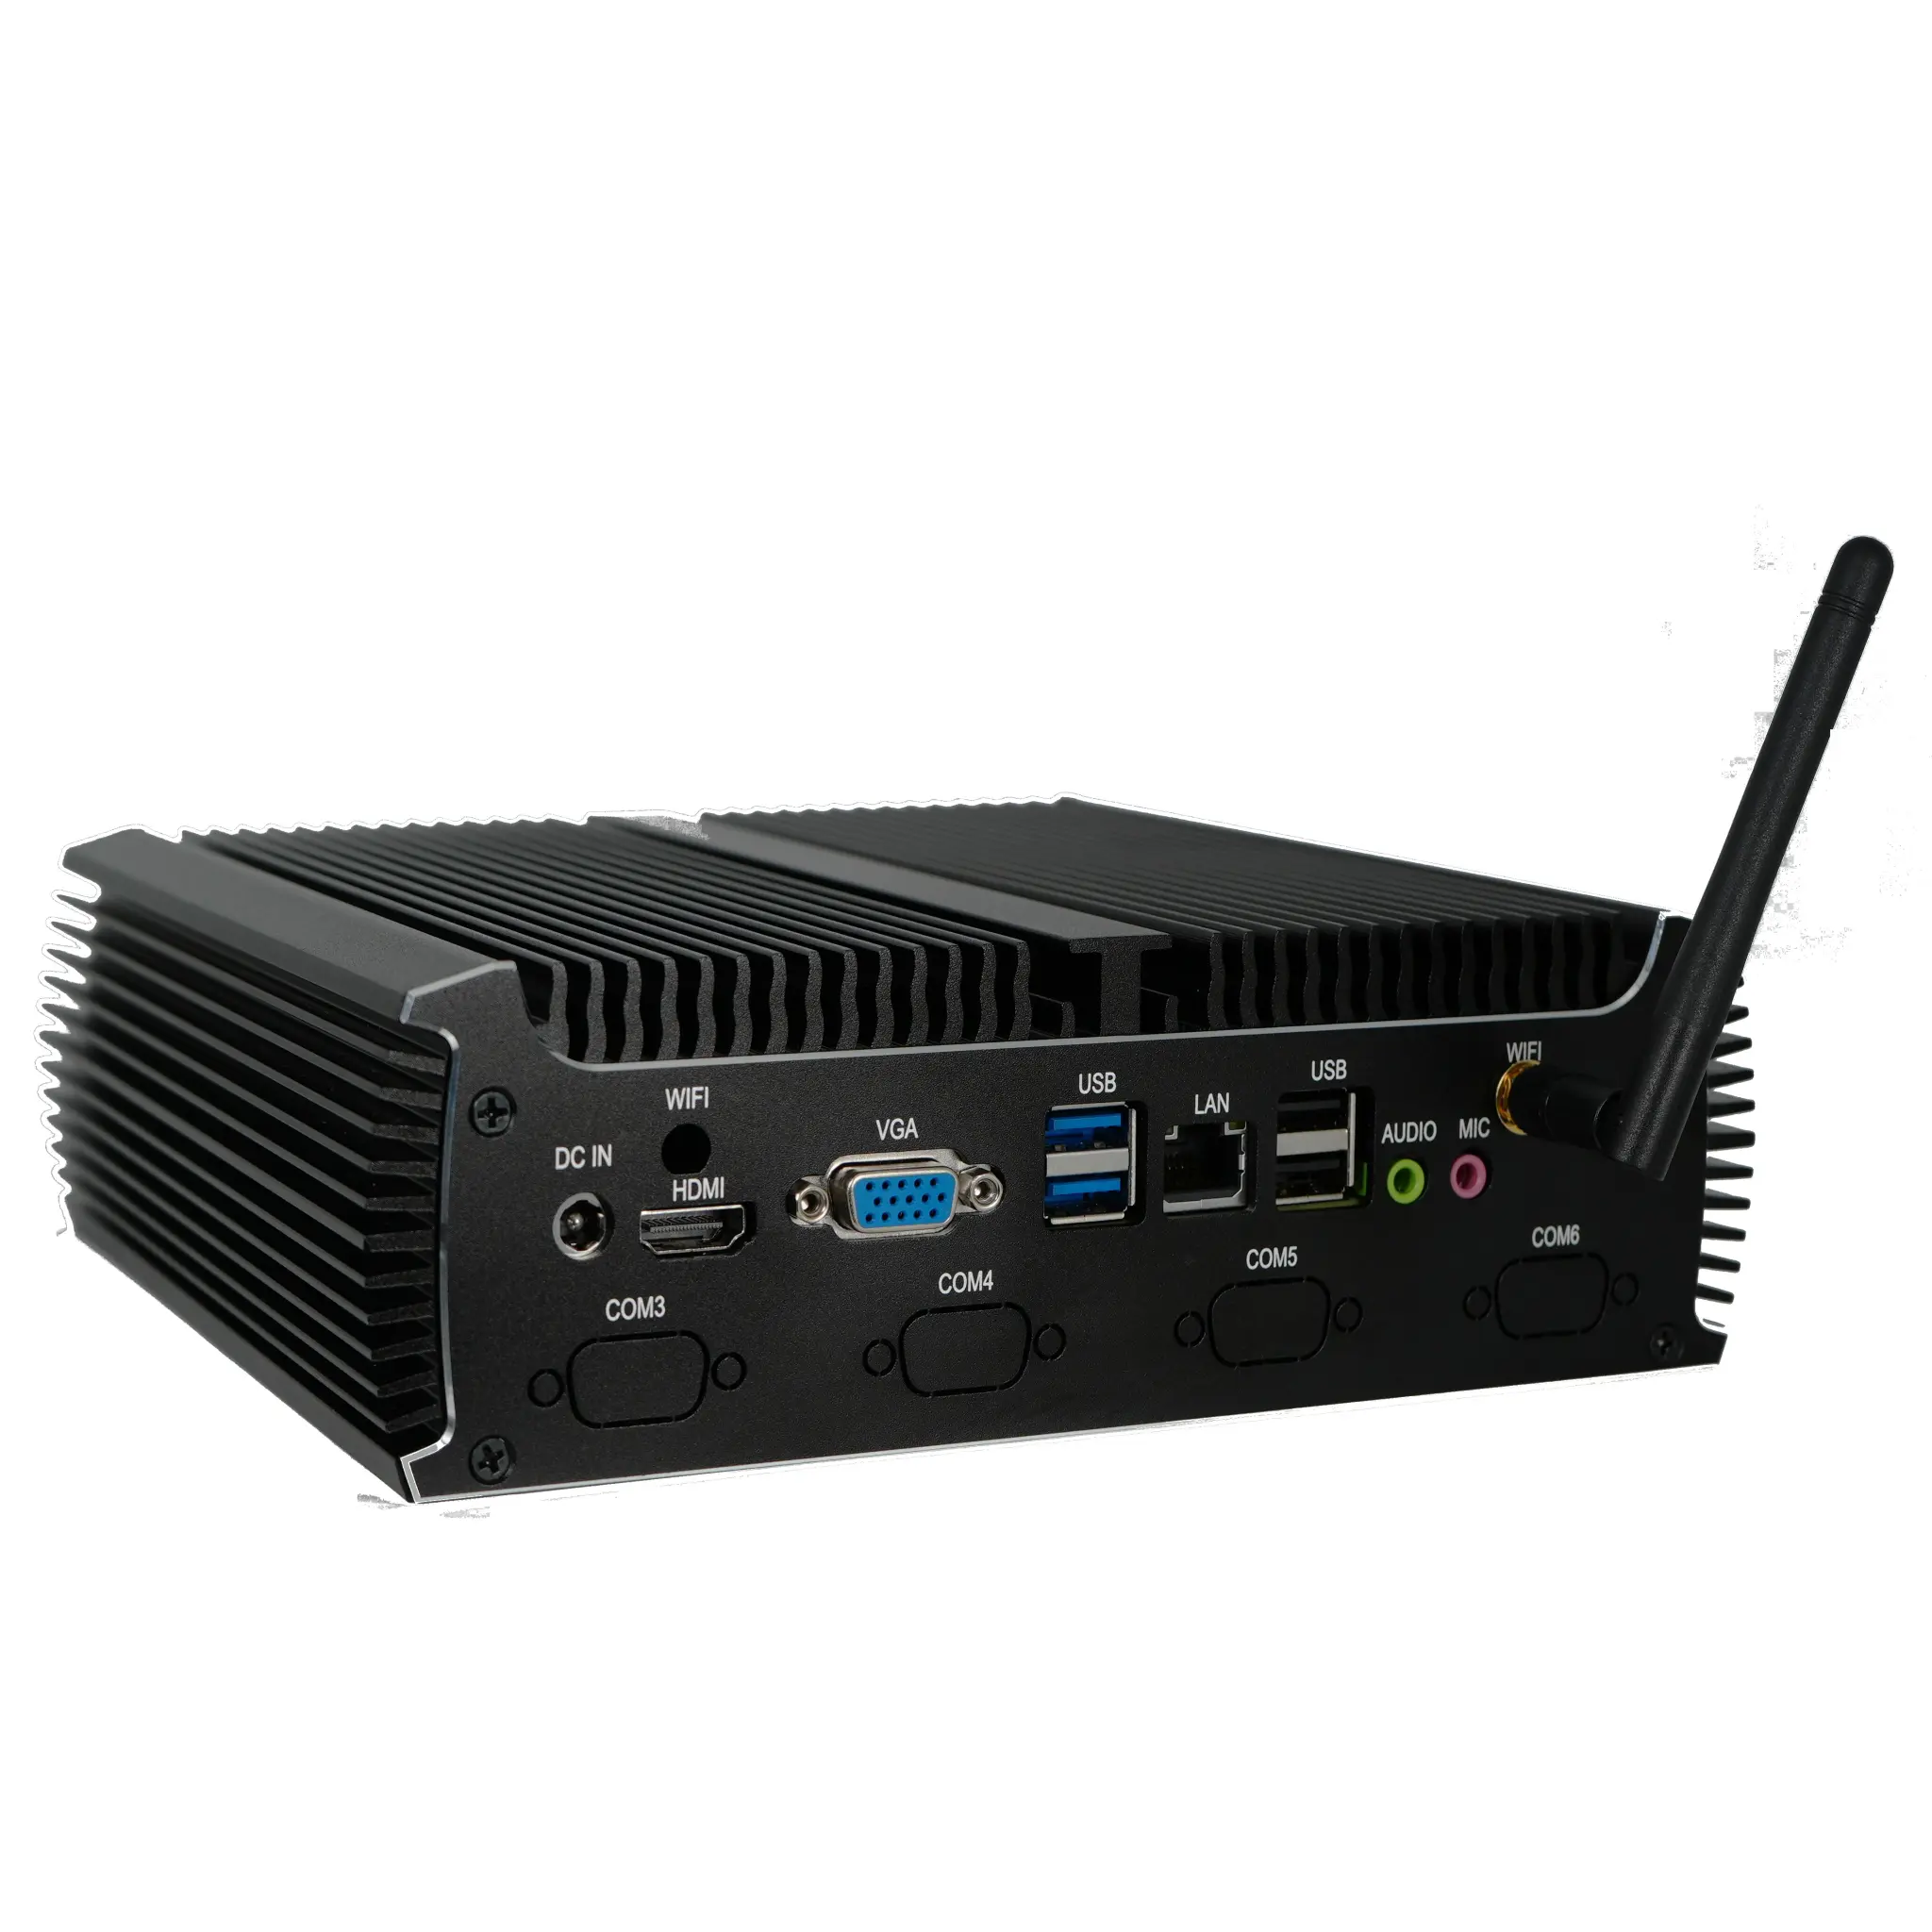
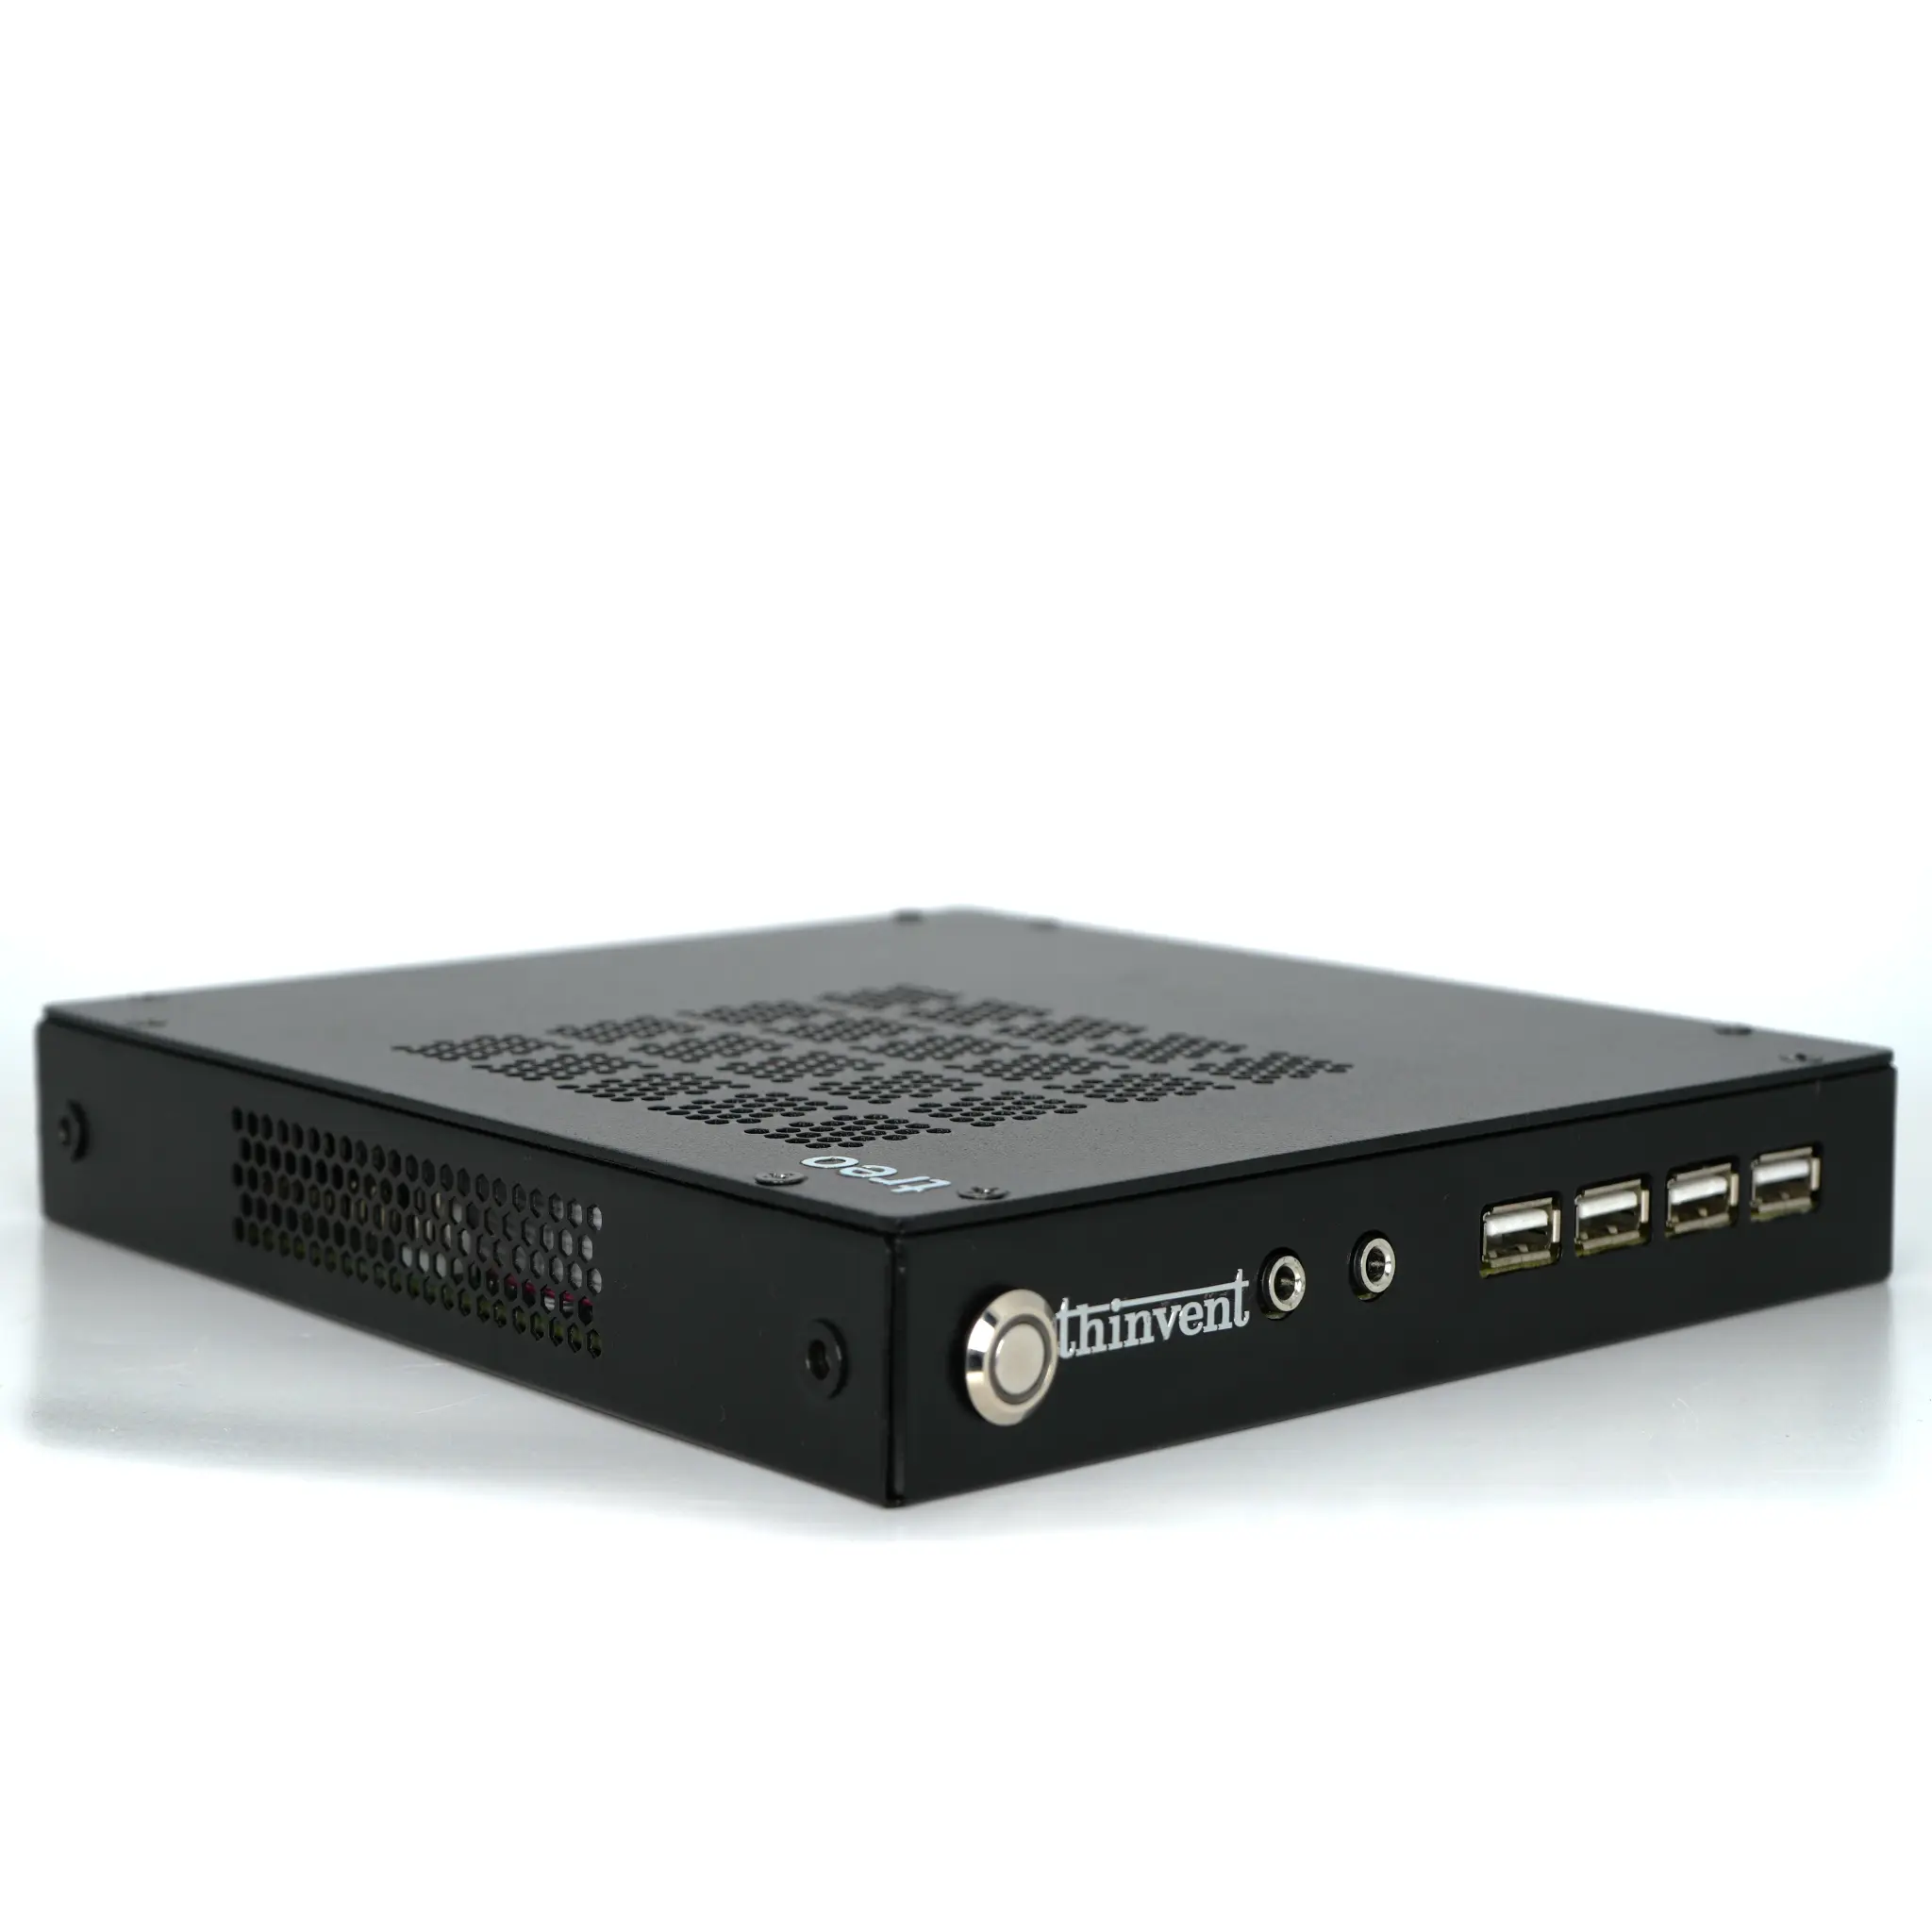
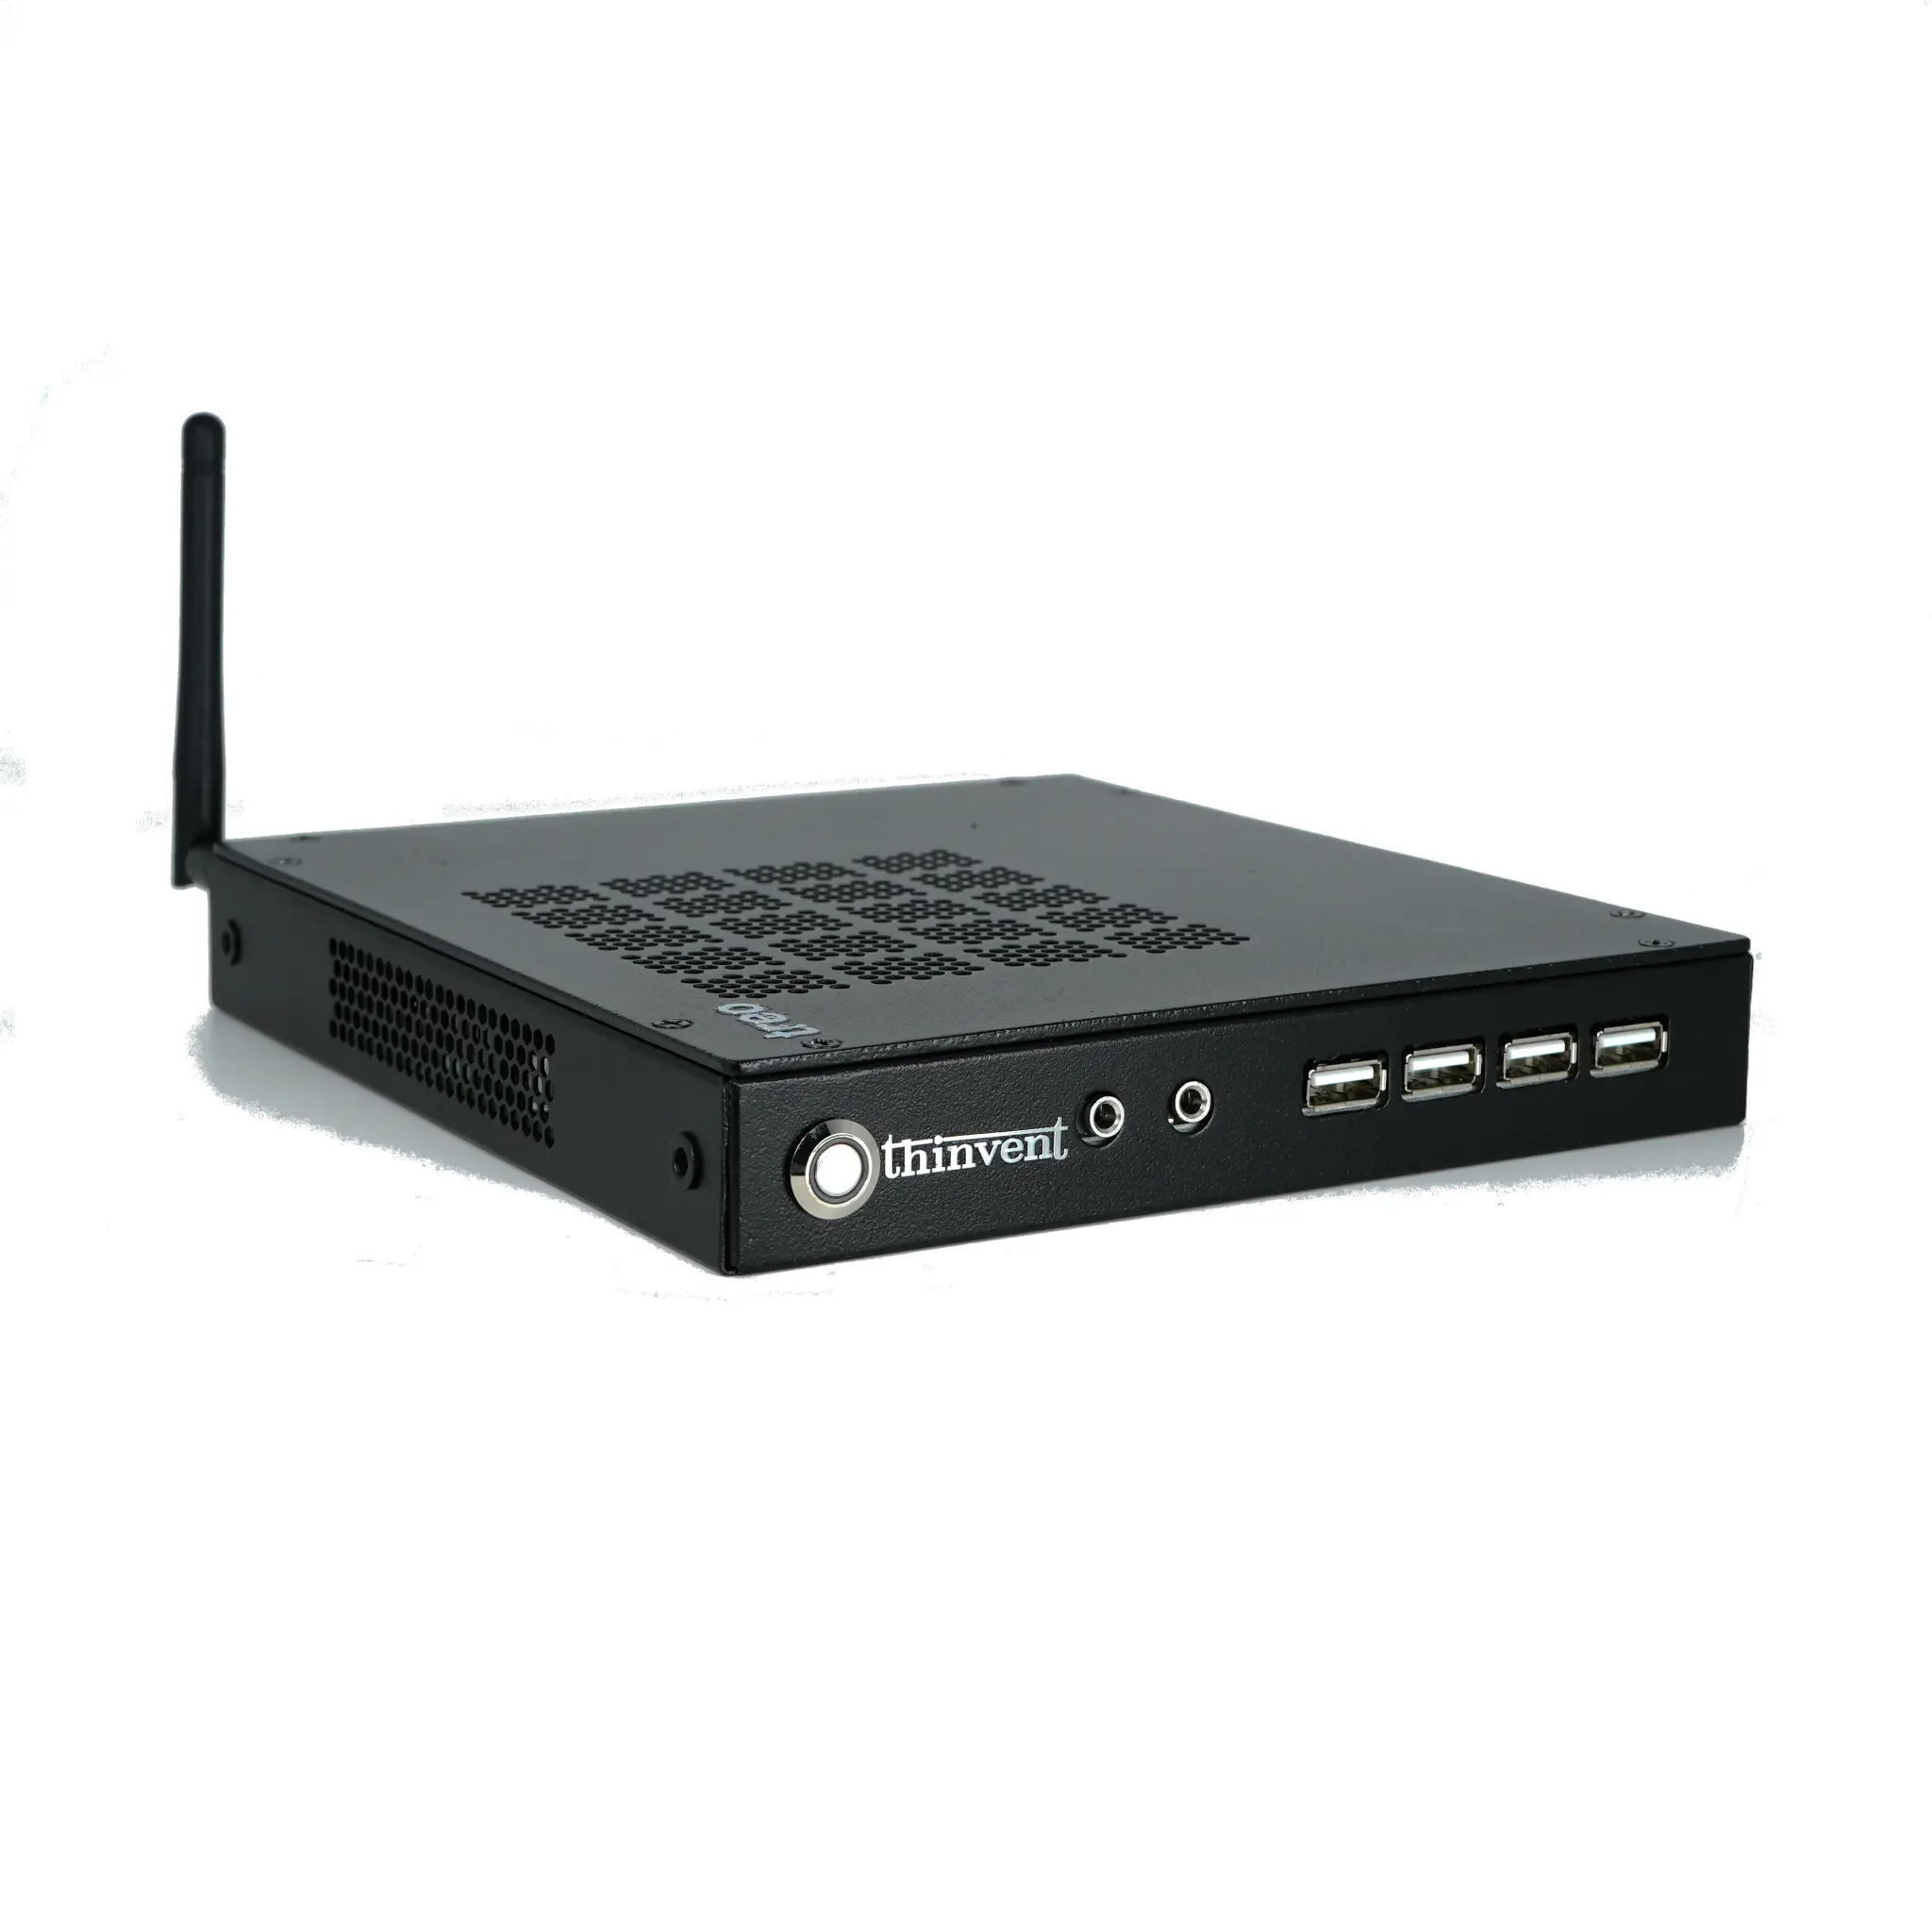
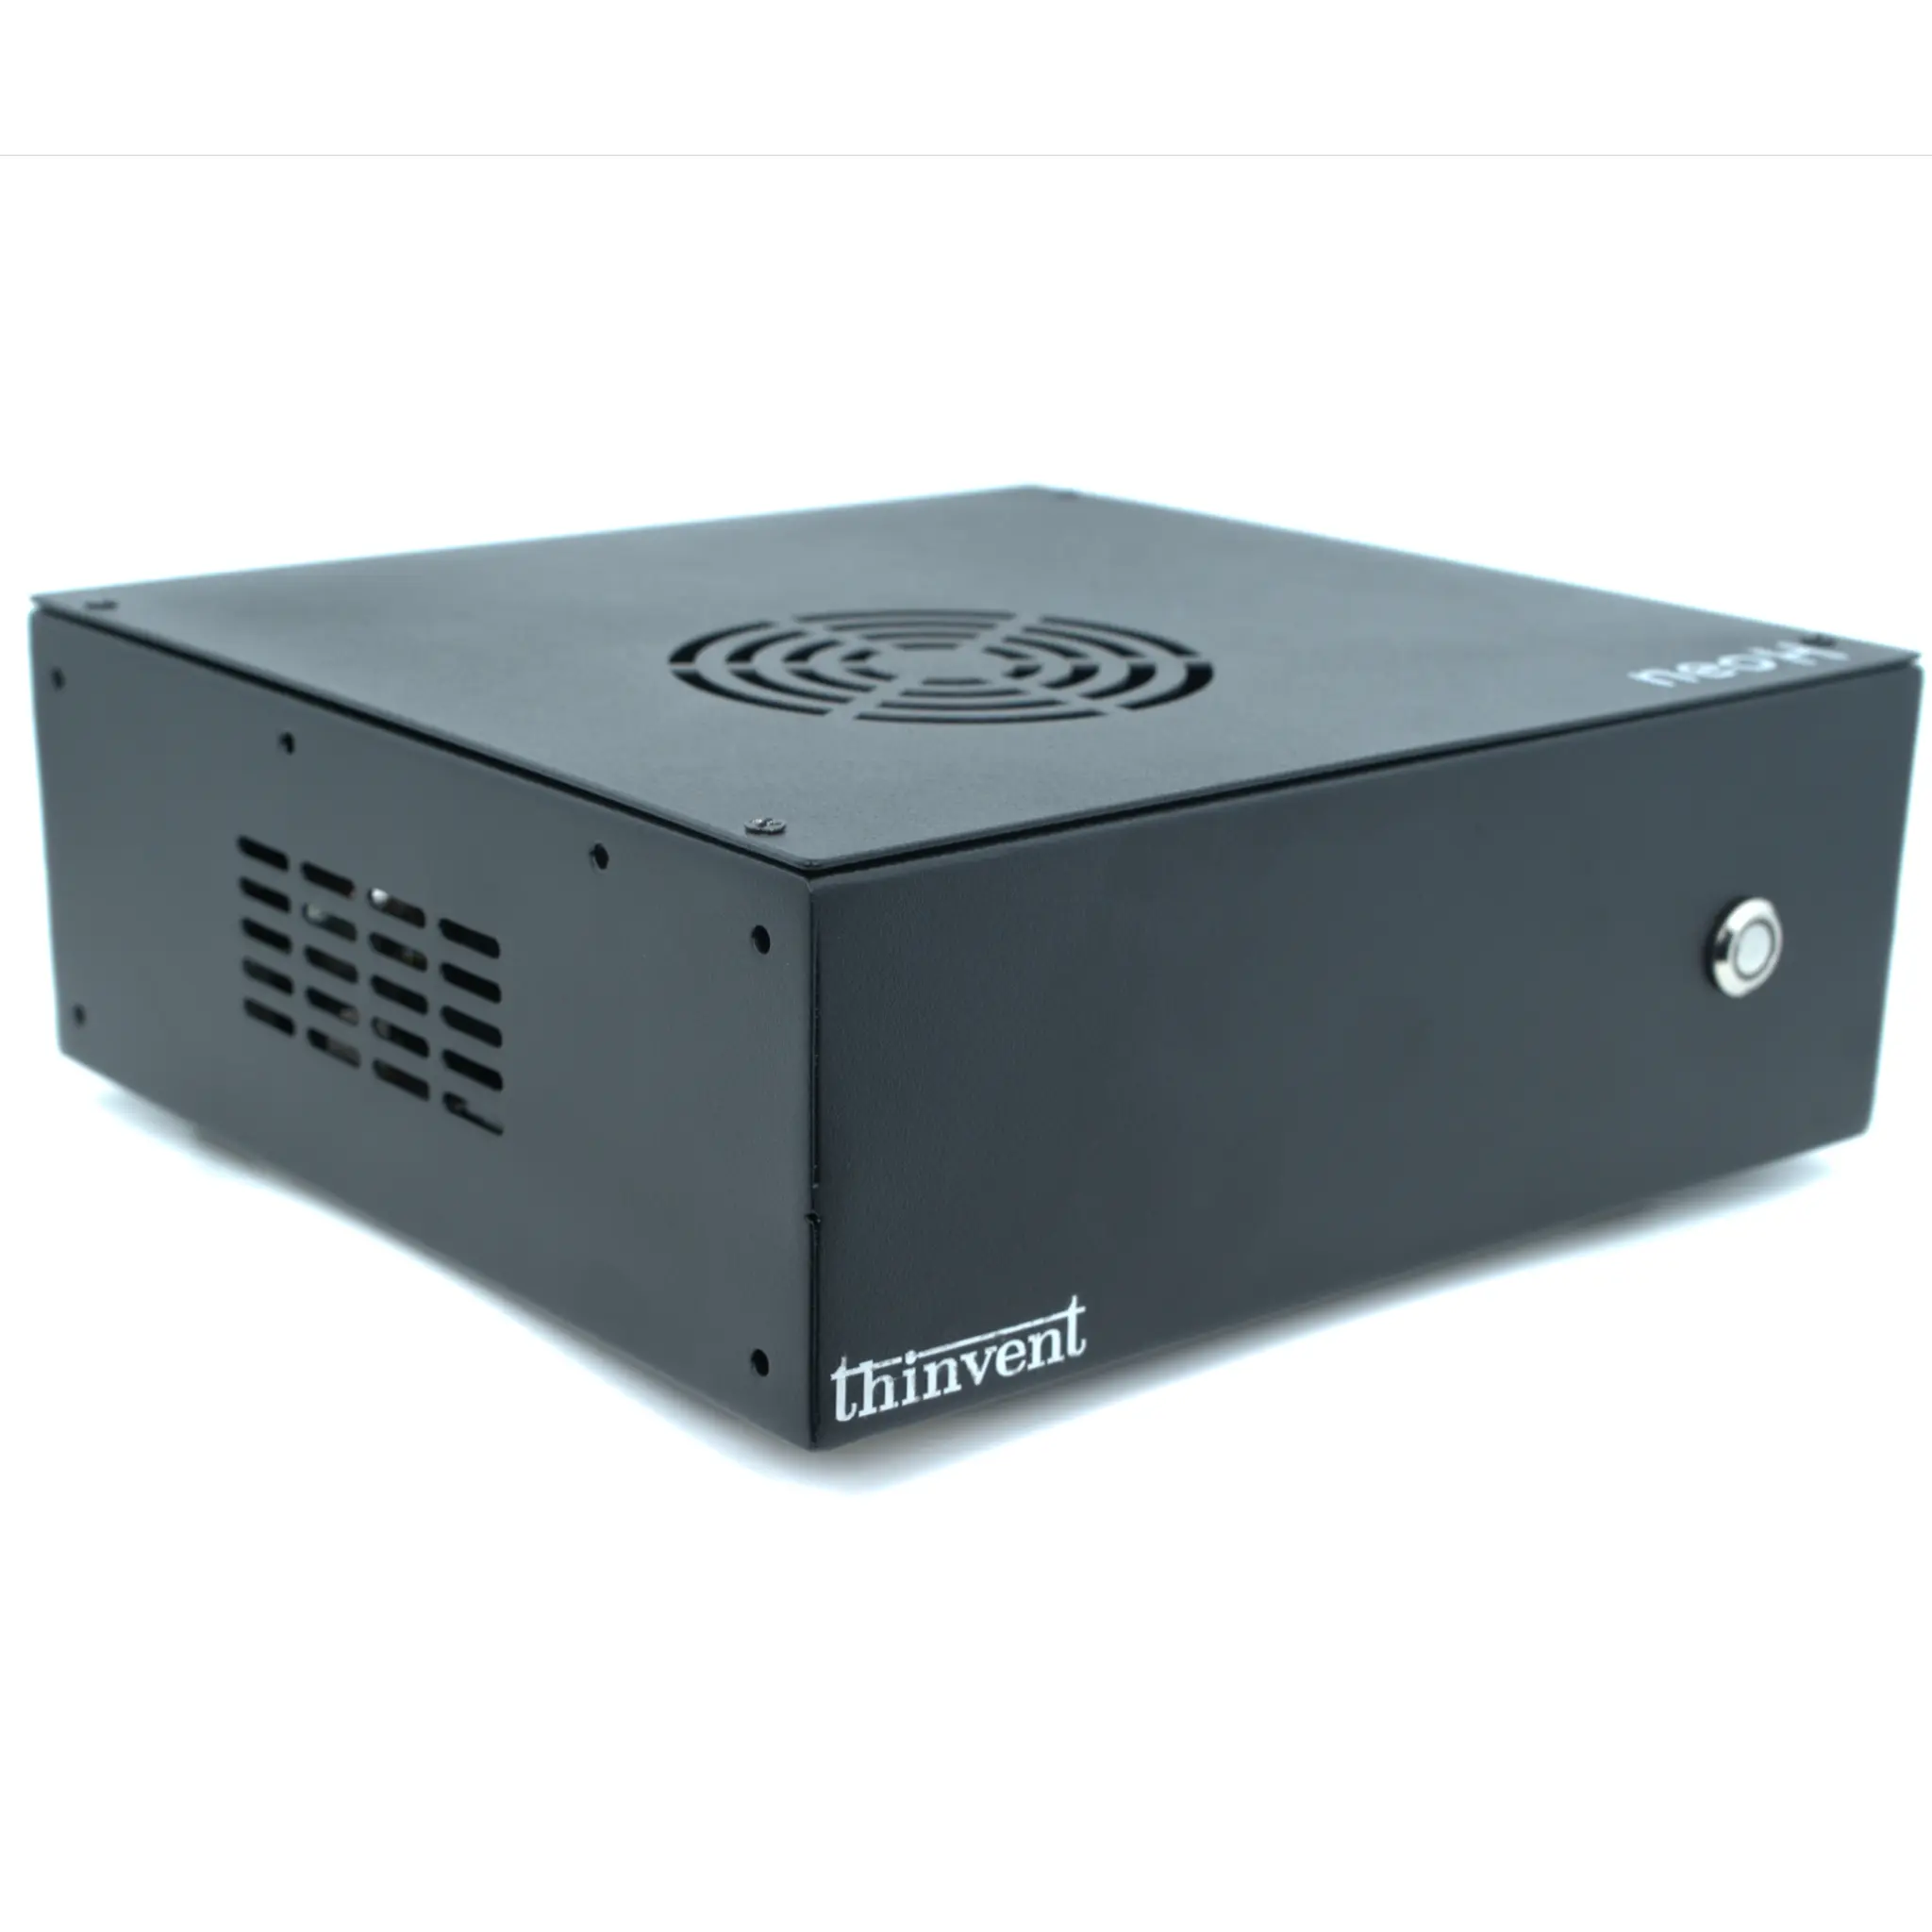
Thinvent builds fanless industrial computers, mini PCs, thin clients, and all-in-one PCs suited to on-premises AI workloads. Configurations based on 12th-generation Intel® Core™ processors such as the i3-1215U pair 6 cores with 16GB DDR4 memory and 1TB SSD storage, giving enough compute and memory for quantised LLM inference, computer vision, and speech processing at the edge. Systems are available with Windows 11 Pro, Windows 11 IoT, Ubuntu Linux 24.04 LTS, Thinux™ Embedded Linux, or without an OS, so you can install the AI runtime that fits your stack. Fanless, ventless chassis options support deployment in dusty or high-temperature environments where a standard desktop would struggle, and dual Ethernet and multiple serial ports allow direct connection to industrial equipment and sensors alongside the AI workload.