What Does "Open Source Local AI" Mean?
Open source local AI refers to running artificial intelligence models — large language models (LLMs), computer vision pipelines, speech-to-text engines, and image generators — directly on hardware you own, using freely available, openly licensed software. Instead of sending prompts and data to a cloud API, the model executes on a local machine: a mini PC, thin client, all-in-one, or industrial computer sitting on your desk, in your lab, or on a factory floor.
The two halves of the phrase matter equally. "Open source" covers the model weights and runtimes — projects such as llama.cpp, Ollama, LM Studio, Open WebUI, Whisper, Stable Diffusion, and the Hugging Face ecosystem — which you can download, inspect, modify, and run without per-token fees. "Local" means inference happens on your own silicon, so sensitive documents, customer records, camera feeds, and machine data never leave the premises.
Hardware Requirements for Local AI Inference
Local AI is memory-bandwidth and memory-capacity bound far more than it is raw-clock bound. When an LLM generates text, every token requires streaming the model weights through the CPU, so RAM size determines which models you can load and RAM speed influences how quickly tokens appear.
| Model Size (Quantised) | Typical RAM Needed | Practical Experience |
|---|---|---|
| 1–3B parameters (Q4) | 4–8 GB | Snappy on modest CPUs; good for classification, summarisation, simple chat |
| 7–8B parameters (Q4) | 8–16 GB | The sweet spot for assistants, document Q&A, coding help |
| 13–14B parameters (Q4) | 16–32 GB | Noticeably better reasoning; slower but usable on 6-core CPUs |
| 30B+ parameters (Q4) | 32–64 GB | Workstation-class; expect several tokens per second |
A modern 6-core processor such as the Intel® Core™ i3-1215U, paired with 16 GB of DDR4 and a fast NVMe SSD, comfortably runs 7B–8B quantised models at conversational speeds while simultaneously serving a web UI, a vector database for retrieval-augmented generation (RAG), and a document-ingestion pipeline. Storage matters too: model files are large, and a 1 TB SSD gives room for several models plus the data they work on.
Why Run AI Locally Instead of in the Cloud?
Privacy and data sovereignty are the leading reasons. Healthcare, legal, financial, and government users often cannot transmit raw data to third-party endpoints. Local inference keeps everything inside the network boundary, which simplifies compliance and removes the risk of a provider logging or training on your inputs.
Cost predictability is the second driver. Cloud inference bills scale with usage; a one-time hardware purchase does not. For steady, continuous workloads — a camera analytics box watching four streams, a helpdesk assistant answering hundreds of queries a day — local hardware frequently pays for itself quickly.
Availability is the third. Local AI keeps working when the internet drops, when a provider has an outage, or when rate limits bite. For industrial and edge deployments, that resilience is not a luxury — it is the difference between a line running and a line stopped.
Use Cases and Deployment Patterns
-
Private document assistants: RAG over contracts, manuals, and internal wikis, with embeddings and the LLM both running locally.
-
Computer vision at the edge: defect detection, people counting, PPE compliance, and licence-plate recognition on factory or retail premises.
-
Speech and transcription: Whisper-class models converting meetings or call recordings to text without uploading audio.
-
Developer tooling: local code completion and code review assistants that never expose proprietary source code.
-
Offline and air-gapped environments: ships, remote sites, defence, and research facilities where no external connection exists.
-
Kiosks and digital signage: on-device language translation and content generation for all-in-one systems.
Fanless industrial designs are particularly well suited here, because they tolerate dust, vibration, and wide temperature ranges while running 24/7 without a fan to fail.
Choosing Hardware for Open Source Local AI
Look for four things: enough RAM to hold your target model, a processor with strong single-thread performance for prompt processing, NVMe storage for fast model loading, and an operating system that gives you full control of the software stack. Linux (including Ubuntu and embedded distributions) is the most common choice because CUDA-free CPU inference with llama.cpp is straightforward, but Windows 11 Pro works equally well with Ollama, LM Studio, and similar tools. Multiple network ports and serial interfaces are useful when the same box must also talk to PLCs, cameras, or legacy equipment.
Thinvent Products Suited to Open Source Local AI
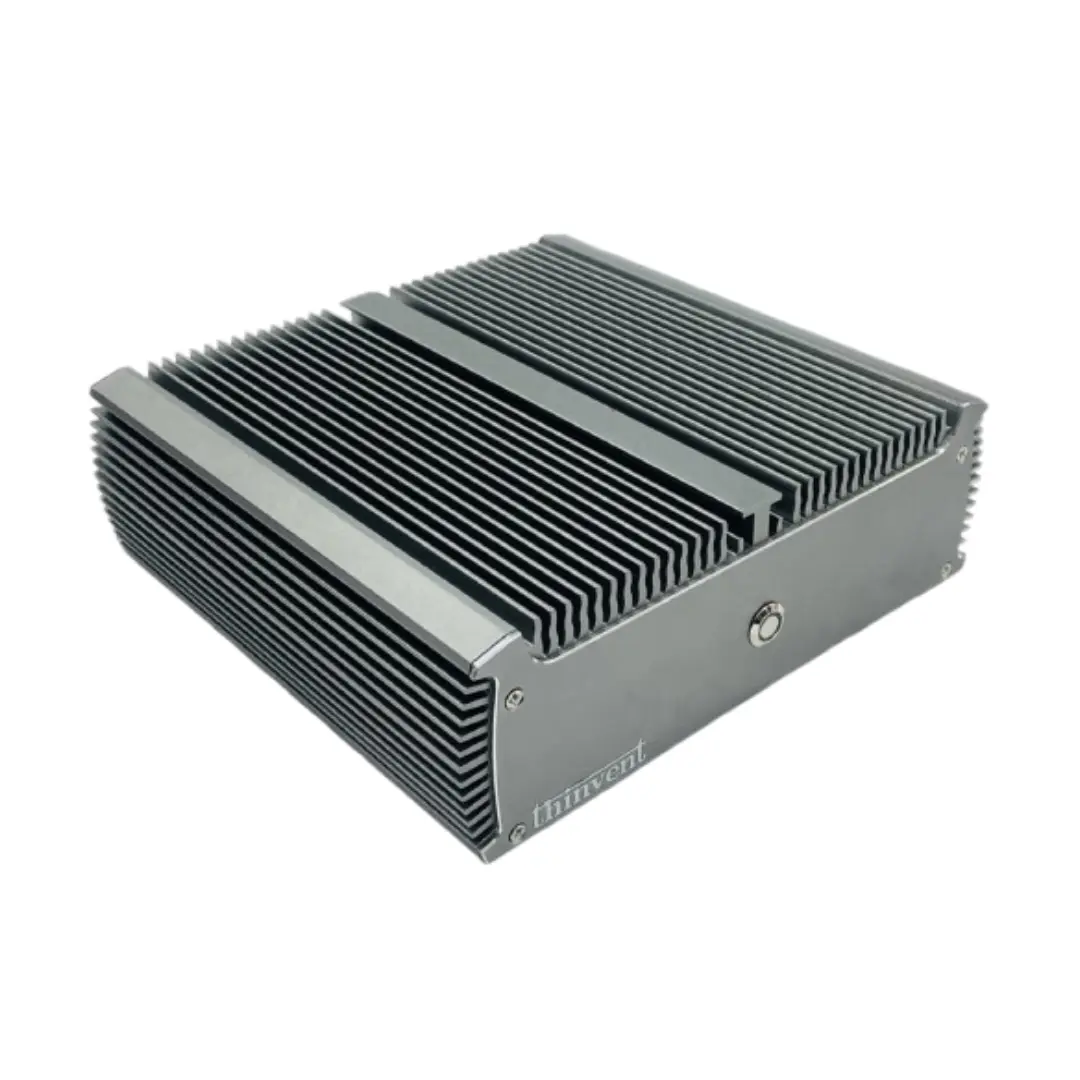
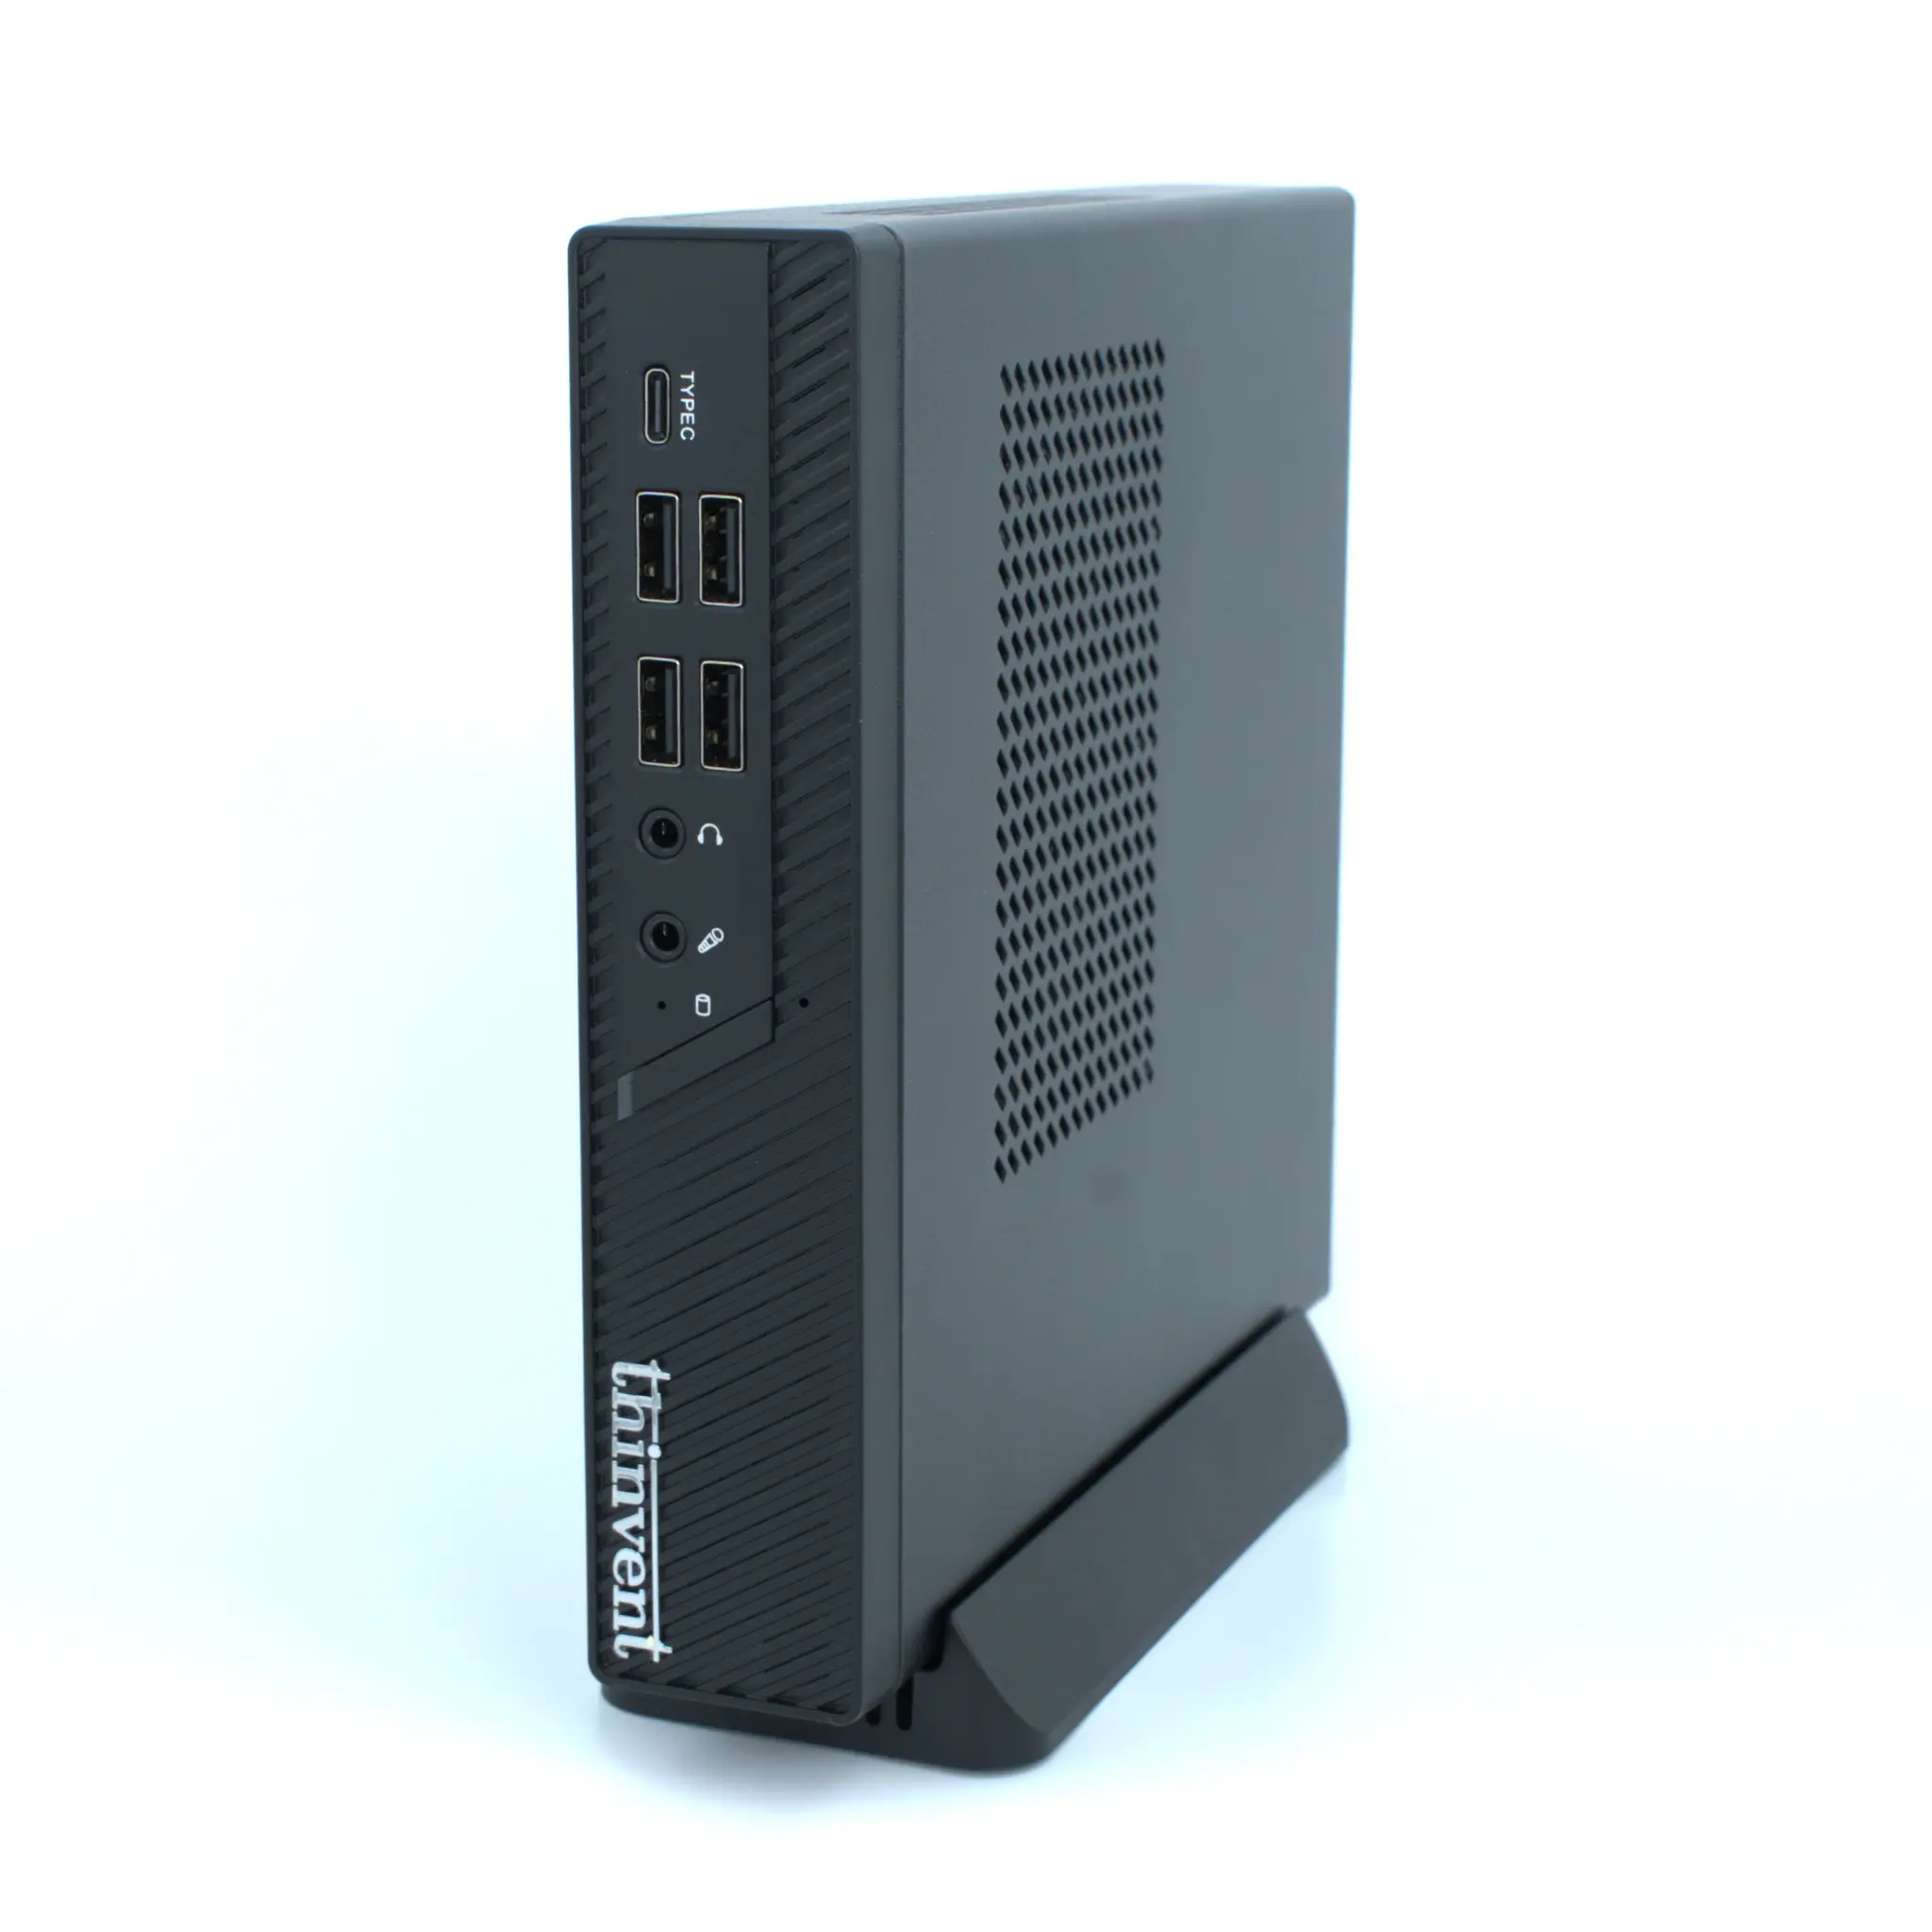
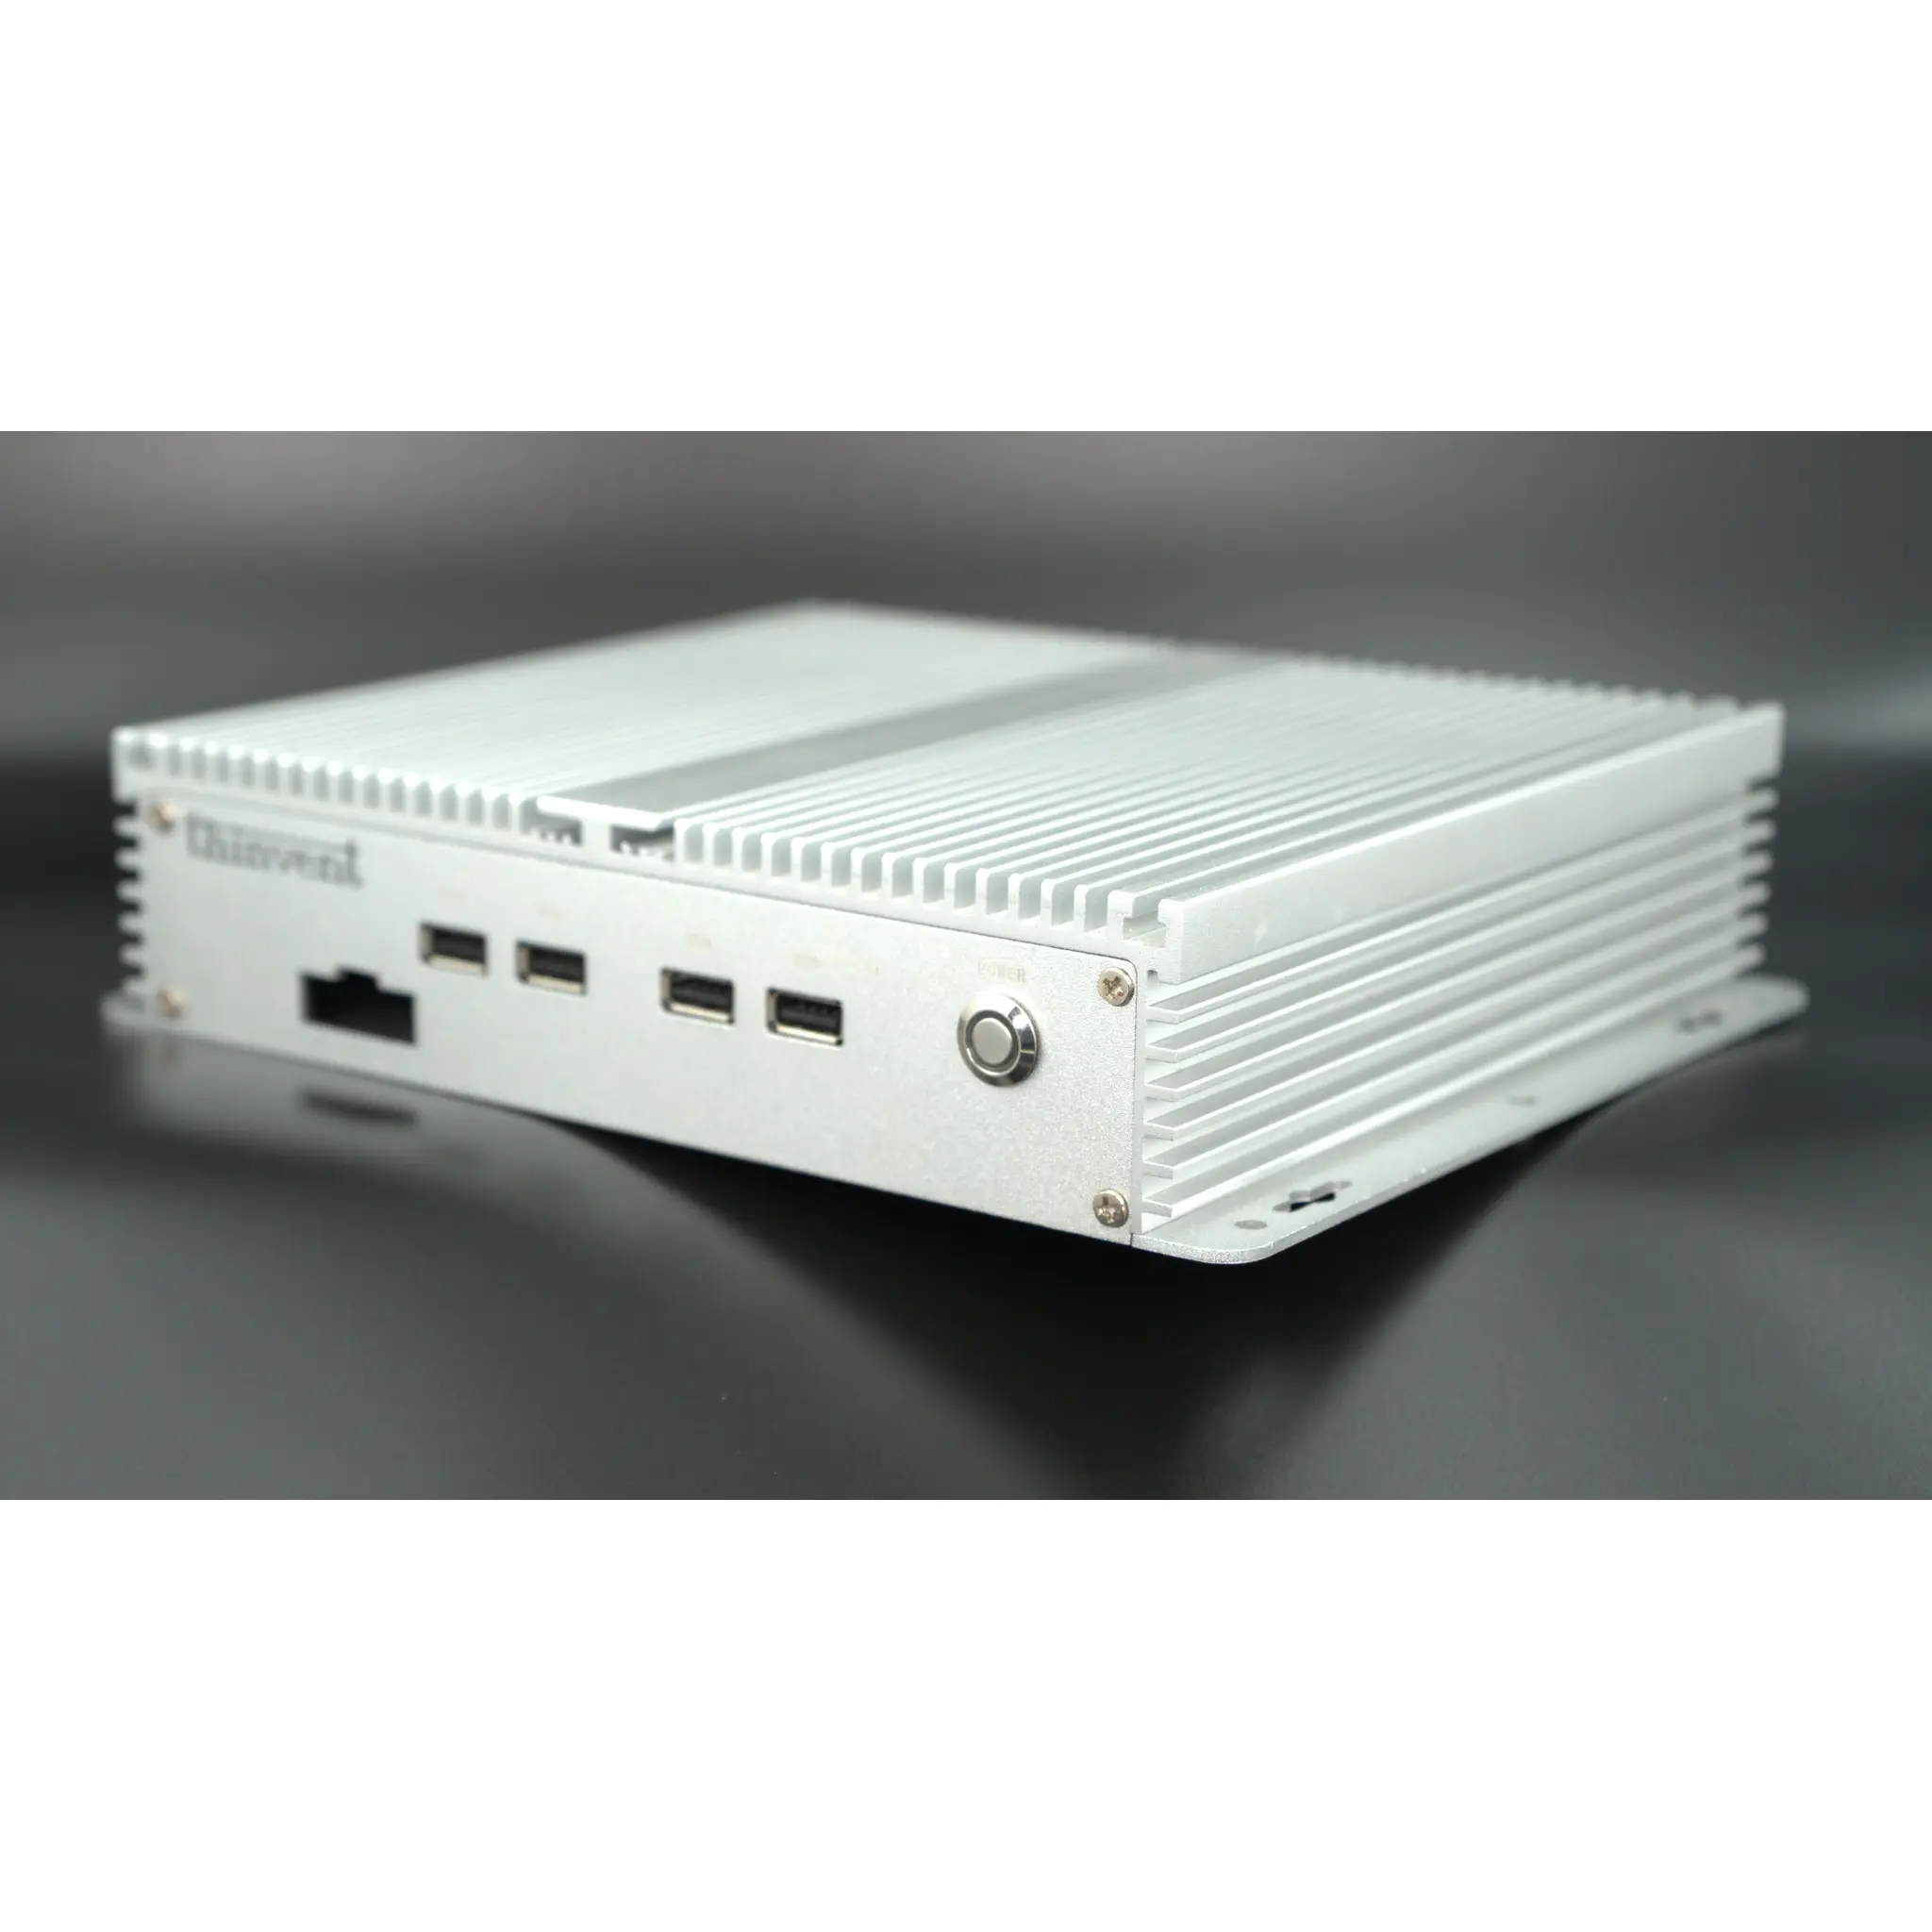
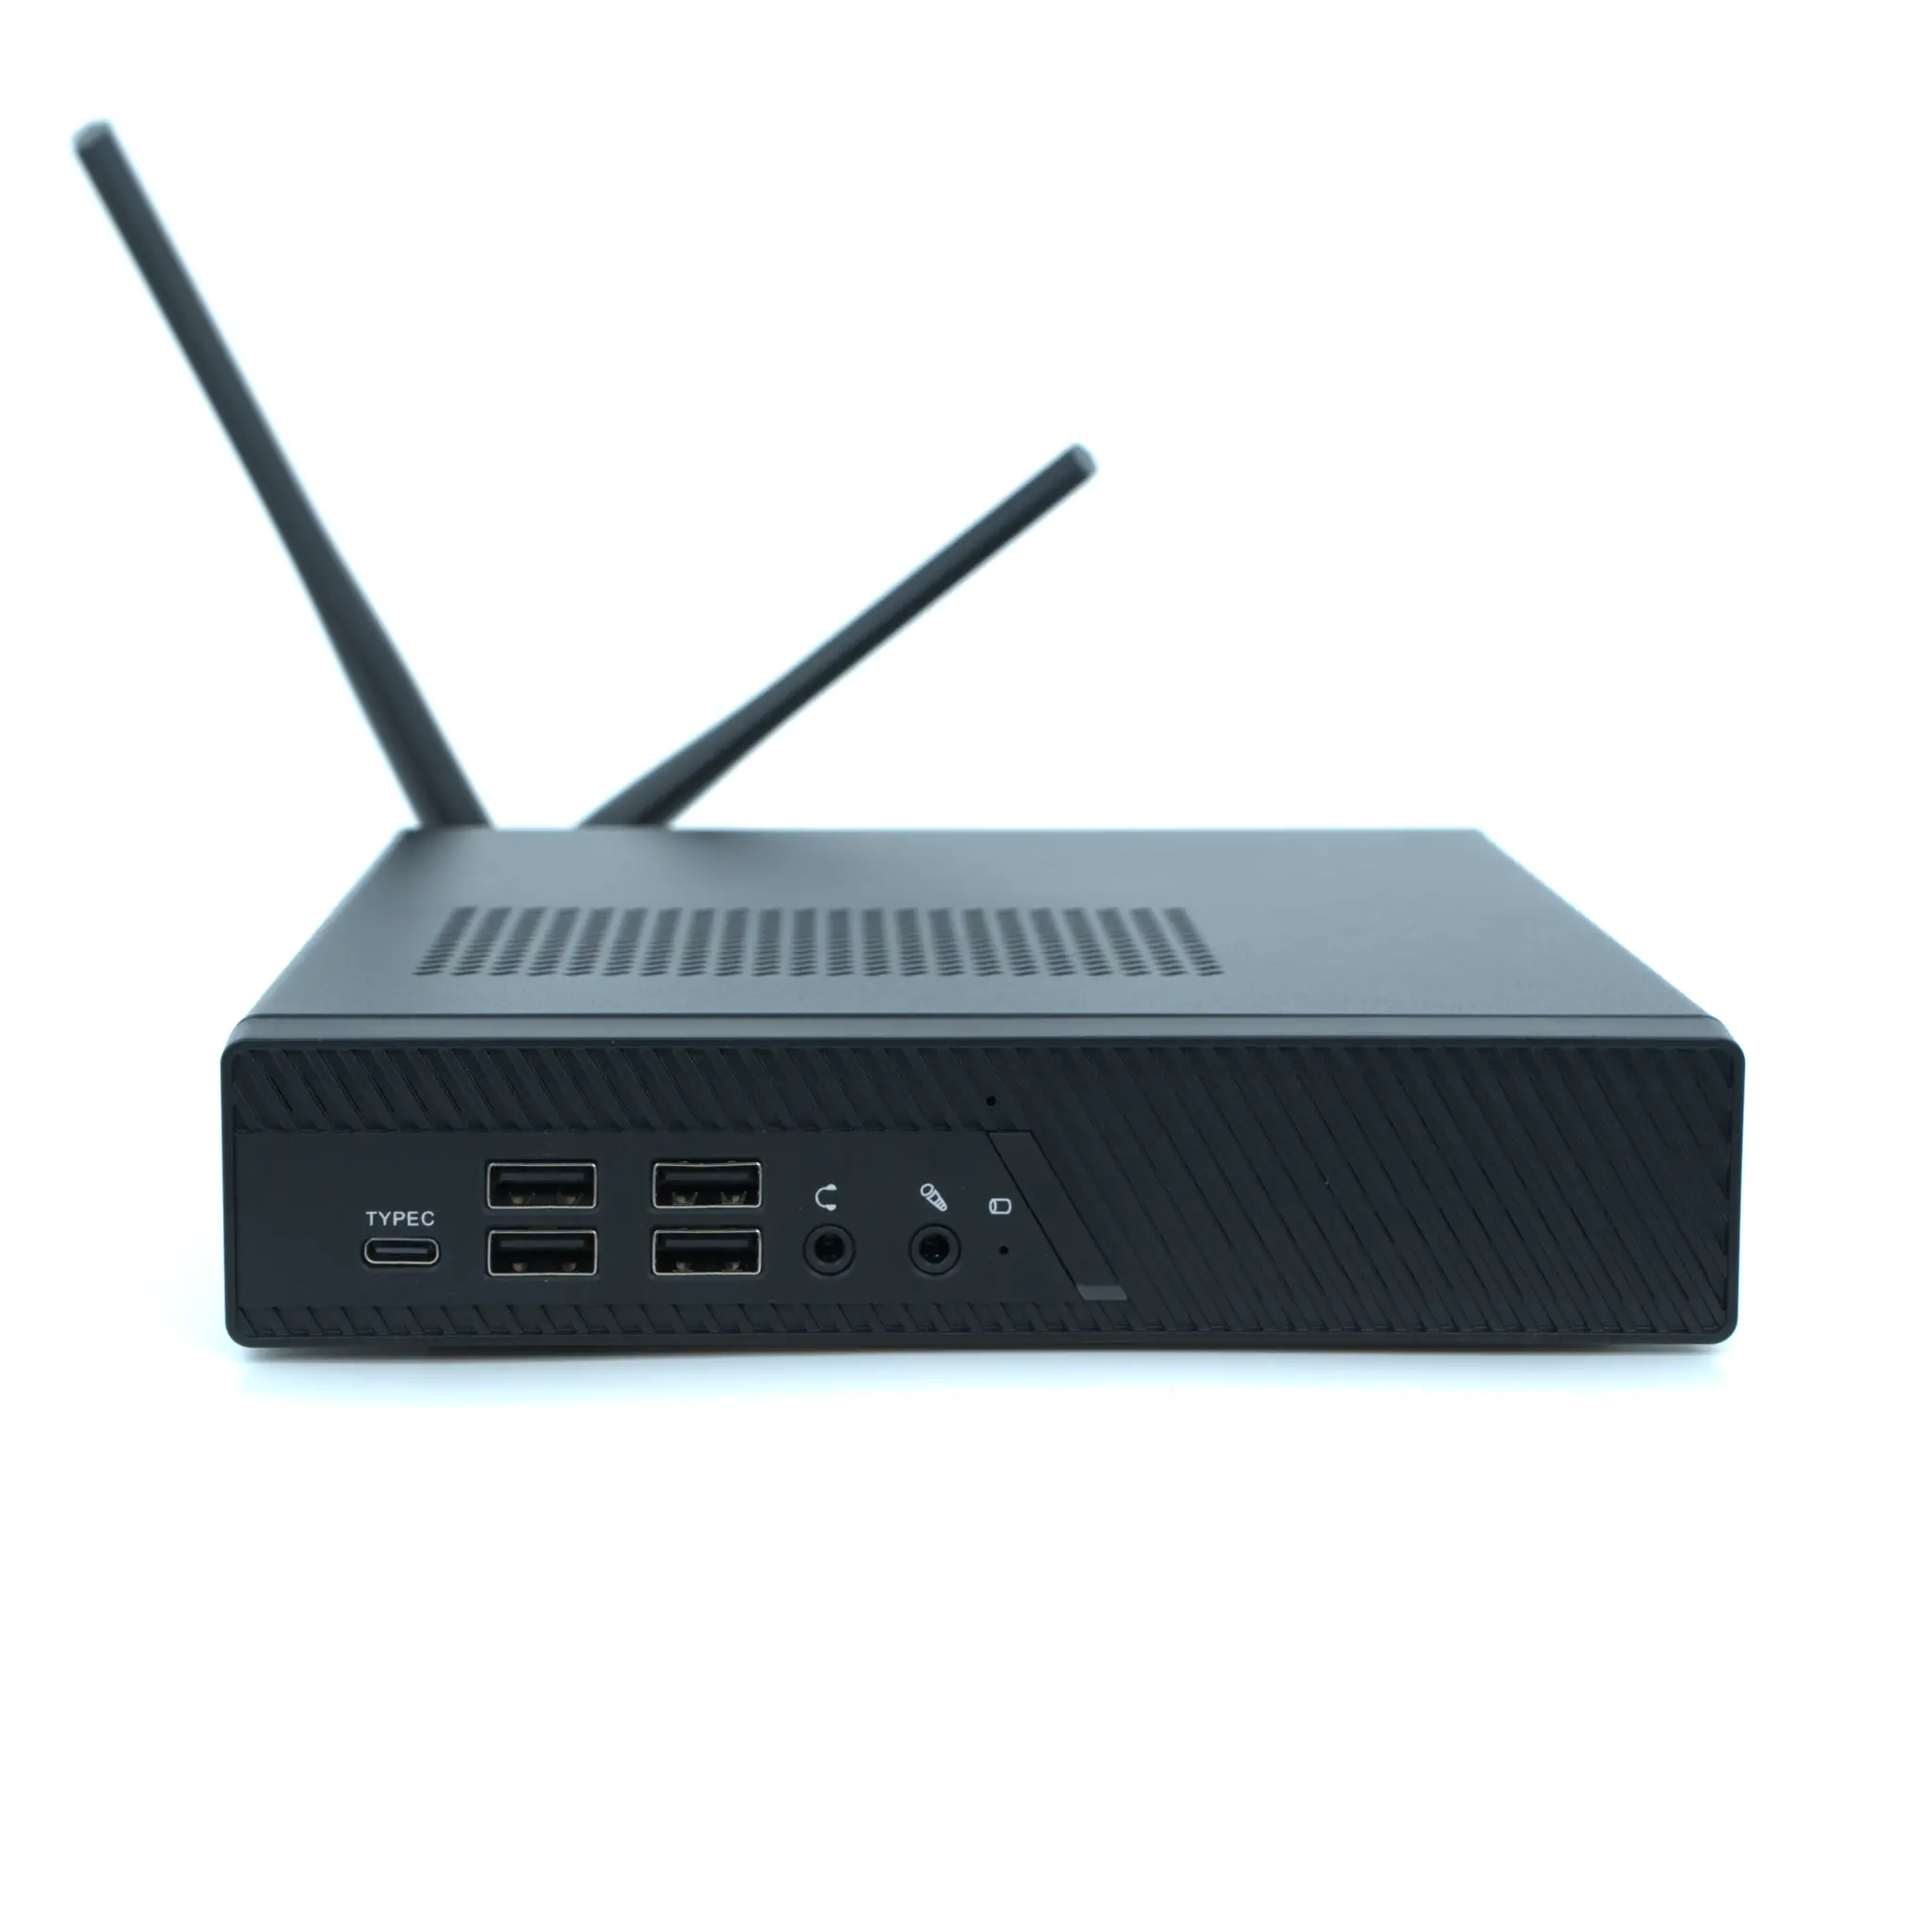
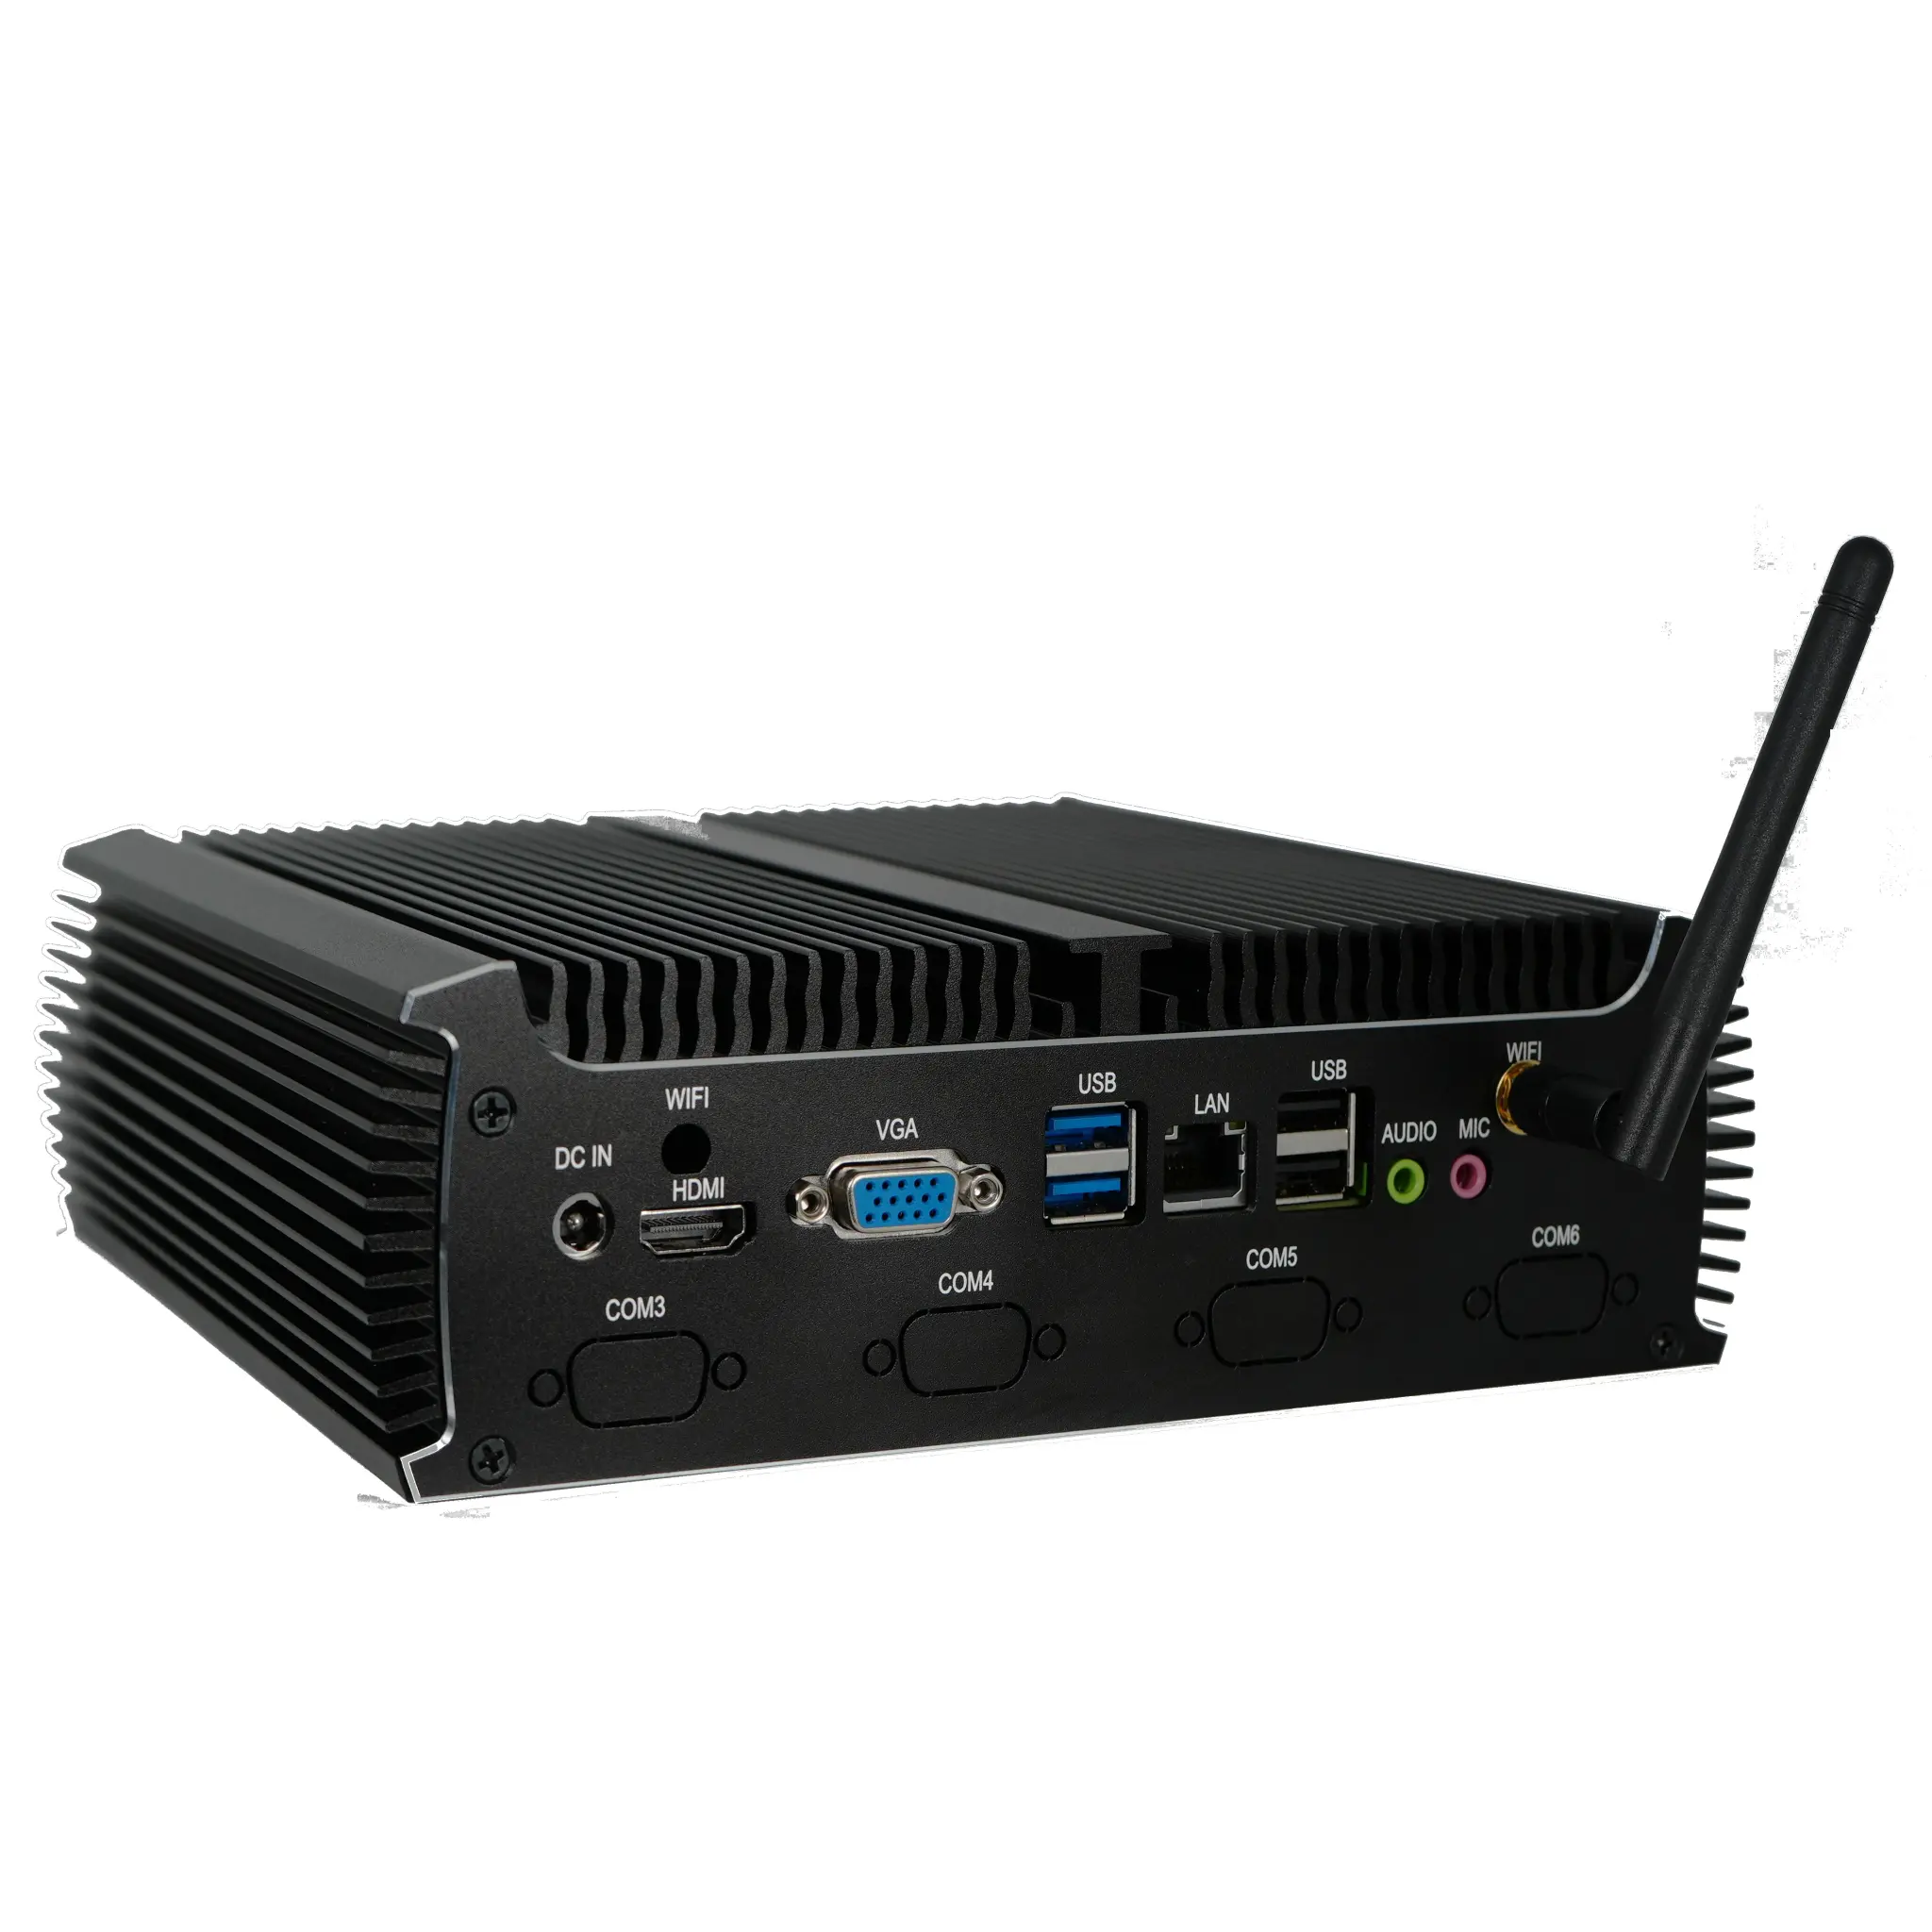
Thinvent builds fanless mini PCs, thin clients, all-in-one computers, and industrial PCs that make dependable hosts for local AI workloads. Configurations with Intel® Core™ i3-1215U processors, 16 GB DDR4 memory, and 1 TB SSDs provide ample headroom for 7B–8B quantised models alongside RAG pipelines and vision tasks, while options for Ubuntu Linux 24.04 LTS, Windows 11 Pro, or no pre-installed OS let you assemble exactly the open source stack you want. Rugged chassis, wide-temperature operation, and dual Ethernet make them equally at home on a desk, in a clinic, or on a production line — keeping your models, and your data, entirely under your control.