What "Open Source AI Models" Means
Open source AI models are neural networks released under licences that let anyone download, inspect, modify and deploy them without paying per-inference fees or sending data to a third party. Well-known families include the Llama, Mistral, Gemma, Phi and Qwen language models, plus task-specific models such as Whisper for speech-to-text, YOLO for object detection and Stable Diffusion for image generation. Because the weights and usually the inference code are public, you can run them on your own hardware — on a desk, in a factory cabinet or inside a vehicle — instead of calling a cloud API.
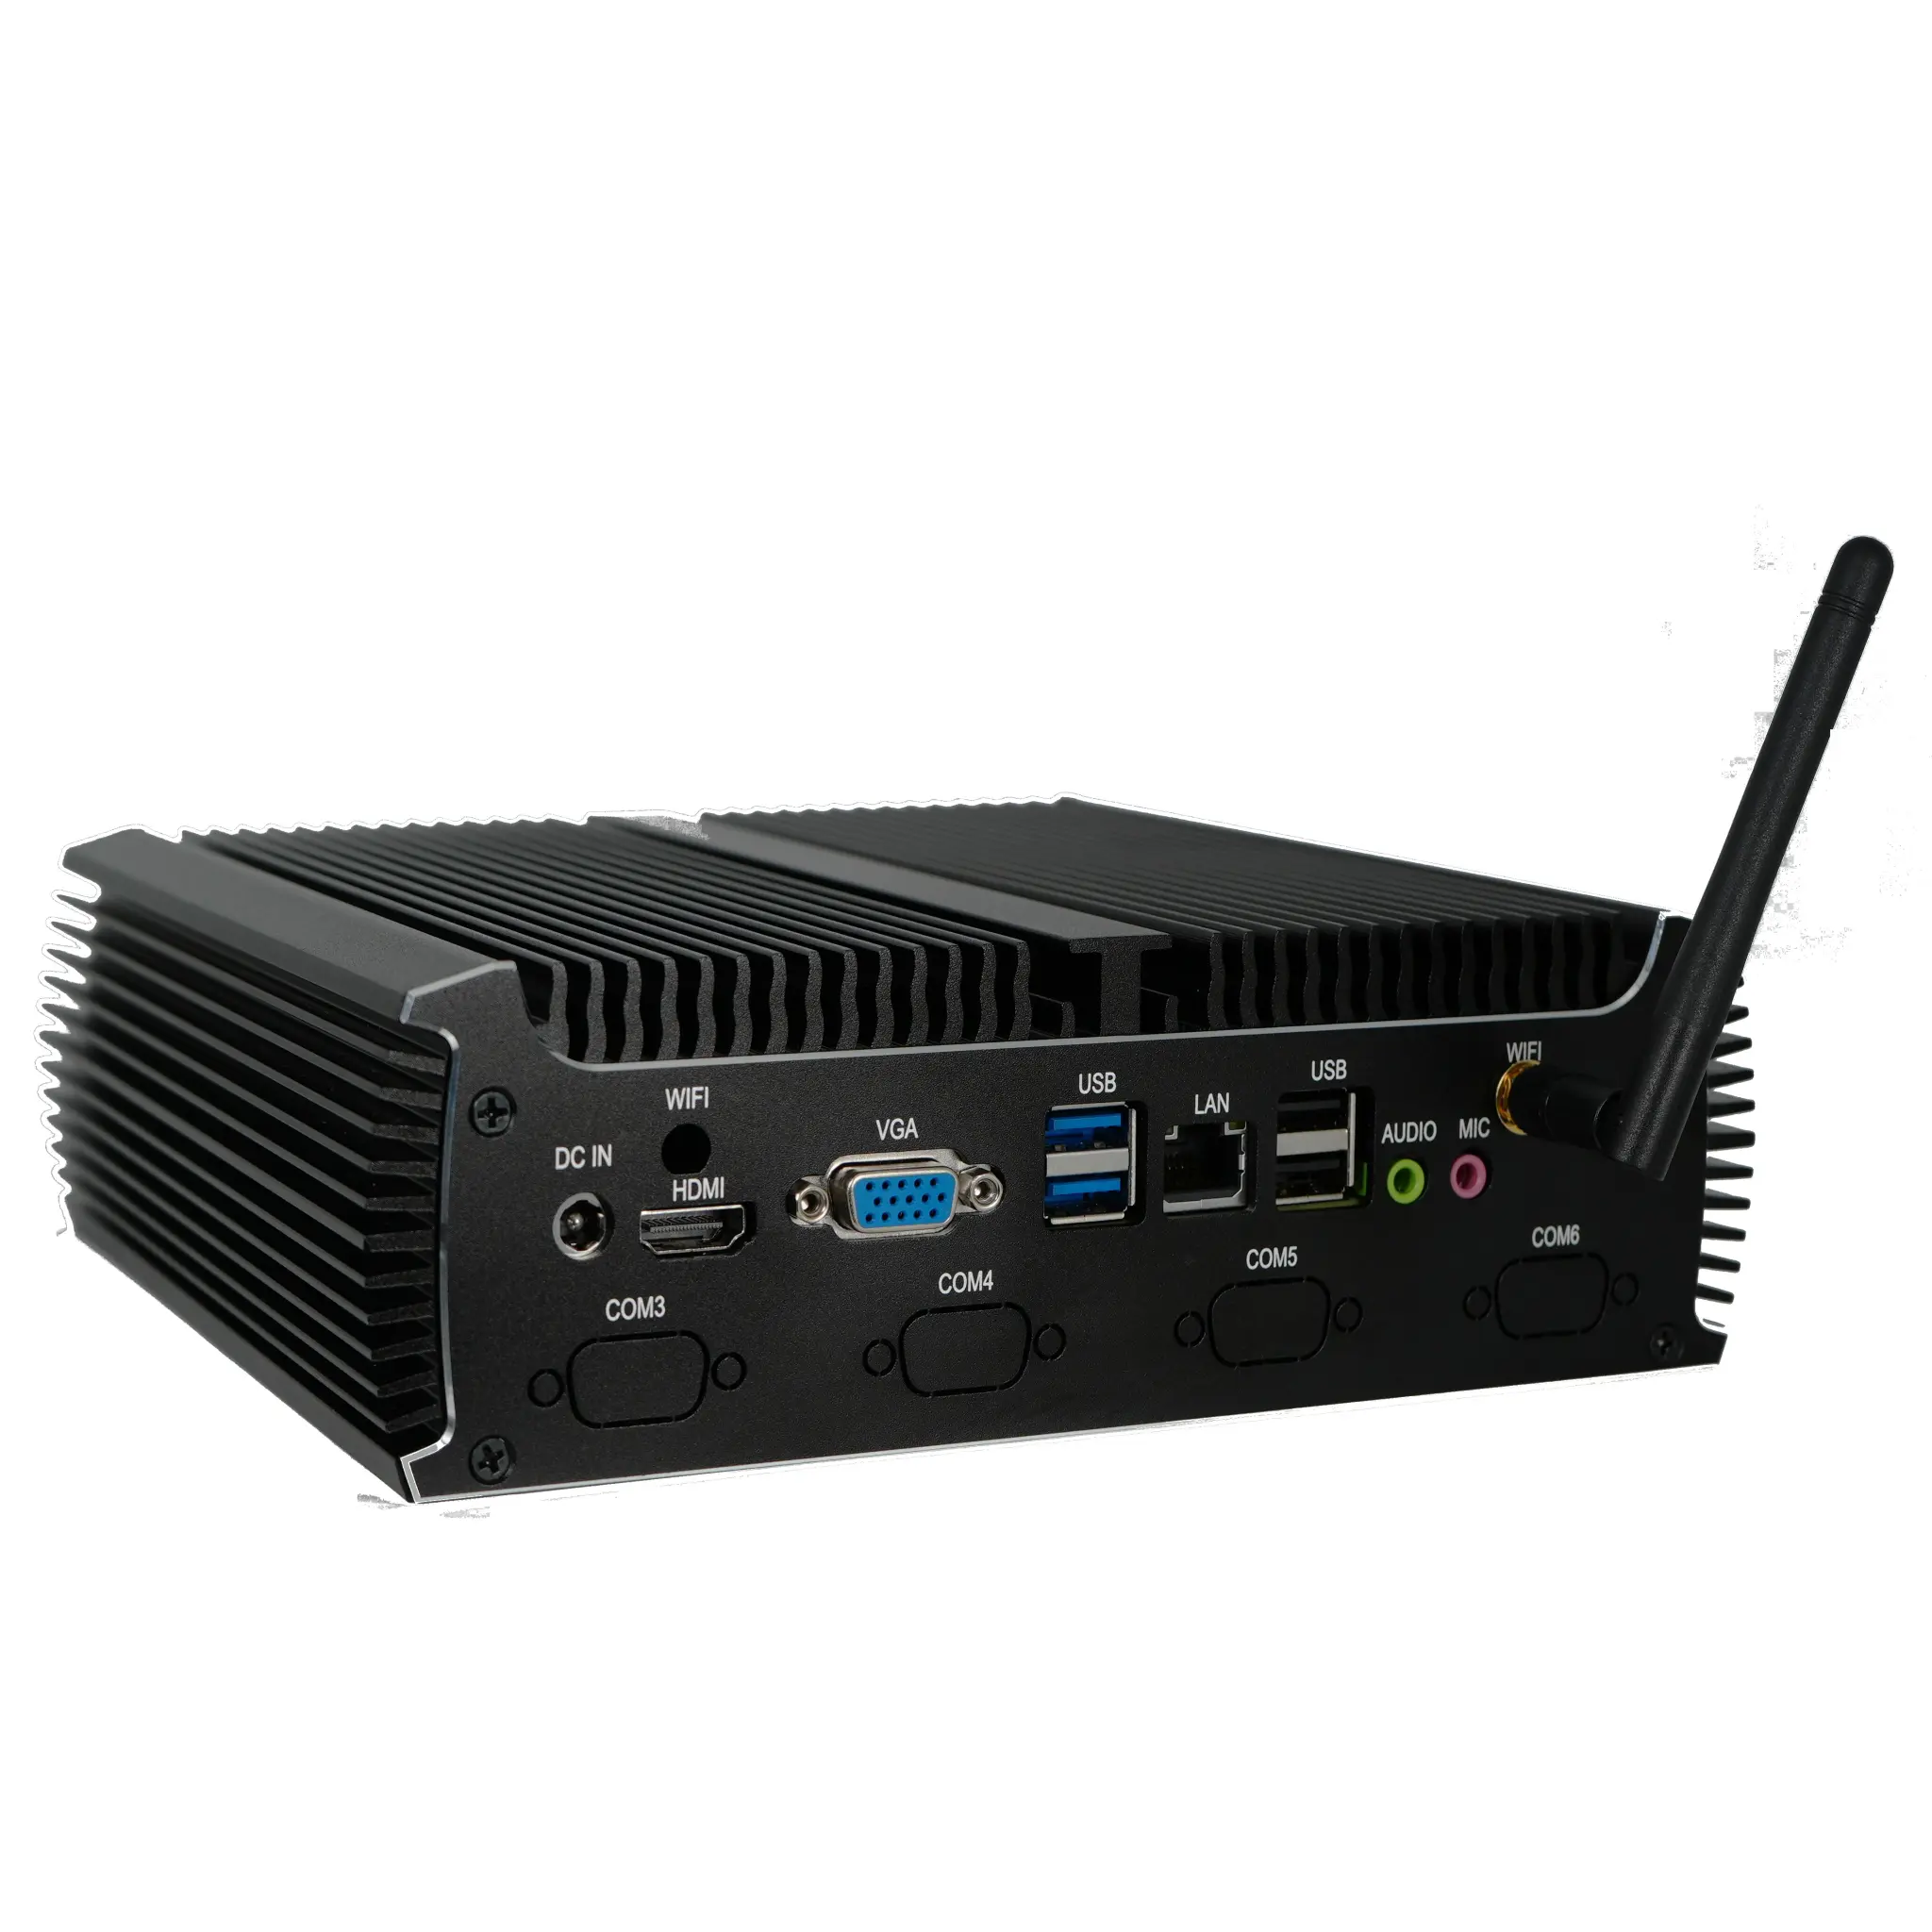
The trade-off is that you supply the compute. That makes the choice of host machine the single biggest decision in an open source AI deployment.
How Models Are Sized and Quantised
Raw model weights are usually published in 16-bit floating point, but almost nobody runs them that way on a CPU. Quantisation compresses weights to 8-bit, 4-bit or lower — the GGUF and GPTQ formats are common — cutting memory use by roughly 2x to 4x with modest accuracy loss. The practical rule of thumb: a quantised model needs about 0.6–0.8 GB of RAM per billion parameters, plus headroom for the context window and the operating system.
| Model size (quantised) | Typical RAM needed | Example use on a CPU host |
|---|---|---|
| 1B– |