What Kind of PC Do You Need for Large Language Model Applications?
A PC for large language model (LLM) applications needs to handle two very different workloads: inference (running a model to generate answers) and local fine-tuning or development. The right machine balances CPU cores, memory capacity, storage speed and — where supported — GPU acceleration, while staying reliable enough to run continuously.
Key Specifications to Consider
| Component | Why It Matters for LLMs | Practical Guidance |
|---|---|---|
| CPU | Token generation and prompt processing are CPU-intensive; more cores help with batching and parallel requests | Modern multi-core Intel® Core™ processors (i3/i5 class, 6–12 cores) handle small-to-mid models and orchestration well |
| RAM | The model, context window and KV cache all live in memory | 16GB is a workable starting point for small quantised models; 32–64GB is better for larger models and concurrent users |
| Storage | Model weights are large files loaded at startup | 512GB–1TB SSD for fast model loading and dataset storage |
| Cooling & Chassis | Sustained inference keeps the CPU busy for long periods | Fanless or industrial-grade designs avoid thermal throttling and dust ingress |
| Networking | API serving, remote clients, model downloads | Dual Gigabit Ethernet for separating management and application traffic |
| OS | Tooling availability | Windows 11 Pro, Ubuntu Linux 24.04 LTS or embedded Linux |
Inference vs. Development Workloads
For edge inference — running a quantised model such as a small Llama, Phi or Mistral variant to answer queries locally — a modern 6-core CPU with 16GB RAM and an SSD is often sufficient, especially when responses are short and the user count is low. These systems are ideal where data must stay on-premises for privacy or latency reasons.
For development, fine-tuning or multi-user serving, you should plan for more memory (32GB+), more storage, and a machine that can sustain high CPU utilisation for hours without throttling. If your workflow depends on GPU acceleration, verify that the platform, power supply and chassis can accommodate the card you intend to use.
Where LLM PCs Are Deployed
-
On-premises AI assistants and chatbots that must not send data to the cloud
-
Industrial and laboratory environments running vision-plus-language pipelines
-
Edge gateways that pre-process data before sending summaries to a larger server
-
Software development workstations for prompt engineering and model evaluation
-
Kiosks and all-in-one terminals with conversational interfaces
Choosing Between Fanless and Actively Cooled Systems
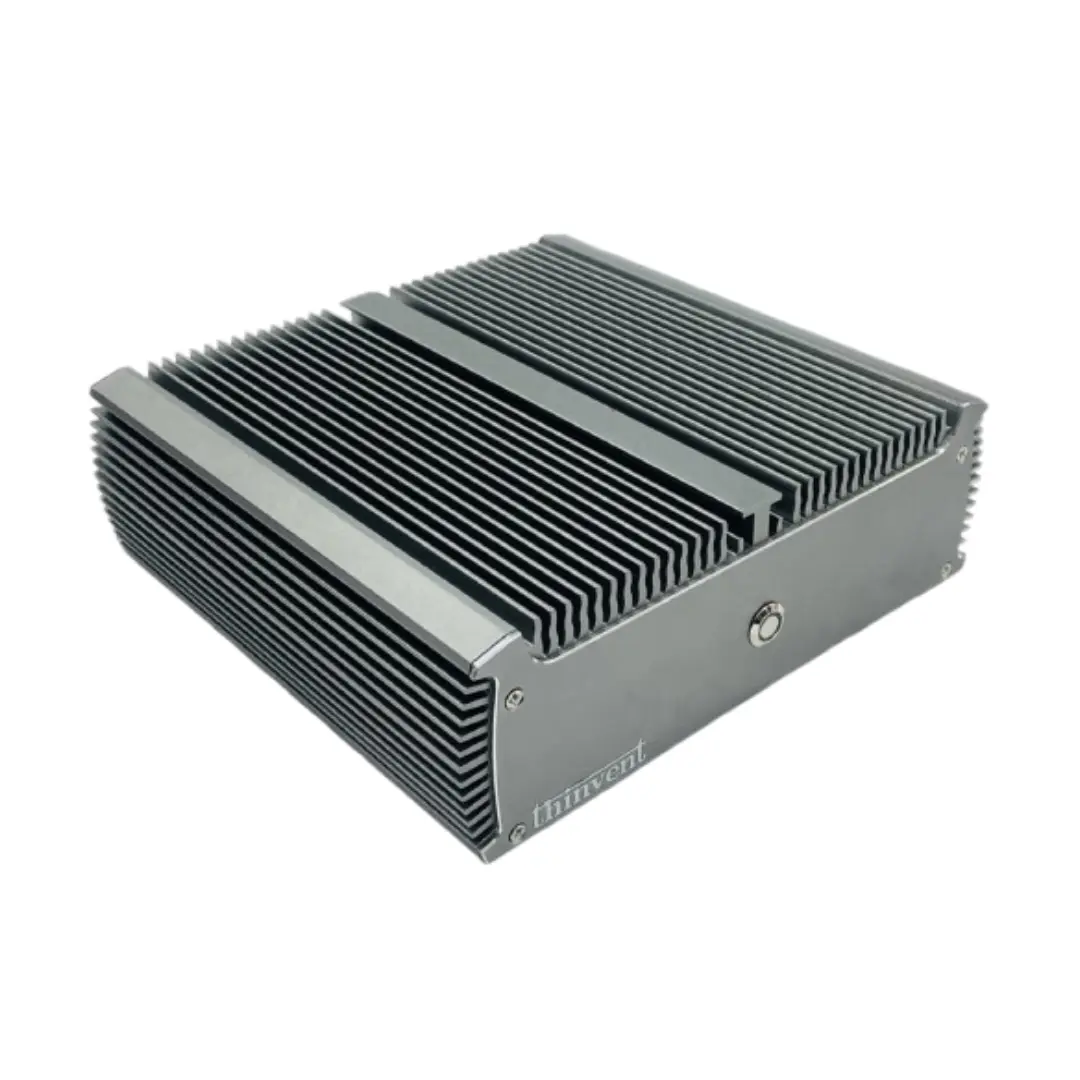
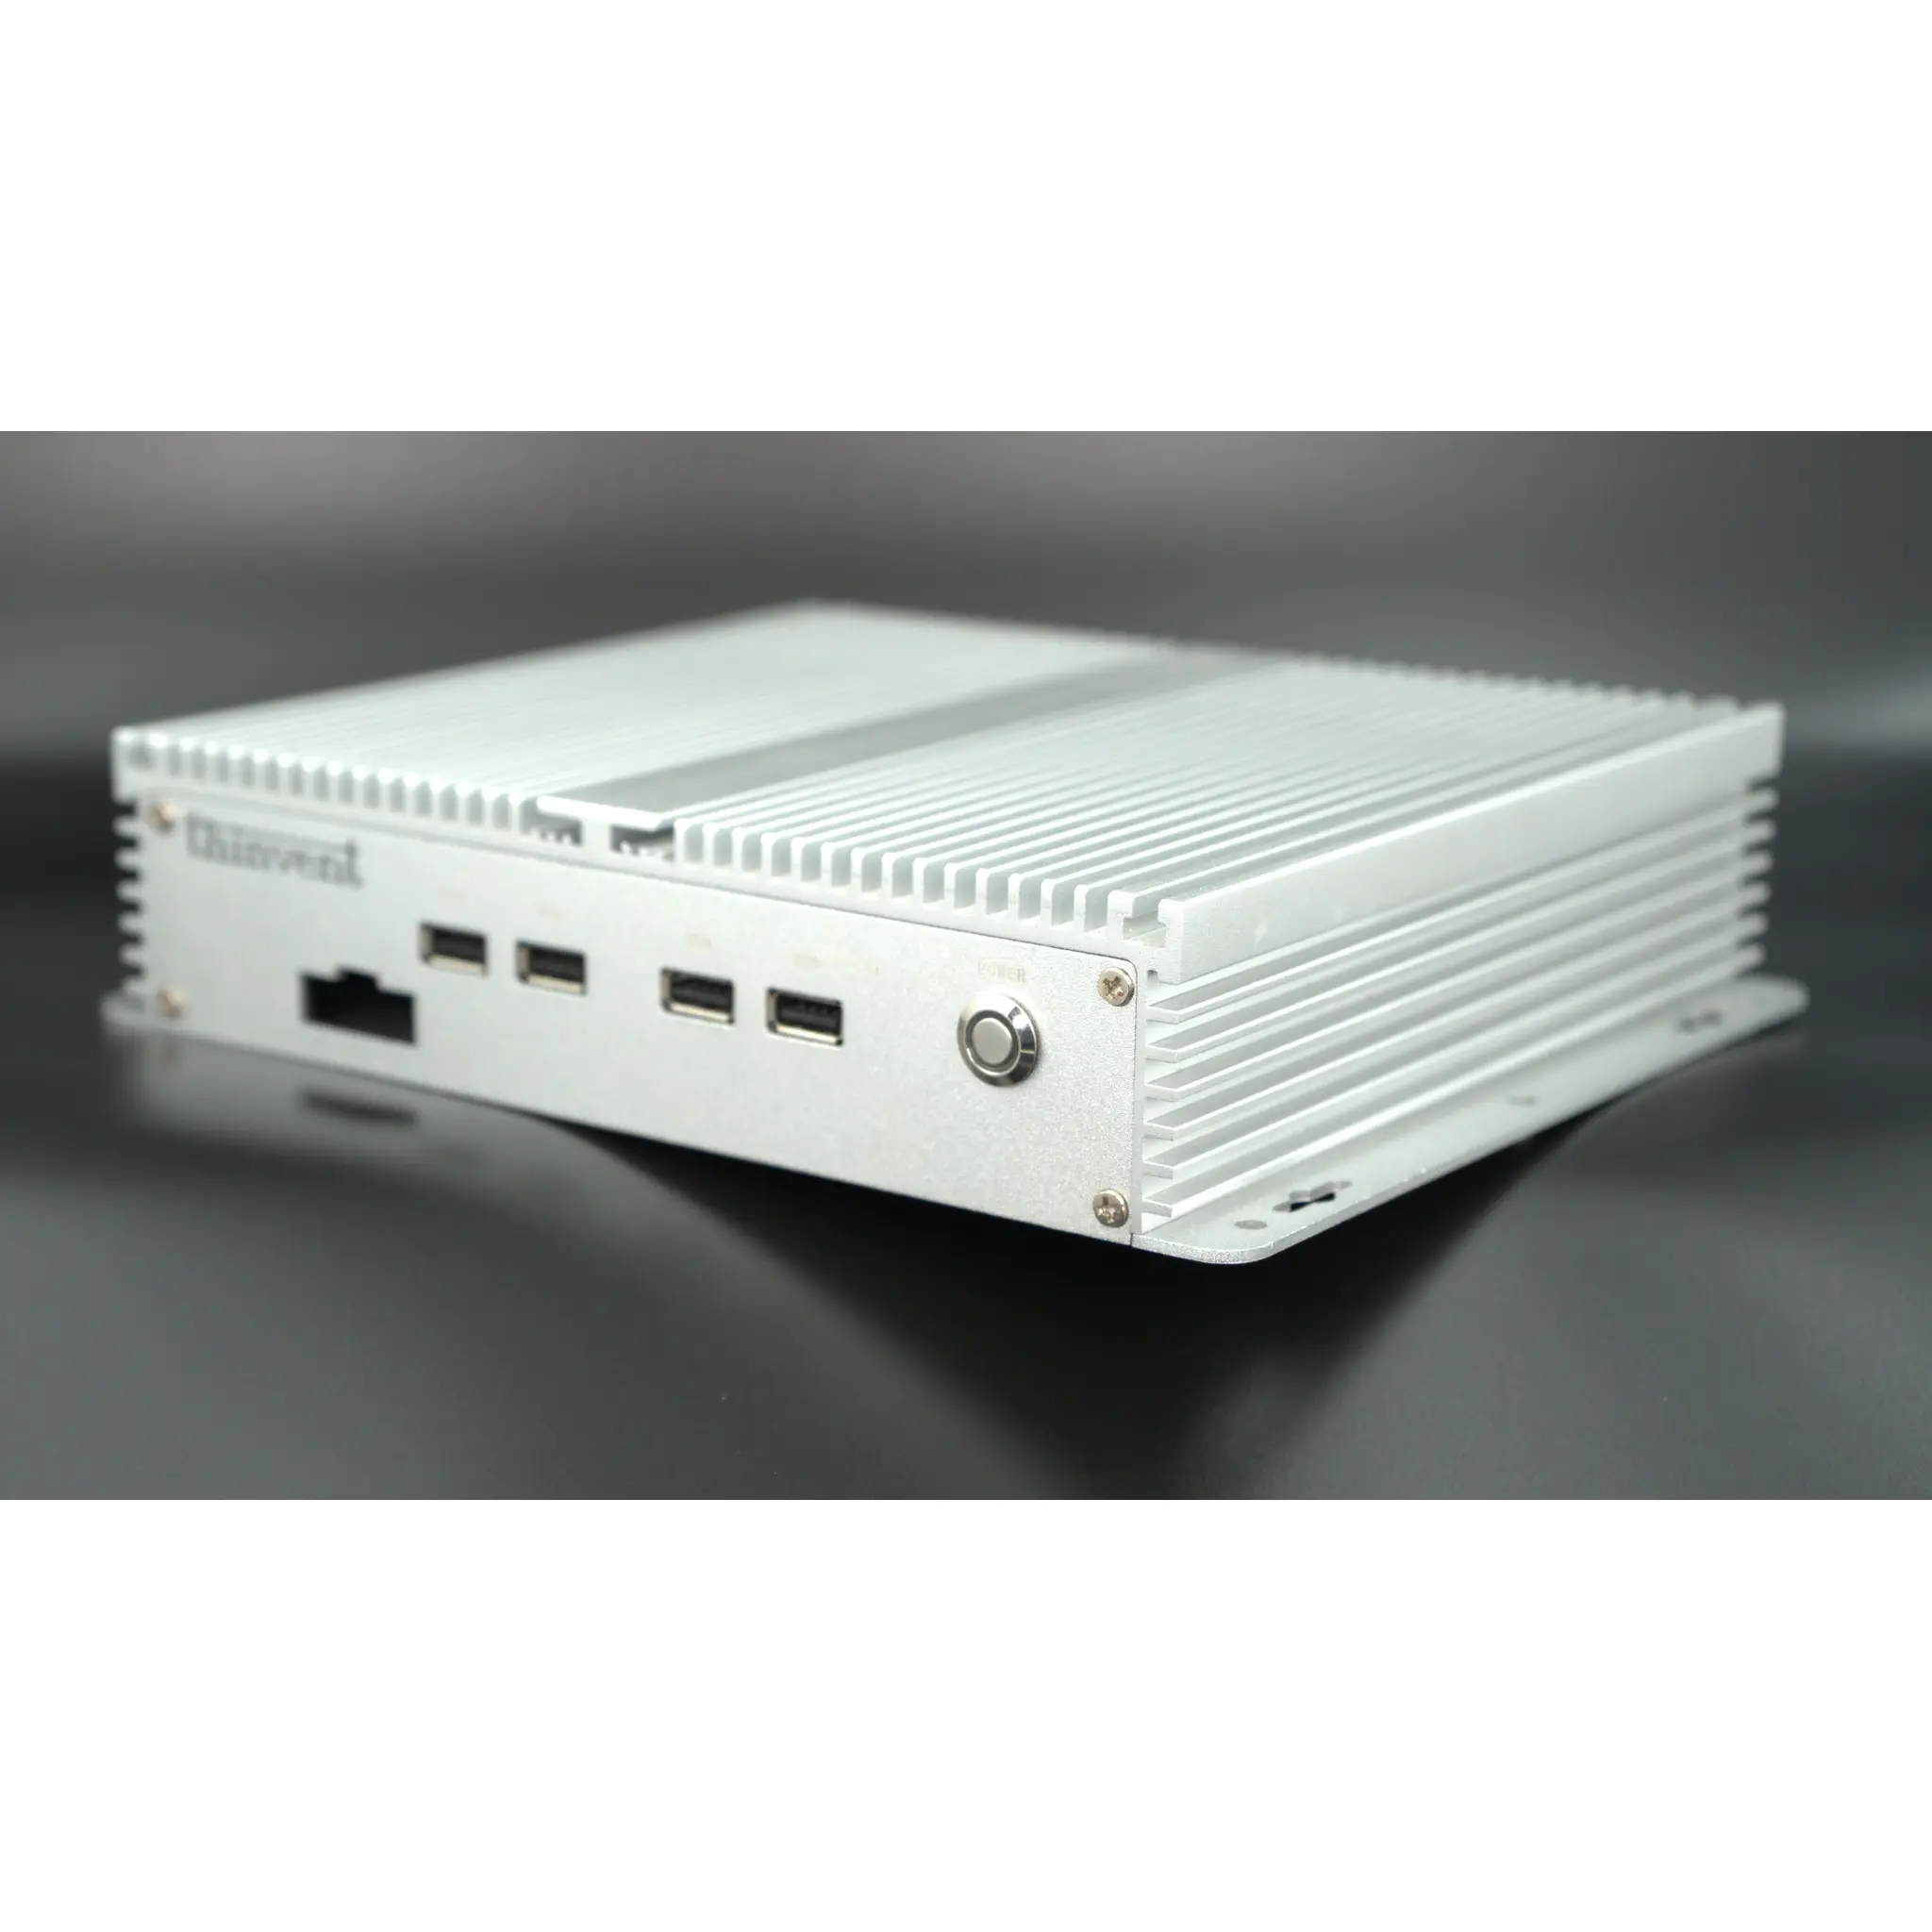
Fanless industrial PCs are a strong fit for LLM edge deployments because they tolerate dust, vibration and wide temperature ranges, and they run quietly in customer-facing locations. The trade-off is thermal headroom: for very long sustained inference at maximum clock speeds, ensure the chassis is rated for the ambient conditions of your site. Actively cooled mini PCs can offer more sustained performance where airflow is available.
Thinvent Products for LLM and AI Workloads
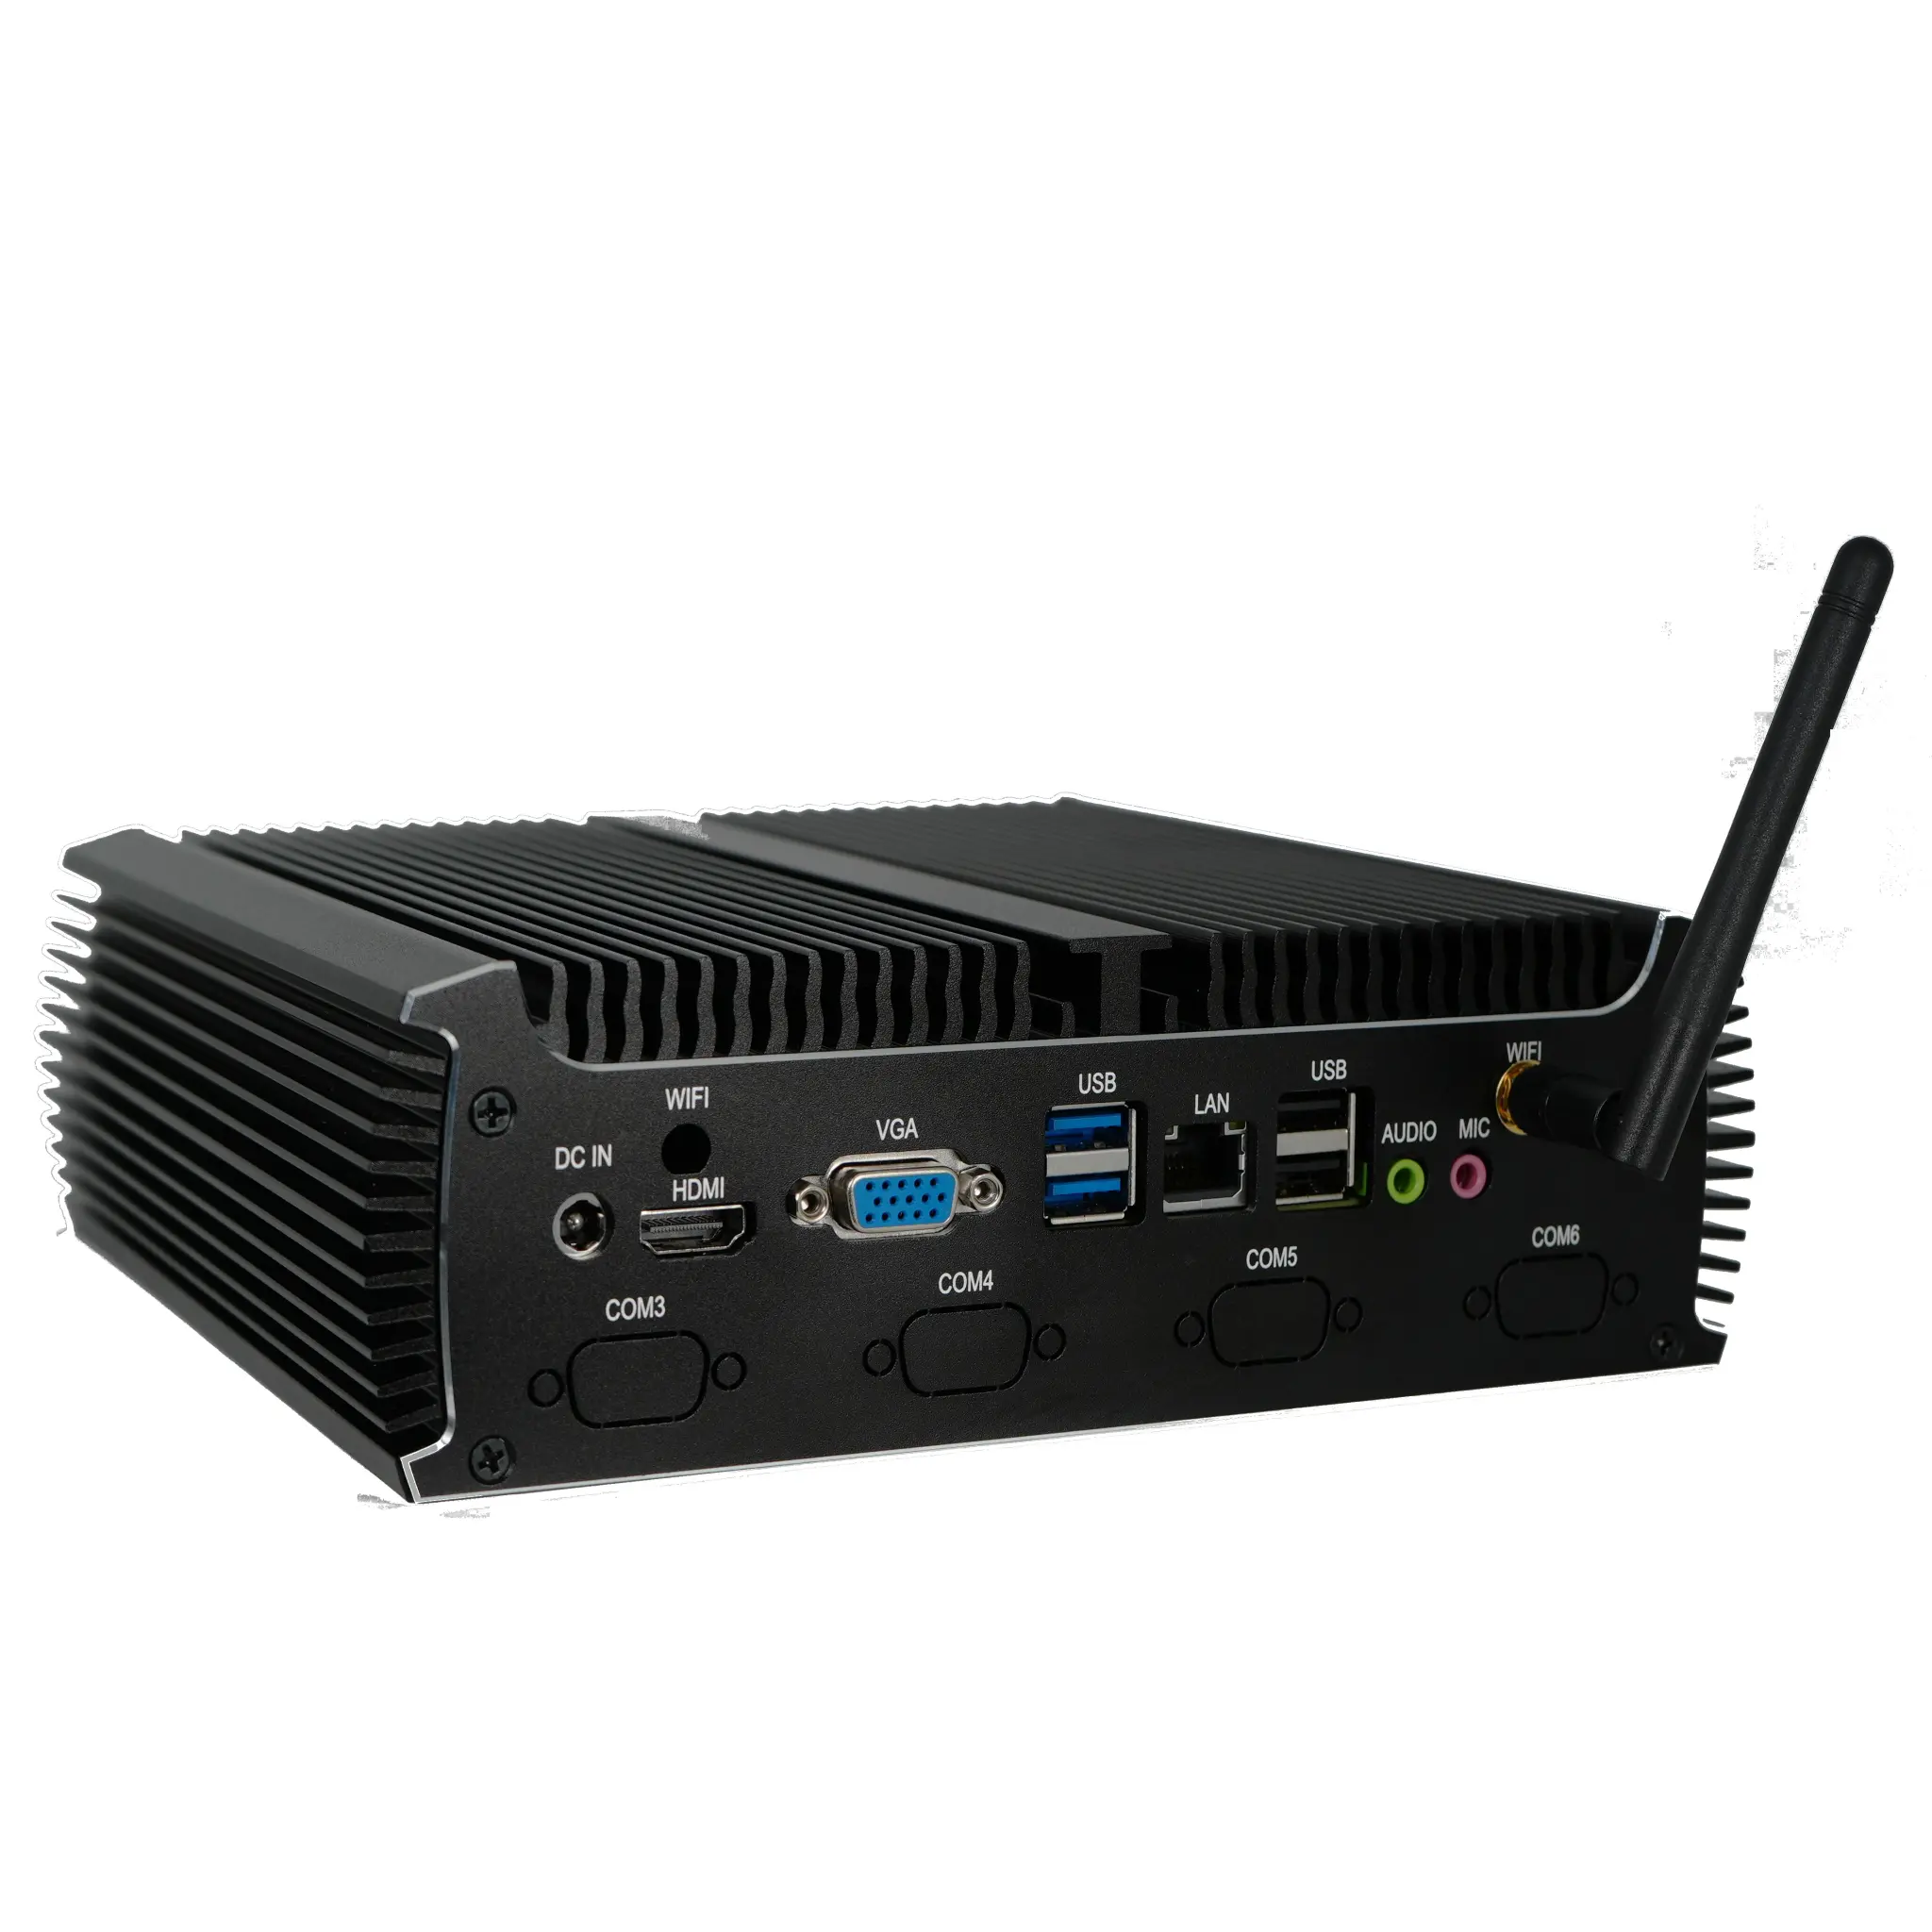
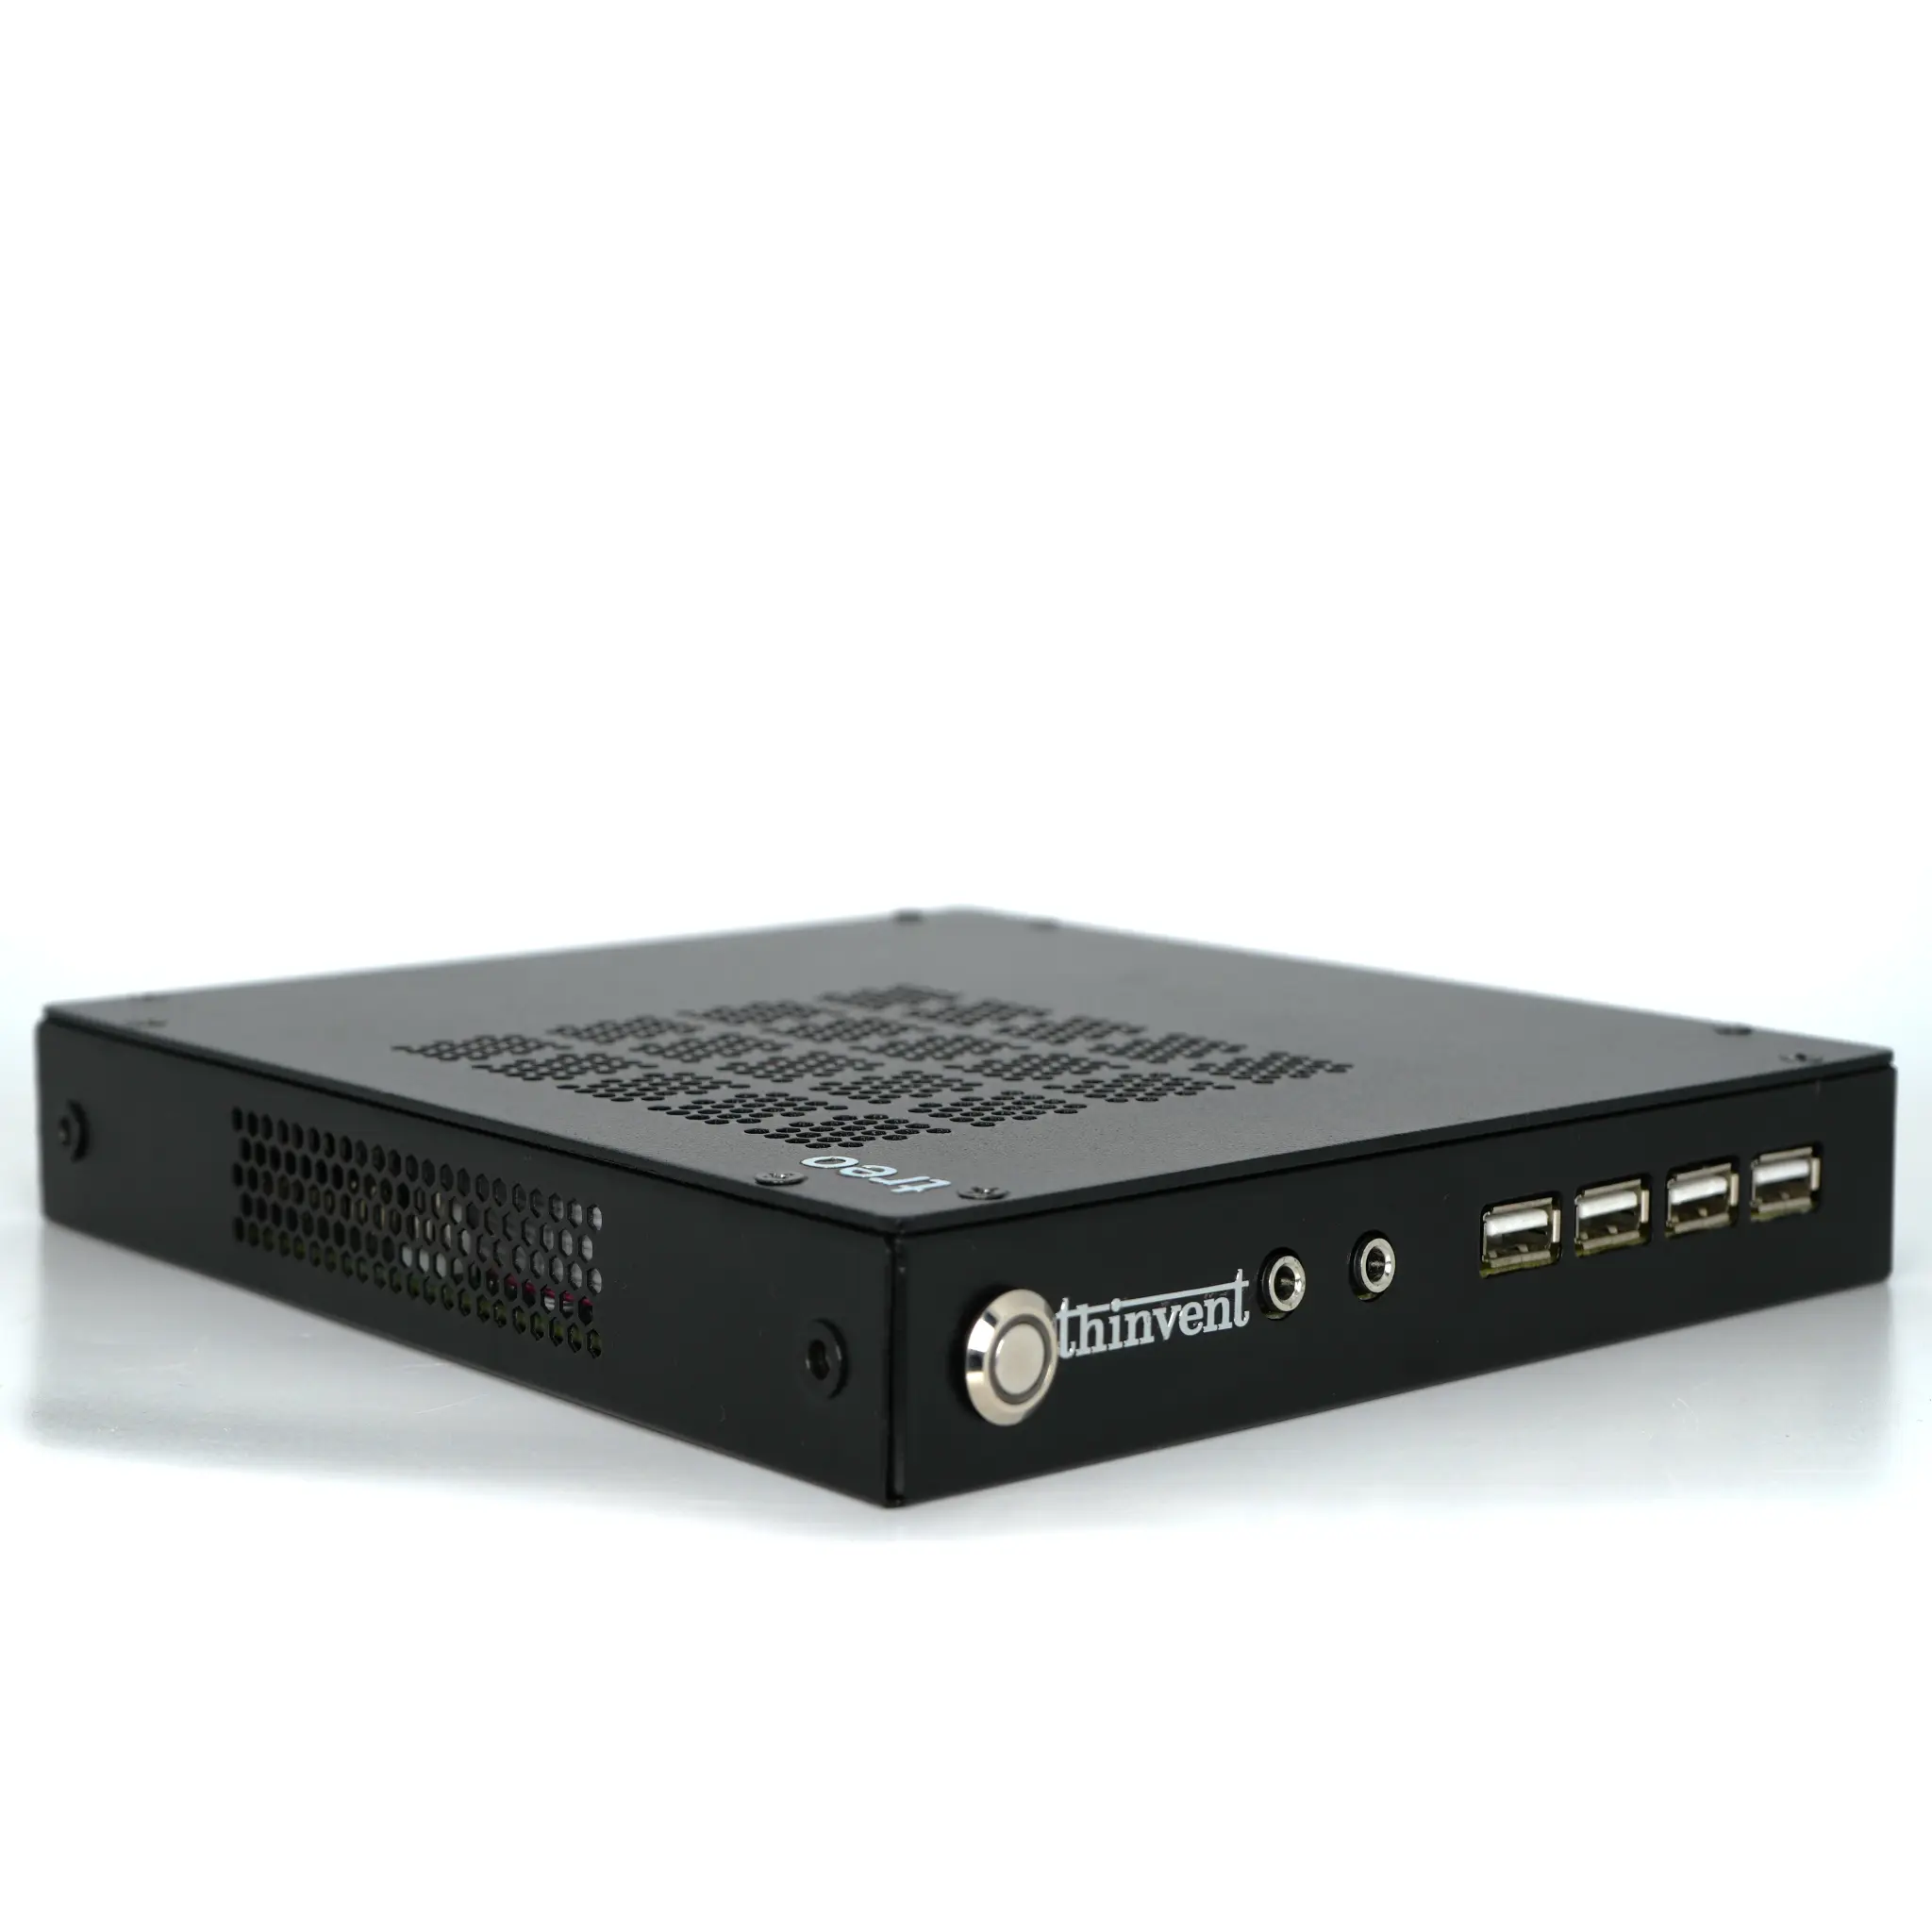
Thinvent builds industrial computers, mini PCs, thin clients and all-in-one PCs suited to AI and LLM edge deployments. Our industrial PC range pairs Intel® Core™ processors — including 12th and 13th generation i3 and i5 options — with up to 64GB memory and 1TB SSD storage, dual Gigabit Ethernet, multiple HDMI outputs and USB-C connectivity. Operating system options include Microsoft Windows 11 Pro, Ubuntu Linux 24.04 LTS, embedded Linux and configurations without an OS, so you can deploy your preferred inference stack. For conversational kiosks and front-desk assistants, our all-in-one PCs with 21.5" and 23.8" screens provide a complete, deployment-ready platform.